Archive for 2022

More thoughts on SPAs

My last post (“The balance has shifted away from SPAs”) attracted a fair amount of controversy, so I’d like to do a follow-up post with some clarifying points.

First off, a definition. In some circles, “SPA” has colloquially come to mean “website with tons of JavaScript,” which brings its own set of detractors, such as folks who just don’t like JavaScript very much. This is not at all what I mean by “SPA.” To me, an SPA is simply a “Single-Page App,” i.e. a website with a client-side router, where every navigation stays on the same HTML page rather than loading a new one. That’s it.

It has nothing to do with the programming model, or whether it “feels” like you’re coding a Single-Page App. By my definition, Turbolinks is an SPA framework, even if, as a framework user, you never have to dirty your hands touching any JavaScript. If it has a client-side router, it’s an SPA.

Second, the point of my post wasn’t to bury SPAs and dance on their grave. I think SPAs are great, I’ve worked on many of them, and I think they have a bright future ahead of them. My main point was: if the only reason you’re using an SPA is because “it makes navigations faster,” then maybe it’s time to re-evaluate that.

Jake Archibald already showed way back in 2016 that SPA navigations are not faster when the page is loading lots of HTML, because the browser’s streaming HTML parser can paint above-the-fold content faster than it takes for the SPA to download the full-fat JSON (or HTML) and manually inject it into the DOM. (Unless you’re doing some nasty hacks, which you probably aren’t.) In his example, GitHub would be better off just doing a classic server round-trip to fetch new HTML than a fancy Turbolinks SPA navigation.

That said, my post did generate some thoughtful comments and feedback, and it got me thinking about whether there are other reasons for SPAs’ recent decline in popularity, and why SPAs could still remain an attractive choice in the future for certain types of websites.

Core Web Vitals

In 2020, Google announced that the Core Web Vitals would become a factor in search page rankings. I think it’s fair to say that this sent shockwaves through the industry, and caused folks who hadn’t previously taken performance very seriously to start paying close attention to their site speed scores.

It’s important to notice that the Core Web Vitals are very focused on page load. LCP (Largest Contentful Paint) and FID (First Input Delay) both apply only to the user experience during the initial navigation. (CLS, or Cumulative Layout Shift, applies to the initial navigation and beyond; see note below.) This makes sense for Google: they don’t really care how fast your site is after that initial page load; they mostly just care about the experience of clicking a link in Google and loading the subsequent page.

Regardless of whether these metrics are an accurate proxy for the user experience, they are heavily biased against SPAs. The whole value proposition of SPAs (from a performance perspective at least) is that you pay a large upfront cost in exchange for faster subsequent interactions (that’s the theory anyway). With these metrics, Google is penalizing SPAs if they render client-side (LCP), load a lot of JavaScript (FID), or render content progressively on the client side (CLS).

A classic MPA (Multi-Page App) with a dead-simple HTML file and no JavaScript will score very highly on Core Web Vitals. Miško Hevery, the creator of Qwik, has explicitly mentioned Core Web Vitals as an influence on how he designed his framework. Especially for websites that are very sensitive to SEO scores, such as e-commerce sites, the Core Web Vitals are pushing developers away from SPAs.

Code caching

This was something I forgot to mention in my post, probably because it happened long enough ago that it couldn’t possibly have had an impact on the recent uptick in MPA interest. But it’s worth calling out.

When you navigate between pages in an MPA, the browser is smart enough not to parse and compile the same JavaScript over and over again. Chrome does it, Firefox does it, Safari does it. All modern browsers have some variation on this. (Legacy Edge and IE, may they rest in peace, did not have this.) Incidentally, this optimization also exists for stylesheet parsing (WebKit bug from 2012, Firefox bug, demo).

So if you have the same shared JavaScript and CSS on multiple MPA pages, it’s not a big deal in terms of subsequent navigations. At worst, you’re asking the browser to re-parse and re-render your HTML, re-run style and layout calculation (which would happen in an SPA anyway, although to a lesser degree thanks to techniques like invalidation sets), and re-run JavaScript execution. (In a well-built MPA, though, you should not have much JavaScript on each page.)

Throw in paint holding and the back-forward cache (as discussed in my previous post), as well as the streaming HTML mentioned above, and you can see why the value proposition of “SPA navigations are fast” is not so true anymore. (Maybe it’s true in certain cases, e.g. where the DOM being updated is very small. But is it so much faster that it’s worth the added complexity of a client-side router?)

Service Worker and offline MPAs

One interesting response to my post was, “I like SPAs because they preserve privacy, and keep all the user data client-side. My site can just be static files.” This is a great point, and it’s actually one of the reasons I wrote my Mastodon client, Pinafore, as an SPA.

But as I mentioned in my post, there’s nothing inherent about the SPA architecture that makes it the only option for handling user data purely on the client side. You could make a fully offline-powered MPA that relies on the Service Worker to handle all the rendering. (Here is an example implementation I found.)

I admit though, that this was one of the weaker arguments in my post, because as far as I can tell… nobody is actually doing this. Most frameworks I’m aware of that generate a Service Worker also generate a client-side router. The Service Worker is an enhancement, but it’s not the main character in the story. (If you know a counter-example, though, then please let me know!)

I think this is actually a very under-explored space in web development. I was pitching this Service-Worker-first architecture back in 2016. I’m still hopeful that some framework will start exploring this idea eventually – the recent focus on frameworks supporting server-side JavaScript environments beyond Node (such as Cloudflare Workers) should in theory make this easier, because the Service Worker is a similarly-constrained JavaScript environment. If a framework can render from inside a Cloudflare Worker, then why not a Service Worker?

This architecture would have a lot of upsides:

  1. No client-side router, so no need to implement focus management, scroll restoration, etc.
  2. You’d also still get the benefits of paint holding and the back-forward cache.
  3. If you open multiple browser tabs pointing to the same origin, each page will avoid the full-SPA JavaScript load, since the main app logic has already been bootstrapped in the Service Worker. (One Service Worker serves multiple tabs for the same origin.)
  4. The Service Worker can use ReadableStreams to get the benefits of the browser’s progressive HTML parser, as described above.
  5. Memory leaks? I’ve harped on this a lot in the past, and admittedly, this wouldn’t fully solve the problem. You’d probably just move the leaks into the Service Worker. But a Service Worker has a fire-and-forget model, so the browser could easily terminate it and restart it if it uses up too much memory, and the user might never notice.

This architecture does have some downsides, though:

  1. State is spread out between the Service Worker and the main thread, with asynchronous postMessage required for communication.
  2. You’d be limited to using IndexedDB and caches to store persistent state, since you’d need something accessible to the Service Worker – no more synchronous LocalStorage.
  3. In general, the simplified app development model of an SPA (all state is stored in one place, on the main thread, available synchronously) would be thrown out the window.
  4. No framework that I’m aware of is doing this.

I still think the performance and simplicity upsides of this model are worth at least prototyping, but again, it remains to be seen if the DX (Developer Experience) is seamless enough to make it viable in practice.

The virtues of SPAs

So given everything I’ve said about SPAs – paint holding, the back-forward cache, Core Web Vitals – why might you still want to build an SPA in 2022? Well, to give a somewhat hand-wavy answer, I think there are a lot of cases where an SPA is a good choice:

  1. You’re building an app where the holotype matches the right use case for an SPA – e.g. only one browser tab is ever open at a time, page loads are infrequent, content is very dynamic, etc.
  2. Core Web Vitals and SEO are not a big concern for you, e.g. because your app is behind a login gate.
  3. There’s a feature you need that’s only available in SPAs (e.g. an omnipresent video player, as mentioned in the previous post).
  4. Your team is already productive building an SPA, because that’s what your favorite framework supports.
  5. You just like SPAs! That’s fine! I’m not going to take them away from you, I promise.

That said, my goal with the previous post was to start a conversation challenging some of the assumptions that folks have about SPAs. (E.g. “SPA navigations are always faster.”) Oftentimes in the tech industry we do things just because “that’s how things have always been done,” and we don’t stop to consider if the conditions that drove our previous decisions have changed.

The only constant in software is change. Browsers have changed a lot over the years, but in many ways our habits as web developers have not really adjusted to fit the new reality. There’s a lot of prototyping and research yet to be done, and the one thing I’m sure of is that the best web apps in 10 years will look a lot different from the best web apps built today.

Next post: State is hard: why SPAs will persist

The balance has shifted away from SPAs

There’s a feeling in the air. A zeitgeist. SPAs are no longer the cool kids they once were 10 years ago.

Hip new frameworks like Astro, Qwik, and Elder.js are touting their MPA capabilities with “0kB JavaScript by default.” Blog posts are making the rounds listing all the challenges with SPAs: history, focus management, scroll restoration, Cmd/Ctrl-click, memory leaks, etc. Gleeful potshots are being taken against SPAs.

I think what’s less discussed, though, is how the context has changed in recent years to give MPAs more of an upper hand against SPAs. In particular:

  1. Chrome implemented paint holding – no more “flash of white” when navigating between MPA pages. (Safari already did this.)
  2. Chrome implemented back-forward caching – now all major browsers have this optimization, which makes navigating back and forth in an MPA almost instant.
  3. Service Workers – once experimental, now effectively 100% available for those of us targeting modern browsers – allow for offline navigation without needing to implement a client-side router (and all the complexity therein).
  4. Shared Element Transitions, if accepted and implemented across browsers, would also give us a way to animate between MPA navigations – something previously only possible (although difficult) with SPAs.

This is not to say that SPAs don’t have their place. Rich Harris has a great talk on “transitional apps,” which outlines some reasons you may still want to go with an SPA. For instance, you might want an omnipresent element that survives page navigations, such as an audio/video player or a chat widget. Or you may have an infinite-loading list that, on pressing the back button, returns to the previous position in the list.

Even teams that are not explicitly using these features may still choose to go with an SPA, just because of the “unknown” factor. “What if we want to implement navigation animations some day?” “What if we want to add an omnipresent video player?” “What if there’s some customization we want that’s not supported by existing browser APIs?” Choosing an MPA is a big architectural decision that may effectively cut off the future possibility of taking control of the page in cases where the browser APIs are not quite up to snuff. At the end of the day, an SPA gives you full control, and many teams are hesitant to give that up.

That said, we’ve seen a similar scenario play out before. For a long time, jQuery provided APIs that the browser didn’t, and teams that wanted to sleep soundly at night chose jQuery. Eventually browsers caught up, giving us APIs like querySelector and fetch, and jQuery started to seem like unnecessary baggage.

I suspect a similar story may play out with SPAs. To illustrate, let’s consider Rich’s examples of things you’d “need” an SPA for:

  • Omnipresent chat widget: use Shared Element Transitions to keep the widget painted during MPA navigations.
  • Infinite list that restores scroll position on back button: use content-visibility and maybe store the state in the Service Worker if necessary.
  • Omnipresent audio/video player that keeps playing during navigations: not possible today in an MPA, but who knows? Maybe the Picture-in-Picture API will support this someday.

To be clear, though, I don’t think SPAs are going to go away entirely. I’m not sure how you could reasonably implement something like Photoshop or Figma as an MPA. But if new browser APIs and features keep landing that slowly chip away at SPAs’ advantages, then more and more teams in the future will probably choose to build MPAs.

Personally I think it’s exciting that we have so many options available to us (and they’re all so much better than they were 10 years ago!). I hope folks keep an open mind, and keep pushing both SPAs and MPAs (and “transitional apps,” or whatever we’re going to call the next thing) to be better in the future.

Follow-up: More thoughts on SPAs

The struggle of using native emoji on the web

Emoji are a standard overseen by the Unicode Consortium. The web is a standard governed by bodies such as the W3C, WHATWG, and TC39. Both emoji and the web are ubiquitous.

So you might be forgiven for thinking that, in 2022, it’s possible to plop an emoji on a web page and have it “just work”:

If you see a lotus flower above, then congratulations! You’re on a browser or operating system that supports Emoji 14.0, released in September 2021. If not, you might see something that looks like the scoreboard on an old 80’s arcade game:

Black square with monospace text inside of hexademical encoding
Another apt description would be “robot barf.”

Let’s try another one. What does this emoji look like to you?

If you see a face with spiral eyes, then wonderful! Your browser can render Emoji 13.1, released in September 2020. If not, you might see a puzzling combination of face with crossed-out eyes and a shooting (“dizzy”) star:

😵💫

It’s a fun bit of cartoon iconography to know that this combination means “dizzy face,” but for most folks, it doesn’t really evoke the same meaning. It’s not much better than the robot barf.

Emoji and browser support

If you’re like me, you’re a minimalist when it comes to web development. If I don’t have to rebuild something from scratch, then I’ll avoid doing so. I try to “use the platform” as much as possible and lean on existing web standards and browser capabilities.

When it comes to emoji, there are a lot of potential upsides to using the platform. You don’t need to bring your own heavy emoji font, or use a spritesheet, or do any manual DOM processing to replace text with <img>s. But sadly, if you try to avoid these heavy-handed techniques and just, you know, use emoji on the web, you’ll quickly run into the kinds of problems I describe above.

The first major problem is that, although emoji are released by the Unicode Consortium at a yearly cadence, OSes don’t always update in a timely manner to add the latest-and-greatest characters. And the browser, in most cases, is beholden to the OS to render whatever emoji fonts are provided by the underlying system (e.g. Apple Color Emoji on iOS, Microsoft Segoe Color Emoji on Windows, etc.).

In the case of major releases (such as Emoji 14.0), a missing character means the “robot barf” shown above. In the case of minor releases (such as Emoji 13.1), it can mean that the emoji renders as a bizarre “double” emoji – some of my favorites include “man with floating wig of red hair” (👨🦰) for “man with red hair” (👨‍🦰) and “bear with snowflake” (🐻❄️) for “polar bear” (🐻‍❄️).

If I’m trying to convince you that native emoji are worth investing in for your website, I’ve probably lost half my audience at this point. Most chat and social media app developers would prefer to have a consistent experience across all browsers and devices – not a broken experience for some users. And even if the latest emoji were perfectly supported across devices, these developers may still prefer a uniform look-and-feel, which is why vendors like Twitter, Facebook, and WhatsApp actually design their own emoji fonts.

Detecting broken emoji

Let’s say, though, that you’re comfortable with emoji looking different on different platforms. After all – maybe Apple users would prefer to see Apple emoji, and Windows users would prefer to see Windows emoji. And in any case, you’d rather not reinvent what the OS already provides. What do you have to do in this case?

Well, first you need a way to detect broken emoji. This is actually much harder than it sounds, and basically boils down to rendering the emoji to a <canvas>, testing that it has an actual color, and also testing that it doesn’t render as two separate characters. (is-emoji-supported is a decent JavaScript library that does this.)

This solution has a few downsides. First off, you now need to run JavaScript before rendering any text – with all the problems therein for SSR, performance, etc. Second, it doesn’t actually solve the problem – it just tells you that there is a problem. And it might not even work – I’ve seen this technique fail in cross-origin iframes in Firefox, presumably because the <canvas> triggered the browser’s fingerprinting detection.

But again, let’s just say that you’re comfortable with all this. You detect broken emoji and perhaps replace them with text saying “emoji not supported.” Or maybe you want a more graceful degradation, so you include half a megabyte of JSON data describing every emoji ever created, so that you can actually show some text to describe the emoji. (Of course, that file is only going to get bigger, and you’ll need to update it every year.)

I know what you’re thinking: “I just wanted to show an emoji on my web page. Why do I have to know everything about emoji?” But just wait: it gets worse.

Black-and-white older emoji

Okay, so now you’re successfully detecting whether an emoji is supported, so you can hide or replace those newfangled emoji that are causing problems. But would it occur to you that the oldest emoji might be problematic too?

This is the classic smiling face emoji. But depending on your browser, instead of the more familiar full-color version, you might see a simple black-and-white smiley. In case you don’t see it, here is a comparison, and here’s how it looks in Chrome on Windows:

Screenshot showing a black and white smiley face with no font-family and a color smiley face with system emoji font family

You’ll also see this same problem for some other older emoji, such as red heart (❤️) and heart suit (♥️), which both render as black hearts rather than red ones.

So how can we render these venerable emoji in glorious Technicolor? Well, after a lot of trial-and-error, I’ve landed on this CSS:

div {
  font-family: "Twemoji Mozilla",
               "Apple Color Emoji",
               "Segoe UI Emoji",
               "Segoe UI Symbol",
               "Noto Color Emoji",
               "EmojiOne Color",
               "Android Emoji",
               sans-serif;
}

Basically, what we have to do is point the font-family at a known list of built-in emoji fonts on various operating systems. This is similar to the “system font” trick.

If you’re wondering what “Twemoji Mozilla” is, well, it turns out that Firefox is a bit odd in that it actually bundles its own version of Twitter’s Twemoji font on Windows and Linux. This will be important later, but let’s set it aside for now.

What is an emoji, anyway?

At this point, you may be getting pretty tired of this blog post. “Nolan,” you might say, “why don’t you just tell me what to do? Just give me a snippet I can slap onto my website to fix all these dang emoji problems!” Well I wish it were as simple as just chucking a CSS font-family onto your body and calling it a day. But if you try that naïve approach, you’ll start to see some bizarre characters:

The text "Call me at #555-0123! You might have to hit the * or # on your smartphone™" with some of the characters thicker and larger and cartoonier than the others.

As it turns out, characters like the asterisk (*), octothorpe (#), trademark (™), and even the numbers 0-9 are technically emoji. And depending on your browser and OS, the system emoji font will either not render them at all, or it might render them as the somewhat-cartoony versions you see above.

Maybe to some folks it’s acceptable for these characters to be rendered as emoji, but I would wager that the average person doesn’t consider these numbers and symbols to be “emoji.” And it would look odd to treat them like that.

So all right, some “emoji” are not really emoji. This means we need to ensure that some characters (like the smiley face) render using the system emoji font, whereas other kinda-sorta emoji characters (like * and #) don’t. Potentially you could use a JavaScript tool like emoji-regex or a CSS tool like emoji-unicode-range to manage this, but in my experience, neither one handles all the various edge cases (nor have I found an off-the-shelf solution that does). And either way, it’s starting to feel pretty far from “use the platform.”

Windows woes

I could stop right here, and hopefully I’ve made the point that using native emoji on the web is a painful experience. But I can’t help mentioning one more problem: flag emoji on Windows.

As it turns out, Microsoft’s emoji font does not have country flags on either Windows 10 or Windows 11. So instead of the US flag emoji, you’ll just see the characters “US” (and the equivalent country codes for other flags). Microsoft might have a good geopolitical reason to do this (although they’d have to explain why no other emoji vendor follows suit), but in any case, it makes it hard to talk about sports matches or national independence days.

Grid of some flag emoji such as the pirate flag and rainbow flag, followed by many two-letter character codes instead of emoji
Flag emoji in Chrome on Windows. You can have the pirate flag, you can have the race car flag, but you can’t root for Argentina vs Brazil in a soccer match.

Interestingly, this problem is actually solvable in Firefox, since they ship their own “Mozilla Twemoji” font (which, furthermore, tends to stay more up-to-date than the built-in Microsoft font). But the most popular browser engine on Windows, Chromium, does not ship their own emoji font and doesn’t plan to. There’s actually a neat tool called country-flag-emoji-polyfill that can detect the broken flag support and patch in a minimal Twemoji font to fix it, but again, it’s a shame that web developers have to jump through so many hoops to get this working.

(At this point, I should mention that the Unicode Consortium themselves have come out against flag emoji and won’t be minting any more. I can understand the sentiment behind this – a font consortium doesn’t want to be in the business of adjudicating geopolitical boundaries. But in my opinion, the cat’s already out of the bag. And it seems bizarre that Wales and Scotland get their own flag, but no other countries, states, provinces, municipalities, duchies, earldoms, or holy empires ever will. It seems guaranteed to lead to an explosion of non-standard vendor-specific flags, which is already happening according to Emojipedia.)

Conclusion

I could go on. I really could. I could talk about the sad state of browser support for color fonts, or how to avoid mismatched emoji fonts in Firefox, or subtle issues with measuring emoji width on Windows, or how you need to install a separate package for emoji to work at all in Chrome on Linux.

But in the end, my message is a simple one: I, as a web developer, would like to use emoji on my web sites. And for a variety of reasons, I cannot.

Screenshot of a grid of emoji smileys where some emoji are empty boxes with text inside
I build an emoji picker called emoji-picker-element. This is what it would look like if I didn’t bend over backwards to fix emoji problems.

At a time when web browsers have gained a staggering array of new capabilities – including Bluetooth, USB, and access to the filesystem – it’s still a struggle to render a smiley face. It feels a bit odd to argue in 2022 that “the web should have emoji support,” and yet here I stand, cap in hand, making my case.

You might wonder why browsers have been so slow to fix this problem. I suspect part of it is that there are ready workarounds, such as twemoji, which parses the DOM to look for emoji sequences and replaces them with <img>s. The fact that this technique isn’t great for performance (downloading extra images, processing the DOM and mutating it, needing to run JavaScript at all) might seem unimportant when you consider the benefits (a unified look-and-feel across devices, up-to-date emoji support).

Part of me also wonders if this is one of those cases where the needs of larger entities have eclipsed the needs of smaller “mom-and-pop” web shops. A well-funded tech company building a social media app with a massive user base has the resources to handle these emoji problems – heck, they might even design their own emoji font! Whereas your average small-time blogger, agency, or studio would probably prefer for emoji to “just work” without a lot of heavy lifting. But for whatever reason, their voices are not being heard.

What do I wish browsers would do? I don’t have much of a grand solution in mind, but I would settle for browsers following the Firefox model and bundling their own emoji font. If the OS can’t keep its emoji up-to-date, or if it doesn’t want to support certain characters (like country flags), then the browser should fill that gap. It’s not a huge technical hurdle to bundle a font, and it would help spare web developers a lot of the headaches I listed above.

Another nice feature would be some sensible way to render what are colloquially known as “emoji” as emoji. So for instance, the “smiley face” should be rendered as emoji, but the numbers 0-9 and symbols like * and # should not. If backwards compatibility is a concern, then maybe we need a new CSS property along the lines of text-rendering: optimizeForLegibility – something like emoji-rendering: optimizeForCommonEmoji would be nice.

In any case, even if this blog post has only served to dissuade you from ever trying to use native emoji on the web, I hope that I’ve at least done a decent job of summarizing the current problems and making the case for browsers to help solve it. Maybe someday, when browsers everywhere can render a smiley face, I can write something other than :-) to show my approval.

Update: At some point, WordPress started automatically converting emoji in this blog post to <img>s. I’ve replaced some of the examples with CodePens to make it clearer what’s going on. Of course, the fact that WordPress feels compelled to use <img>s instead of native emoji kind of proves my point.

Update: Ollie Williams has written a great recent blog post with some more tips on rendering emoji.

Five years of quitting Twitter

It’s been almost five years since I deleted my Twitter account. I didn’t just delete the app or deactivate – I deleted my whole account and my entire tweet history, lighting a match and burning the bridge behind me.

I don’t want to pretend to be some kind of seer, but since then, divesting yourself from social media has become a somewhat fashionable lifestyle choice. For a certain type of person, it’s the kind of pro-mental health, self-care kind of thing you might do along with going vegan or taking up Vispassana meditation. (To make it clear that I’m not above such intellectual trendiness, I’ve tried all those things too.)

In this post, I want to talk honestly about the good and the bad that comes with deleting your Twitter account, from the perspective of a tech guy who’s plugged in to several different software communities (open source, web development, Node.js, etc.).

The good

Let’s start off with the good stuff. Twitter is no longer what I check first thing in the morning and the last thing before I go to sleep. In fact, I instituted a personal rule to charge my phone outside of the bedroom altogether so that I’m not tempted to read it in bed. (I don’t always hold fast to this.)

I have my RSS feed, I have Hacker News, and I have various news outlets (Ars Technica, Wired, etc.), so there’s plenty for me to read on the internet. But unlike Twitter, I actually run out of stuff to read and eventually get bored with my phone. I consider this a plus, even if it ends up driving me towards other screens – video games in particular. But even if my lofty goal is to spend more time reading books or riding my bike, I still consider time spent with my Switch or doing crossword puzzles to be time better spent than flicking through social media.

I also disabled all notifications on my phone except for IM and email, which helps reduce the neediness of my little pocket Tamagatchi. IM notifications are invaluable for keeping up with family and friends, but my email notifications are still sometimes a source of stress, so I try to unsubscribe as much as possible from any newsletters, automated updates, and other bullshit. If my email is going to buzz in my pocket and show me a notification, I want it to be something important.

I still have a Mastodon account, and I still host a Mastodon server at toot.cafe, but I’m not very active anymore. I mostly treat it as a write-only medium. My reasons for this are various, but basically I’ve become less of a booster of Mastodon (and the fediverse in general) over time. It’s a neat idea, and it still works pretty well for the cohort of hardcore techies and tech-adjacent folks who seem to be there, but I just don’t find it super interesting any more. Sometimes I think of Mastodon as my Twitter nicotine patch – it sorta feels like Twitter, it scratches the same itch, but it’s just not nearly as compelling.

The bad

If you’re the kind of techie who uses social media to connect with your peers and build your personal brand – the kind of person who speaks at conferences, writes blog posts, talks on podcasts, etc. – then quitting Twitter is a terrible idea. My blog posts get less traffic than they used to, I don’t get invited to as many conferences anymore, and even when I do give the odd podcast interview, there’s always an awkward moment when they ask for my Twitter handle, or which social media account they should direct traffic and followers to. (I dunno, GitHub? I think I have a Reddit account?)

My main public outlet these days is my blog, and from looking at the WordPress stats, my overall traffic has taken a hit since I quit Twitter. I’ve kind of ceased to exist for a certain segment of my (former) audience, and for the rest, I only exist when someone takes pity on me and links to my blog from Twitter, Reddit, Hacker News, or a big site like CSS Tricks. (I don’t abstain from Reddit or Hacker News, but I’m also not super active there.) It feels kind of weird to have quit Twitter, and yet to relish the traffic spike from a well-timed Twitter mention.

For those people who are re-sharing my content on social media, I suspect most of them found it from their RSS feed. So RSS definitely still seems alive and well, even if it’s just a small upstream tributary for the roaring downstream river of Twitter, Reddit, etc.

Another odd downside of deleting your Twitter account is that, after a cool-down period, someone can grab your Twitter handle. I didn’t realize this was a thing, so someone has squatted on my old Twitter name, presumably because they hope to re-sell it later, or maybe because they want the SEO juice? I have no idea. I would be mad about it, but the fact that this account exists (and my old mentions on Twitter still link to it!) makes Twitter a slightly shittier place, so in my own petty way, I’m kind of glad it exists.

The mixed bag

Some things that I miss from Twitter are both good and bad. Twitter is a sprawling global conversation, and a lot of the important debates in web development (client-rendering vs server-rendering, web components vs frameworks, etc.) were born and thrive there. I miss out on a lot of those debates, and many of them could serve as good fodder for a thoughtful blog post or open-source project, so I regret not having the creative spark that comes from those conversations.

The problem is that a lot of these debates are, in my opinion, either trivial or manufactured. Twitter (like all social media) is an outrage machine, designed to goose engagement using whatever means the algorithm finds through blind optimization. I fully believe that phenomena like “the great divide” in web development wouldn’t exist without Twitter, and to the extent that it does exist in the “real world,” it’s only because it was hatched on Twitter before infecting the rest of us. Social media engagement thrives when it finds a wedge to drive between two parts of a community, where it can cause incendiary content to cross-pollinate from one camp to another, creating an endless cycle of irritation, condemnation, dunking, and flaming.

Occasionally in my RSS feed I’ll read a post that starts off by saying, “There’s been a huge debate about…” or “There’s been a recent controversy over…” and then eventually I realize the whole post is about some Twitter beef. I don’t miss being on the front lines of these kind of battles, but I do think some of these debates are worth having, so I have mixed feelings about it.

Conclusion

I don’t plan on coming back to Twitter. Mostly because I just don’t need it anymore – I’m not super active at conferences or meetups, I don’t have a workshop or service I need to sell, and so there’s little professional reason for me to be there. I like posting on my blog, but I can only hope that my content gets attention in direct correlation to the value that people derive from it. If I write a good blog post, people will read it. I try to focus on that and that alone.

Honestly, even that lifestyle – writing blog posts, watching it occasionally blow up on Hacker News and Reddit, reading occasionally scathing comments – is hard enough on my mental health. Whenever I write a blog post these days, I have a period of anxiety and dread where I worry about the potential backlash. I mitigate that a bit by carefully editing my posts to remove anything that could be misconstrued, and to occasionally have some trusted friends review a draft (thank you all!), but frankly it’s a bit sad that I even do this, because my writing has gotten decidedly more boring over the years.

Sometimes I go back and read my blog posts from 2014 and marvel at how freewheeling, irreverent, and downright joyful my writing was. I don’t really write like that anymore, because social media (and the internet in general) have conditioned me to constantly fret over negative attention. So I act as my own PR firm, carefully focus-testing and bowdlerizing my prose until it’s as dry as a slice of burnt toast. Sometimes I can escape from this trap a little bit (like I’m trying to do right now), but overall I worry that my writing has gotten worse, not better, over time. (Another worry!)

So given my inherent worry-prone nature about posting content on the internet, Twitter is probably just not right for me. The high I would get from seeing a tweet go viral and getting adulation from my peers just doesn’t outweigh the anxiety, the sleeplessness, or the careful tiptoeing and sanitization of my thoughts that come with heavy social media use. I’m already bad enough with that as it is, just with my blog; coming back to Twitter would dial that up to 11.

So I deleted my Twitter account, and I plan to keep it that way. Should you do the same? Well, I dunno. If you need it for your livelihood, then decidedly not. You should probably just see Twitter as a necessary evil and try to insulate yourself from the bad parts while profiting from the good parts. If you’re a casual user, then maybe you’ve already figured out a healthy way to live with Twitter (curating your feed, turning off the algorithmic timeline, whatever), and if so – good for you! For me, I have too much stubbornness and too little faith in my own ability to manage my social media addiction to want to give Twitter a second try.

Memory leaks: the forgotten side of web performance

I’ve researched and learned enough about client-side memory leaks to know that most web developers aren’t worrying about them too much. If a web app leaks 5 MB on every interaction, but it still works and nobody notices, then does it matter? (Kinda sounds like a “tree in the forest” koan, but bear with me.)

Even those who have poked around in the browser DevTools to dabble in the arcane art of memory leak detection have probably found the experience… daunting. The effort-to-payoff ratio is disappointingly high, especially compared to the hundreds of other things that are important in web development, like security and accessibility.

So is it really worth the effort? Do memory leaks actually matter?

I would argue that they do matter, if only because the lack of care (as shown by public-facing SPAs leaking up to 186 MB per interaction) is a sign of the immaturity of our field, and an opportunity for growth. Similarly, five years ago, there was much less concern among SPA authors for accessibility, security, runtime performance, or even ensuring that the back button maintained scroll position (or that the back button worked at all!). Today, I see a lot more discussion of these topics among SPA developers, and that’s a great sign that our field is starting to take our craft more seriously.

So why should you, and why shouldn’t you, care about memory leaks? Obviously I’m biased because I have an axe to grind (and a tool I wrote, fuite), but let me try to give an even-handed take.

Memory leaks and software engineering

In terms of actual impact on the business of web development, memory leaks are a funny thing. If you speed up your website by 2 seconds, everyone agrees that that’s a good thing with a visible user impact. If you reduce your website’s memory leak by 2 MB, can we still agree it was worth it? Maybe not.

Here are some of the unique characteristics of memory leaks that I’ve observed, in terms of how they actually fit into the web development process. Memory leaks are:

  1. Low-impact until critical
  2. Hard to diagnose
  3. Trivial to fix once diagnosed

Low-impact…

Most web apps can leak memory and no one will ever notice. Not the user, not the website author – nobody. There are a few reasons for this.

First off, browsers are well aware that the web is a leaky mess and are already ruthless about killing background tabs that consume too much memory. (My former colleague on the Microsoft Edge performance team, Todd Reifsteck, told me way back in 2016 that “the web leaks like a sieve.”) A lot of users are tab hoarders (essentially using tabs as bookmarks), and there’s a tacit understanding between browser and user that you can’t really have 100 tabs open at once (in the sense that the tab is actively running and instantly available). So you click on a tab that’s a few weeks old, boom, there’s a flash of white while the page loads, and nobody seems to mind much.

Second off, even for long-lived SPAs that the user may habitually check in on (think: GMail, Evernote, Discord), there are plenty of opportunities for a page refresh. The browser needs to update. The user doesn’t trust that the data is fresh and hits F5. Something goes wrong because programmers are terrible at managing state, and users are well aware that the old turn-it-off-and-back-on-again solves most problems. All of this means that even a multi-MB leak can go undetected, since a refresh will almost always occur before an Out Of Memory crash.

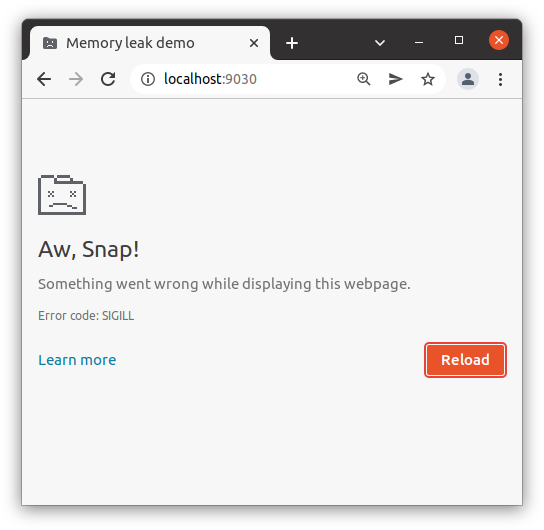
Screenshot of Chrome browser window with sad tab and "aw snap something went wrong" message
Chrome’s Out Of Memory error page. If you see this, something has gone very wrong.

Third, it’s a tragedy-of-the-commons situation, and people tend to blame the browser. Chrome is a memory hog. Firefox gobbles up RAM. Safari is eating all my memory. For reasons I can’t quite explain, people with 100+ open tabs are quick to blame the messenger. Maybe this goes back to the first point: tab hoarders expect the browser to automatically transition tabs from “thing I’m actively using” to “background thing that is basically a bookmark,” seamlessly and without a hitch. Browsers have different heuristics about this, some heuristics are better than others, and so in that sense, maybe it is the browser’s “fault” for failing to adapt to the user’s tab-hoarding behavior. In any case, the website author tends to escape the blame, especially if their site is just 1 out of 100 naughty tabs that are all leaking memory. (Although this may change as more browsers call out tabs individually in Task Manager, e.g. Edge and Safari.)

…Until critical

What’s interesting, though, is that every so often a memory leak will get so bad that people actually start to notice. Maybe someone opens up Task Manager and wonders why a note-taking app is consuming more RAM than DOTA. Maybe the website slows to a crawl after a few hours of usage. Maybe the users are on a device with low available memory (and of course the developers, with their 32GB workstations, never noticed).

Here’s what often happens in this case: a ticket lands on some web developer’s desk that says “Memory usage is too high, fix it.” The developer thinks to themselves, “I’ve never given much thought to memory usage, well let’s take a stab at this.” At some point they probably open up DevTools, click “Memory,” click “Take snapshot,” and… it’s a mess. Because it turns out that the SPA leaks, has always leaked, and in fact has multiple leaks that have accumulated over time. The developer assumes this is some kind of sudden-onset disease, when in fact it’s a pre-existing condition that has gradually escalated to stage-4.

The funny thing is that the source of the leak – the event listener, the subscriber, whatever – might not even be the proximate cause of the recent crisis. It might have been there all along, and was originally a tiny 1 MB leak nobody noticed, until suddenly someone attached a much bigger object to the existing leak, and now it’s a 100 MB leak that no one can ignore.

Unfortunately to get there, you’re going to have to hack your way through the jungle of the half-dozen other leaks that you ignored up to this point. (We fixed the leak! Oh wait, no we didn’t. We fixed the other leak! Oh wait, there’s still one more…) But that’s how it goes when you ignore a chronic but steadily worsening illness until the moment it becomes a crisis.

Hard to diagnose

This brings us to the second point: memory leaks are hard to diagnose. I’ve already written a lot about this, and I won’t rehash old content. Suffice it to say, the tooling is not really up to the task (despite some nice recent innovations), even if you’re a veteran with years of web development experience. Some gotchas that tripped me up include the fact that you have to ignore WeakMaps and circular references, and that the DevTools console itself can leak memory.

Oh and also, browsers themselves can have memory leaks! For instance, see these ResizeObserver/IntersectionObserver leaks in Chromium, Firefox, and Safari (fixed in all but Firefox), or this Chromium leak in lazy-loading images (not fixed), or this discussion of a leak in Safari. Of course, the tooling will not help you distinguish between browser leaks and web page leaks, so you just kinda have to know this stuff. In short: good luck!

Even with the tool that I’ve written, fuite, I won’t claim that we’ve reached a golden age of memory leak debugging. My tool is better than what’s out there, but that’s not saying much. It can catch the dumb stuff, such as leaking event listeners and DOM nodes, and for the more complex stuff like leaking collections (Arrays, Maps, etc.), it can at least point you in the right direction. But it’s still up to the web developer to decide which leaks are worth chasing (some are trivial, others are massive), and to track them down.

I still believe that the browser DevTools (or perhaps professional testing tools, such as Cypress or Sentry), should be the ones to handle this kind of thing. The browser especially is in a much better position to figure out why memory is leaking, and to point the web developer towards solutions. fuite is the best I could do with userland tooling (such as Puppeteer), but overall I’d still say we’re in the Stone Age, not the Space Age. (Maybe fuite pushed us to the Bronze Age, if I’m being generous to myself.)

Trivial to fix once diagnosed

Here’s the really surprising thing about memory leaks, though, and perhaps the reason I find them so addictive and keep coming back to them: once you figure out where the leak is coming from, they’re usually trivial to fix. For instance:

  • You called addEventListener but forgot to call removeEventListener.
  • You called setInterval, but forgot to call clearInterval when the component unloaded.
  • You added a DOM node, but forgot to remove it when the page transitions away.
  • Etc.

You might have a multi-MB leak, and the fix is one line of code. That’s a massive bang-for-the-buck! That is, if you discount the days of work it might have taken to find that line of code.

This is where I would like to go with fuite. It would be amazing if you could just point a tool at your website and have it tell you exactly which line of code caused a leak. (It’d be even better if it could open a pull request to fix the leak, but hey, let’s not get ahead of ourselves.)

I’ve taken some baby steps in this direction by adding stacktraces for leaking collections. So for instance, if you have an Array that is growing by 1 on every user interaction, fuite can tell you which line of code actually called Array.push(). This is a huge improvement over v1.0 of fuite (which just told you the Array was leaking, but not why), and although there are edge cases where it doesn’t work, I’m pretty proud of this feature. My goal is to expand this to other leaks (event listeners, DOM nodes, etc.), although since this is just a tool I’m building in my spare time, we’ll see if I get to it.

Screenshot of console output showing leaking collections and stacktraces for each
fuite showing stacktraces for leaking collections.

After releasing this tool, I also learned that Facebook has built a similar tool and is planning to open-source it soon. That’s great! I’m excited to see how it works, and I’m hoping that having more tools in this space will help us move past the Stone Age of memory leak debugging.

Conclusion

So to bring it back around: should you care about memory leaks? Well, if your boss is yelling at you because customers are complaining about Out Of Memory crashes, then yeah, you absolutely should. Are you leaking 5 MB, and nobody has complained yet? Well, maybe an ounce of prevention is worth a pound of cure in this case. If you start fixing your memory leaks now, it might avoid that crisis in the future when 5 MB suddenly grows to 50 MB.

Alternatively, are you leaking a measly ~1 kB because your routing library is appending some metadata to an Array? Well, maybe you can let that one slide. (fuite will still report this leak, but I would argue that it’s not worth fixing.)

On the other hand, all of these leaks are important in some sense, because even thinking about them shows a dedication to craftsmanship that is (in my opinion) too often lacking in web development. People write a web app, they throw something buggy over the wall, and then they rewrite their frontend four years later after users are complaining too much. I see this all the time when I observe how my wife uses her computer – she’s constantly telling me that some app gets slower or buggier the longer she uses it, until she gives up and refreshes. Whenever I help her with her computer troubles, I feel like I have to make excuses for my entire industry, for why we feel it’s acceptable to waste our users’ time with shoddy, half-baked software.

Maybe I’m just a dreamer and an idealist, but I really enjoy putting that final polish on something and feeling proud of what I’ve created. I notice, too, when the software I use has that extra touch of love and care – and it gives me more confidence in the product and the team behind it. When I press the back button and it doesn’t work, I lose a bit of trust. When I press Esc on a modal and it doesn’t close, I lose a bit of trust. And if an app keeps slowing down until I’m forced to refresh, or if I notice the memory steadily creeping up, I lose a bit of trust. I would like to think that fixing memory leaks is part of that extra polish that won’t necessarily win you a lot of accolades, but your users will subtly notice, and it will build their confidence in your software.

Thanks to Jake Archibald and Todd Reifsteck for feedback on a draft of this post.