Archive for the ‘Web’ Category

Do web components have a future if nobody is writing them?

With my previous post on “using the platform”, I was surprised that the comments on Hacker News and Lobsters tended to veer toward web components. This surprised me because I didn’t mention web components at all in the post.

I was less surprised when I did some research and found that the entire “use the platform” mantra was first popularized by Polymer, which was Google’s early attempt at a web-components-based JavaScript framework. In 2018 they even called it “our motto”! So this explains why a lot of people seem to have it burned into their brains that “use the platform” means “use web components.”

Now, one of the reasons I didn’t mention web components in the post is that, in my opinion, they’re actually not a great example of “use the platform” (regardless of the motto’s origins). I instead leaned on examples of HTML and CSS features that tend to be more performant, more accessible, and require far fewer lines of code than the equivalent in JavaScript. This is largely thanks to the advances that the browser vendors and standards bodies (e.g. the CSS Working Group and Open UI project) have made in the past few years.

Modern Web Guidance

Web components popped into my head again, though, after a comment on Mastodon pointed me to Google’s Modern Web Guidance. I wasn’t aware of this tool before writing the post, but essentially it’s a set of skills that you can give to an agent to nudge them in the direction of using more modern browser features. Essentially, it’s “use the platform” for agents (or at least the Chrome team’s vision of it).

As I was watching the demo, though, I was struck by how hard it is to see where web components fit into the picture. In the presentation, Phil Walton shows how you can use Modern Web Guidance to create a web app that feels more like a native app in terms of following your finger smoothly as you touch the screen, thanks to features like CSS scroll snap points and scroll-driven animations.

But nowhere in the demo are we really seeing the code – this is pure vibe-coding. And as I watched, I struggled to think of any place where, if I were building Modern Web Guidance myself, I would put instructions to tell the agent, “Hey, you should use custom elements, shadow DOM, or other web component primitives here because it’s going to make the end user experience better.” And that’s because there’s nothing that web components can really do to make the end user experience better. (Arguably you could say that shadow DOM improves CSS performance, but I’ve benchmarked this to death, and you can effectively get the same boost with compile-time CSS scoping, which many frameworks and tools like Svelte, Vue, and Tailwind are already doing.)

So I took a look at the actual code for Modern Web Guidance, and my hunch was confirmed: web components feel like an afterthought. For the first six months of the project’s lifetime, there was almost no mention of web components. This only changed 3 weeks ago when a single commit landed, which mostly provides guidelines for those already using web components, around the topics of accessibility, pre-rendering, styling, etc. But nowhere does the Modern Web Guidance strongly recommend the agent to use web components – in fact, there’s a whole section titled “Decide whether you even need a custom element” which sounds downright discouraging at times. As written, if you throw the Modern Web Guidance at an agent building a brand-new product, it seems unlikely to me that it would choose to use web components.

To be fair, there is one exception: a line for Chrome extension authors recommends using shadow DOM for complex UI injected into a page. This seems perfectly sensible to me, although it’s a fairly narrow use case. Another line suggests using web components for “design systems, embeddable widgets, and self-contained UI,” but this is also fairly narrow, and reads to me as a faint nod within the larger context of “decide whether you even need a custom element.”

Web components at a crossroads

So where do web components fit into this new AI coding world? I’m not going to rehash all my points about web components’ strengths and weaknesses; I’ve already done that at considerable length. Instead I want to talk about what’s new if people are no longer writing the code (or increasingly, even reading it).

This section was painful for me to write, because I spent years working on a web-components-based framework (LWC), participating in the Web Components Community Group and Accessibility Object Model group, and defending web components on my blog, in podcasts, etc. And yet I have to acknowledge that their core value proposition have been severely weakened by agentic coding.

In short, web components were designed for a world where people typed HTML by hand, code was scarce, and thus reuse was an economic necessity. None of those things are true anymore, or at least they’re much less true and becoming less so by the day. So the elevator pitch of “build for a common standard and your components will be easier to pick up and reuse” becomes less compelling as more and more people are vibing UIs from scratch on top of a largely invisible platform substrate.

This doesn’t just devastate the value proposition of web components: it also impacts the JavaScript frameworks that inspired them. Increasingly I read about teams rewriting their entire frontend from one framework to another, based largely on the vibes of “it’s probably better for agents.” Regardless of the merits of these rewrites (which I think ought to be more evidence-based along the lines of “it uses fewer tokens” or “it’s a faster end-user experience”), we’re likely to see more of them in the future. And if people start seeing the framework layer as disposable, it seems unlikely to me that they would assign much value to the layer one step below that.

As I argued in a 2023 post, component libraries were already moving from a “batteries-included” model to a more “DIY” mindset. The apotheosis of this is shadcdn, which might seem like a machine for spitting out reams of boilerplate, but in a sense, that’s the point. Rather than make your touchpoint with a component system an inflexible API that resists your attempts to style or tweak it, you import the individual bits and pieces and then rearrange them at your will. This shift was already underway before AI coding, and now with LLMs “reams of boilerplate” are an advantage rather than a detriment. And none of this plays to the strengths of shadow DOM, reflected attributes, or other web component mainstays.

Salvaging web components

There are two (slightly weak) cases I can try to make for web components in this new world of AI coding.

The first is so-called micro-frontends, or the idea of separating a large UI into multiple sections that can be built by different teams without clobbering each other. Web components were explicitly designed for this scenario: avoiding “friendly fire” (in Brian Kardell’s memorable phrasing). In a world of agents, this kind of sandboxing is actually a well-known technique, because typically you want to isolate agents into strict boundaries to avoid them rampaging on top of each other. In other words, web components could theoretically allow you to have multiple swarms of agents working on separate parts of the UI without their CSS, events, or globals clashing with one another.

The obvious counterpoint is that the web already has a great sandboxing primitive, which is iframes. Iframes offer even firmer boundaries than web components: not only are components isolated from each other, but they also live in separate JavaScript realms with postMessage as the only communication channel. There are several tradeoffs that I don’t want to get into here (synchronous vs asynchronous communication, memory usage, the porousness of closed vs open shadow DOM), but I do think web components have a chance in this fight. (Arguably, the Modern Web Guidance’s “design systems and self-contained UI” are also examples of micro-frontend-like scenarios where web components can shine.)

The second argument is that reuse still matters even when rewrites are just a prompt away. For example, I still believe that my <emoji-picker> element is a good poster child for an effective web component: there is no reason to rebuild this thing in React, Vue, Svelte, and a dozen other frameworks, even though you could trivially do so with an LLM these days. It’s a standalone, client-only component, and most of its complexity lives in managing the emoji data, IndexedDB, etc., with little need for touchpoints with a framework to manage its rendering or lifecycle. So packaging it as a web component and allowing folks to wrap it in their framework layer of choice (or none at all) is still a sensible distribution model.

Arguing against web components as a lingua franca for reuse sounds (to me) like an argument that all code sharing or even open source in general is a waste of time in the agentic era. My colleague André Staltz has shown that this is clearly false: if anything, AI coding is increasing the amount of shared code, not decreasing it. Even if you can rebuild something with agents, that doesn’t mean that it’s worth spending the tokens to do so. (Although I do still wonder about smaller projects.)

The stronger counterargument is that agents already have a perfectly good component reuse layer, which is React. I don’t believe this, though, because I don’t think that React is the last JavaScript framework the world will ever need. Performance benchmarks like the js-framework-benchmark and isomorphic SSR benchmark still stubbornly argue against React adoption: as it turns out, the virtual DOM is still pure overhead. React could certainly reinvent itself for the agentic era, but I imagine this could lead to compatibility problems that would argue more strongly for web component adoption, if for no other reason than to get off the update treadmill.

Still, I think the strongest argument of all is that neither web components nor React nor any other framework really matter, except maybe as a footnote in someone’s AGENTS.md or an aside in an agent’s thinking process. Recently I vibe-coded a small app for my wife, and the agent mentioned that it was wavering between Preact and Svelte before finally settling on Preact. To be honest, I didn’t care at all because the app worked and solved the problem at hand.

Conclusion

I still have a soft spot for web components, and when push comes to shove I’ll happily defend them against any detractors.

There’s even a web component on this very site! The theme picker above is an “HTML web component” (or “light DOM component”), which I find quite nice as an alternative to the old-school “HTML with jQuery sprinkles” approach. Defining setup logic in connectedCallback just feels cleaner to me than awkward querySelector acrobatics. That said, I’ll admit that I had to explicitly tell my agent to use a web component (otherwise I’m certain it would have just shrugged and reached for querySelector).

Despite my sentimentality for web components, though, I think that the web component advocates working on standards, frameworks, or browsers will have to work twice as hard to argue for their relevance in an AI coding future. I no longer have a dog in this fight, but I looked at the status of some longstanding problems with web components and was disappointed to see that server-side rendering, stylesheet sharing, and accessibility still appear to be unsolved. These kinds of flaws – which mind you, directly impact the end-user experience and are thus unchanged with AI coding – will have to be fixed if web components want to have a fighting chance.

If web components don’t survive, or they wither away to forgotten infrastructure on a minority of websites, then what will they have accomplished? Well, I do think that one unambiguous victory for web components has been in “explaining the platform.” This was one of the original goals of web components: taking a native HTML element like <video controls> or <details>/<summary> and explaining how web developers could build it themselves from platform primitives. And in fact if you look at the browser DevTools, you’ll even see “user-agent shadow DOM” hiding inside these elements.
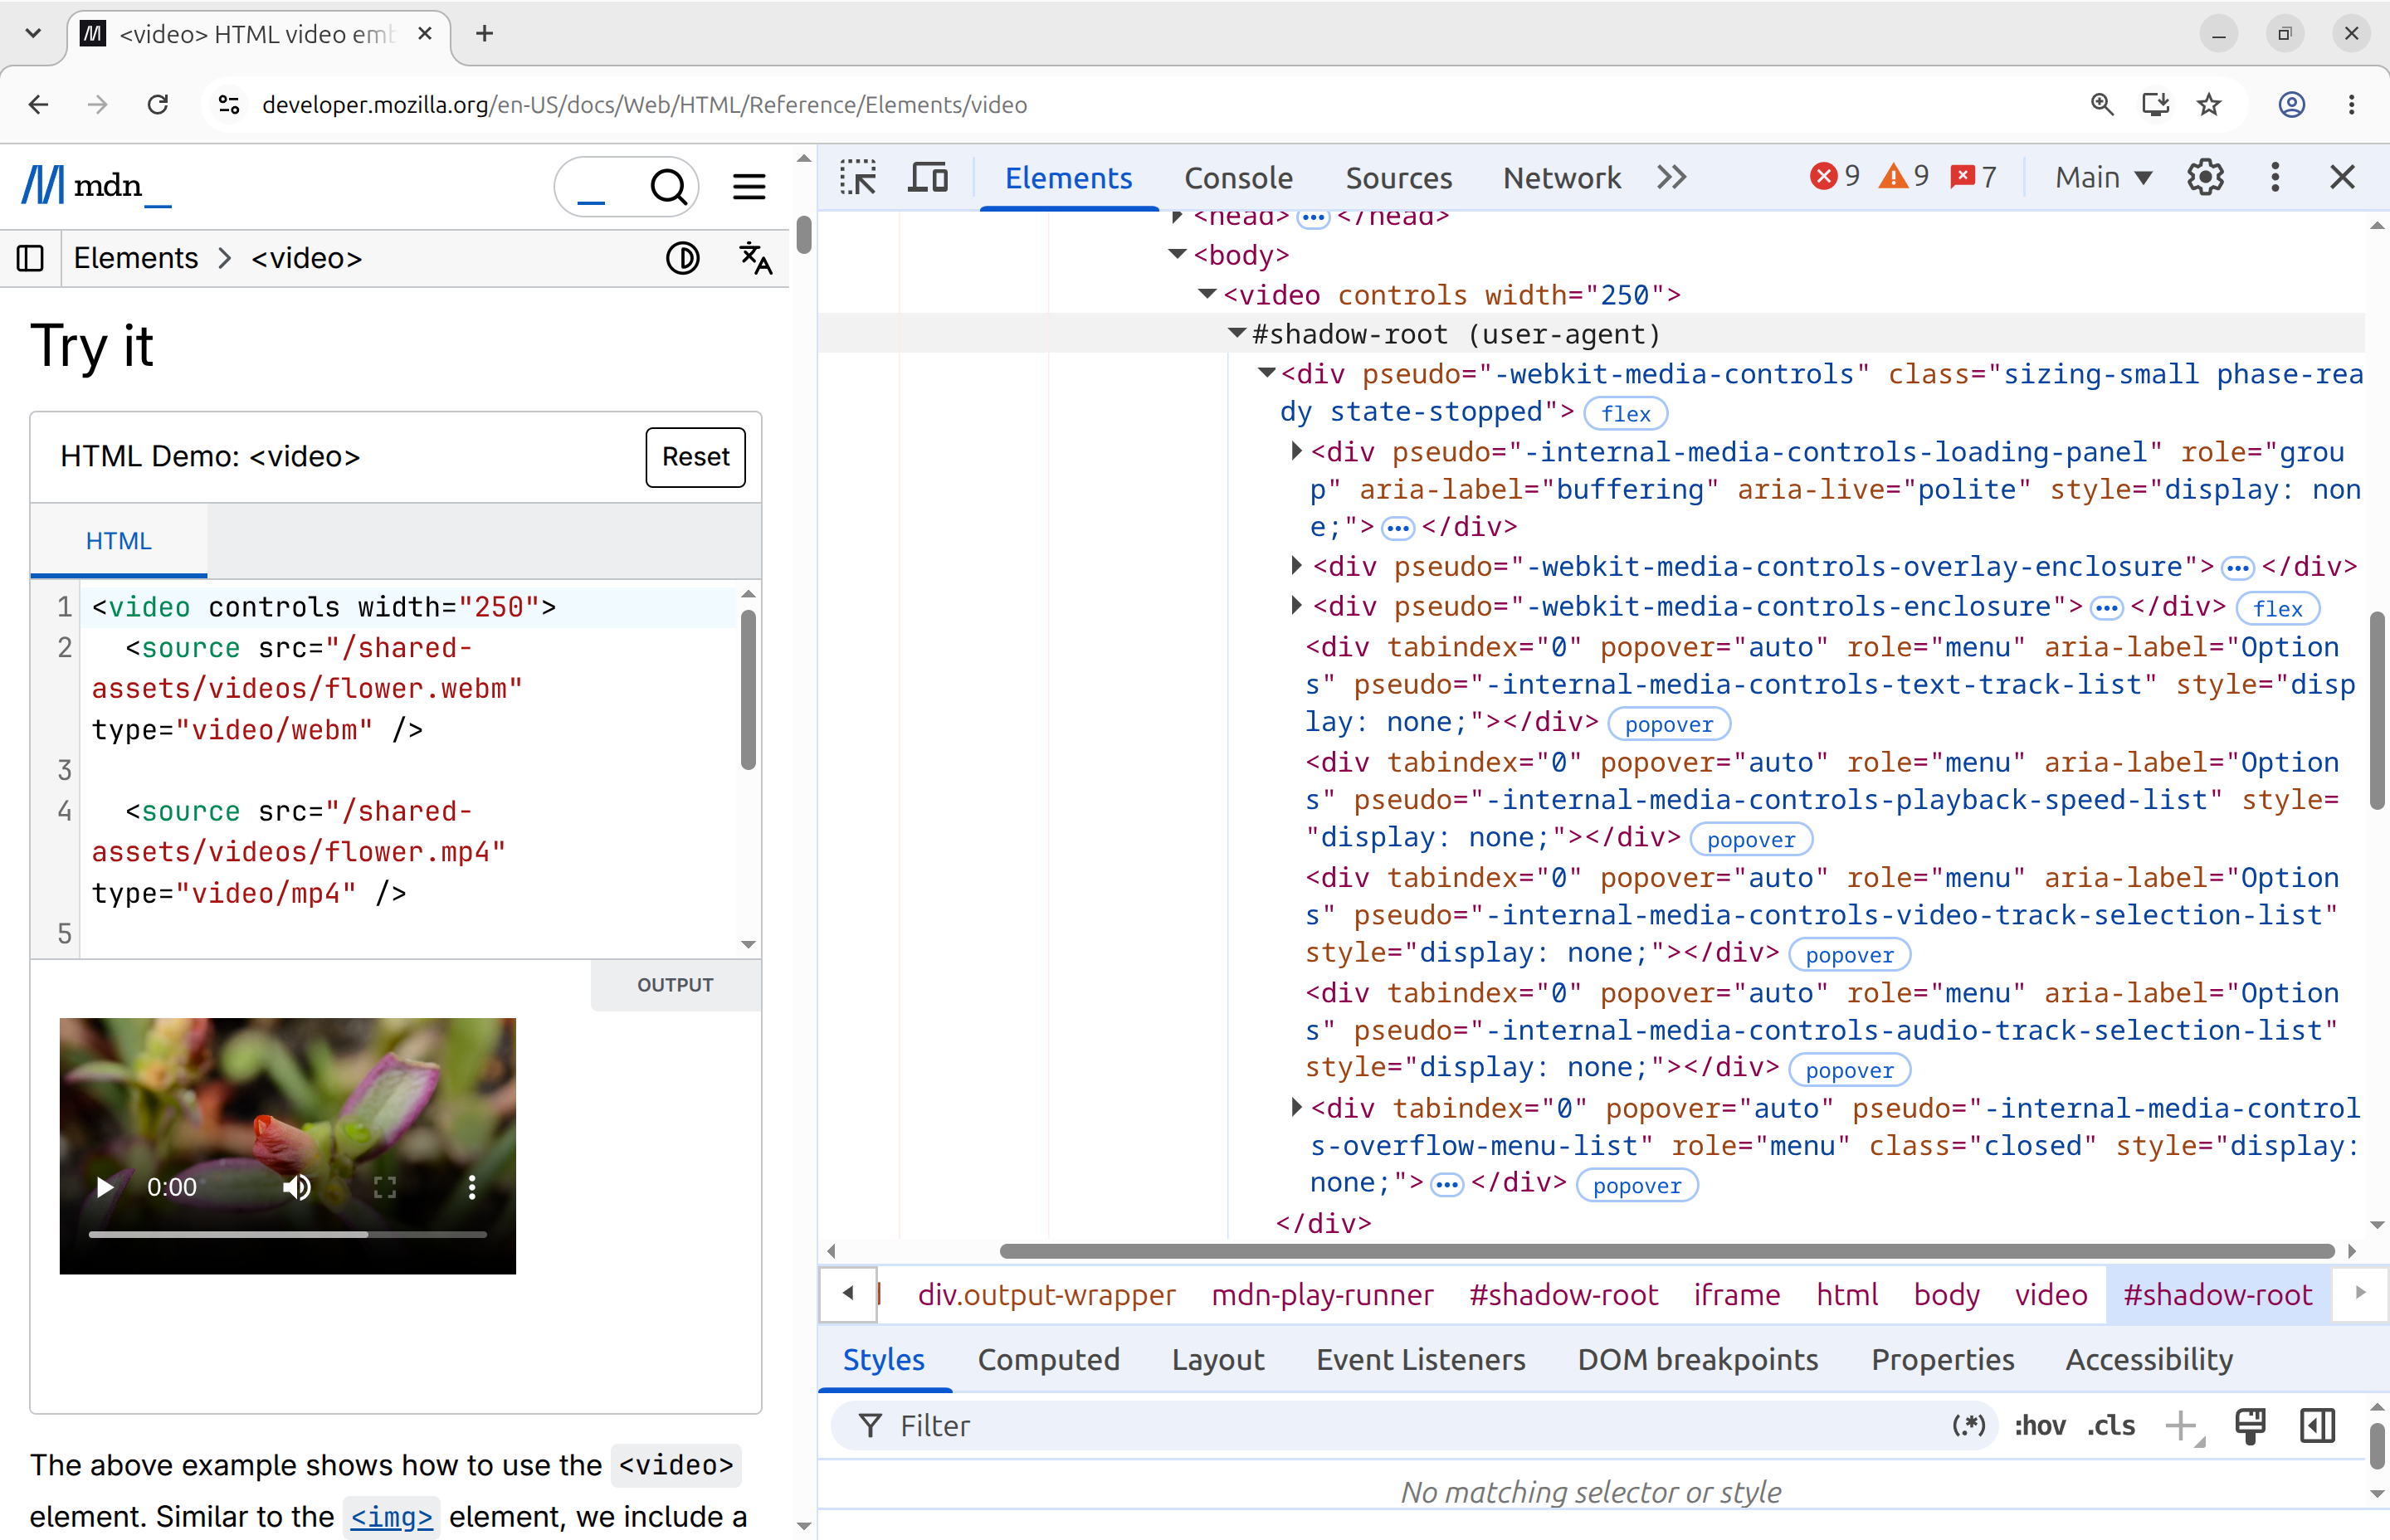
An example of Chromium's DevTools showing a video with controls having a user-agent shadow root. The video is shown on the left and the browser Elements panel in the DevTools on the right, with various elements inside shadow root.
The user agent shadow root for <video controls> in Chromium DevTools.

So from a standards and internal-consistency perspective, web components have been a clear win. They provide a degree of coherence between userland and the platform that, without them, might have felt ad-hoc or inconsistent from browser to browser.

This has also created a symbiotic relationship between standards and userland, where web component concepts have flowed back into standards and influenced the design of new platform features. You can see this most clearly in the Open UI project, where terms like “parts” and “slots” are frequently invoked (both of which come from web components), and which has landed several new features in browsers such as customizable <select>, popovers, and invoker commands, with more likely on the way.

So whatever happens to web components in the future, and regardless of whether web developers ignore them, forget them, celebrate their demise, or write them off entirely, nothing can take this victory away from them. They are woven into the texture of the web platform in a way that can never be undone. For me, this makes me happy even if I never write another web component again.

You can comment on the fediverse or Lobsters.
Why don’t more developers “use the platform”?

For years, advocates for web standards, performance, and accessibility have implored web developers to “use the platform”. I’ve often been one of those advocates.

The argument is simple: why build something yourself, in JavaScript, when the browser can do it for you? Whatever you build, it’s likely to have poorer performance and worse usability than something the browser could just give you out-of-the-box.

I think it’s worth taking the other side, though, if for no other reason than to understand where the “platform-skeptic” developers are coming from. If “use the platform” is so obvious, then why do so many people seem to need convincing?

The most obvious reason is historical: for the longest time, browsers were playing catch-up with the ecosystem on top of them. Libraries like jQuery filled crucial gaps while browsers implemented equivalent APIs – and even then, you might have to wait for laggards like IE6 to age out before you could actually use them. Today, most browsers are evergreen (Safari is debatable, although ~7 times per year ain’t bad), but up until the 2020s or so, web developers had to deal with a decidedly lumpy web. In that environment, rolling your own is a sensible choice.

Another reason is familiarity: when you’re used to looking for React components on npm, that’s what you tend to reach for, regardless of the problem at hand. If you search for “sticky positioning” on npm, there’s no package that says “just use CSS position: sticky, you dolt.”

And often, even with a robust standard, libraries on npm would fill a useful gap between framework ergonomics and the platform underneath it. I always found it intriguing that many React developers preferred to stick to JSX and React idioms – raw DOM APIs felt “icky” – but were perfectly happy to use lower-level libraries where raw DOM manipulations are common. For example, a virtual list library might happily use raw DOM APIs for pure performance, while exposing higher-level primitives that a novice React developer could better grasp. In a sense, the ecosystem of React components led to a natural division of labor where those with more expertise packaged up unfamiliar platform APIs in a more familiar form factor.

Some of this effect was also driven by documentation. Many npm packages have lovingly detailed READMEs or websites with examples, tutorials, and screenshots. Whereas until MDN became cemented as the go-to place for web documentation (with web.dev as Google’s more future-facing arm), documentation for the web platform was scattered across blogs, StackOverflow, and sites like CSS Tricks. And many of these sites would just tell you to use a well-known library like jQuery or GreenSock!

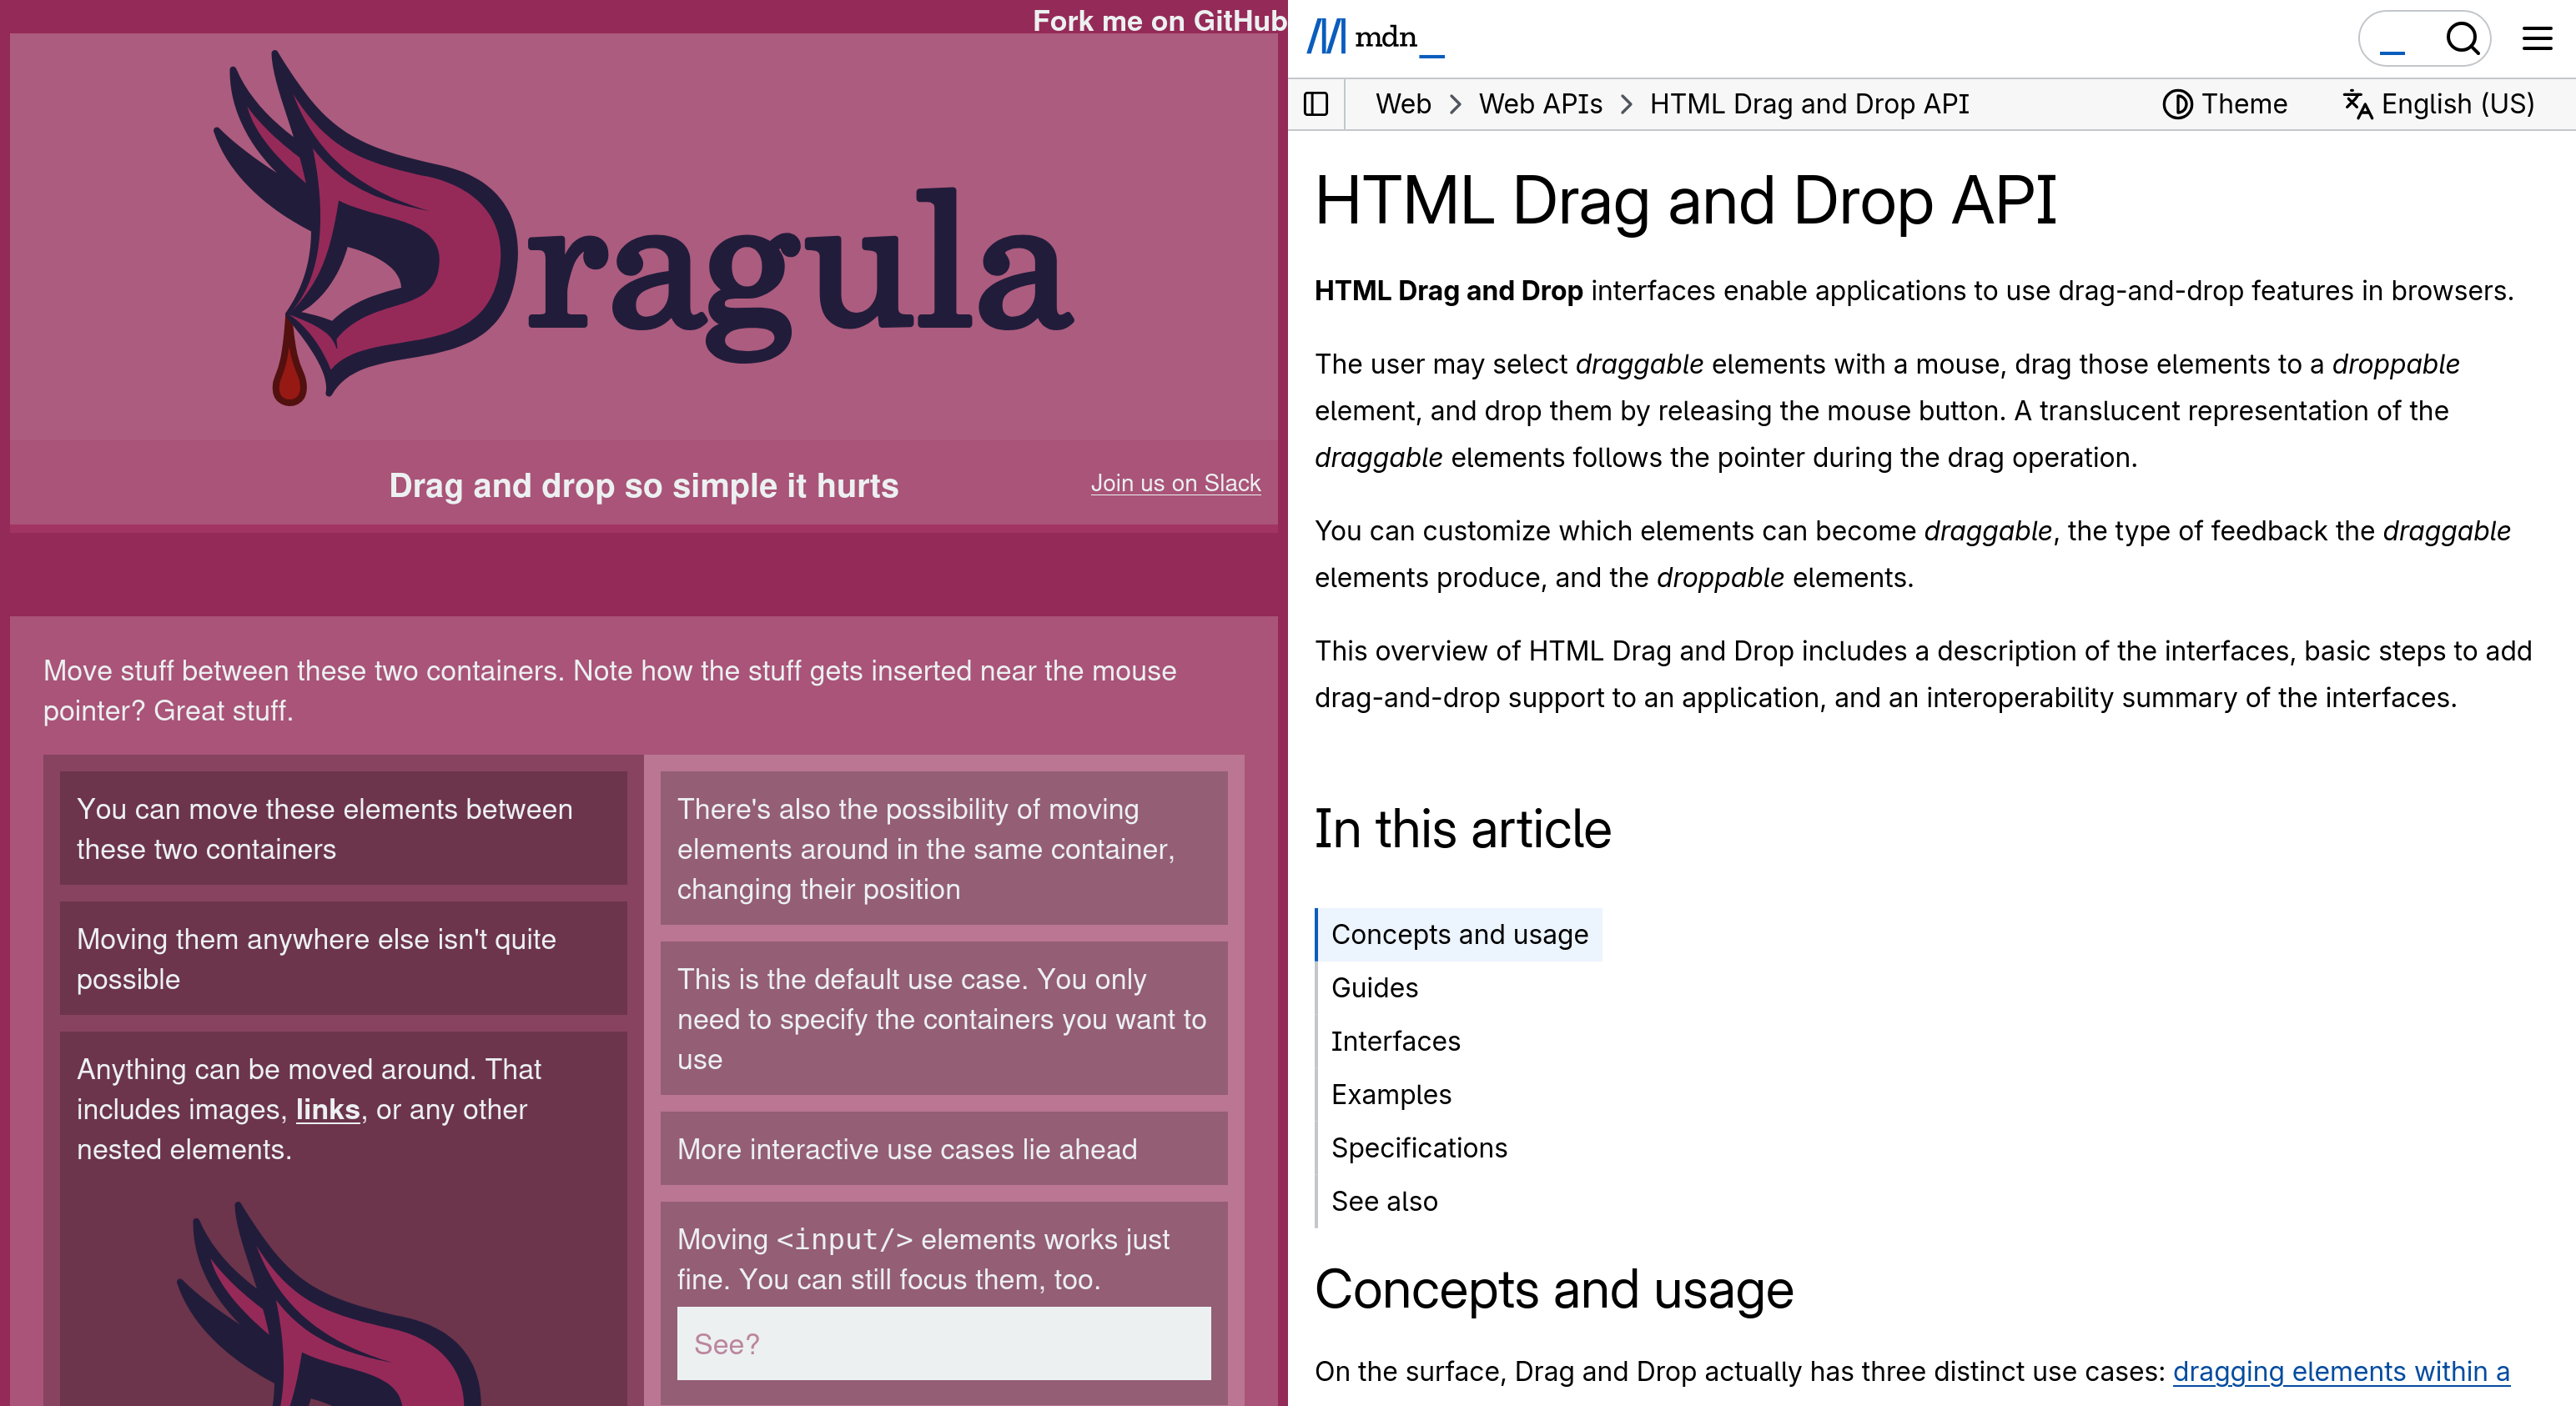
Screenshot of the Dragula website saying "drag and drop so simple it hurts" with a logo and stylized purple page versus the MDN page for the Drag and Drop API which looks much more subdued in comparison
The Dragula site versus the Drag and Drop MDN page. Arguably the former is still more compelling.

If it were just about third-party libraries versus platform APIs, though, then I don’t think it could fully explain the antipathy toward “use the platform.” Developers who are lazy (or do I repeat myself?), and who just want a ready-made solution for whatever problem they’re facing, are unlikely to care whether that solution comes from npm, the browser, or copied off of someone’s random GitHub Gist. They want to solve their problem and move on. But there’s a different source of anti-“use the platform” that I want to explore.

For a certain type of developer, building things yourself is just more fun. And often the resulting code is easier to reason about, especially if you don’t have an encyclopedic knowledge of the web platform. And once you’ve built something, there can be a kind of IKEA effect where you want to maintain and tinker with your own homemade code.

As an example, let’s imagine you’re trying to build a modal dialog. You might visually understand how these are supposed to work: content appears on the screen, but the background is still visible although partially occluded, and maybe clicking outside the dialog dismisses it. So you might grab for position:absolute and z-index to position the dialog correctly – aha, but the background still scrolls, so you have to disable overflow on the body… And then if you understand something about accessibility, you realize you need to handle Esc to dismiss, and build a focus trap, and return focus to the element that launched the dialog, and…

For many developers, what I just described sounds like a nightmare (and a good way to build something that only half-works). But for many developers, this sounds like fun! Think of how much you learn as you start building this thing. And think about how you could start putting your own spin on it by adding animations, themes, an optional “close” button… Before you know it, you’ve built a library that’s ready to go on npm. That’s way more fun than just grabbing <dialog> and calling it a day – what a downer!

And for many of us, before APIs like <dialog> existed, this was how we learned the web platform! Many of the people who now advocate for “use the platform” were once themselves authors of polyfills, shims, and libraries. I know because I’m one myself! I spent years working on tooling for IndexedDB, WebSQL, and other browser storage APIs as part of my work on PouchDB, which eventually led to me feeling confident enough to sit in W3C standards meetings and even open issues and pull requests on the IndexedDB spec itself. Without the forcing function of a gap in the platform that needed to be filled, I don’t know if I would have found the interest or motivation to get to that level of expertise.

Of course, doing it yourself is not always an unalloyed good. Sometimes it just comes from pure ignorance. On the web platform in particular, I think one of the reasons there was such a proliferation of JavaScript solutions to problems that could be better solved by CSS, for example, is that many developers just didn’t take the time to deeply understand how CSS works.

And to be fair, CSS has historically been hard to understand! There’s a reason the site is called “CSS Tricks.” Things like the clear fix, floats, and the min-width: 0 trick are hardly intuitive. Rather than trying to understand CSS’s internal algorithm, it’s often much easier to just imagine the imperative logic you want and then express it in JavaScript. Plus, for years CSS didn’t have a straightforward way to express common patterns like line clamping, textarea resizing, scrollbar hiding, etc. So of course developers built it themselves using the tools they already understood.

I don’t even think this phenomenon of “avoiding the platform” is limited to the web. It can apply to any developer working on top of a platform they don’t fully understand. For example, at my work, we use ClickHouse for storing various kinds of analytics data. At one point, my coworker and I disagreed about how to store large JSON data in a column: he built a system for compressing it before storage, whereas I put the data in a separate key-value store and only inserted the key into ClickHouse. It turned out we were both wrong! ClickHouse automatically compresses data, and as a columnar data store you actually get better compression across rows if you just let ClickHouse handle it. And the separate key-value store was just a poor man’s version of what a columnar SELECT already does.

I only realized these things after actually taking the time to thoroughly read the ClickHouse docs and then write a benchmark to prove my hypothesis. In the end I was shocked that we had built something that was slower and clunkier than what the platform itself could give us out-of-the-box. The parallels with JavaScript and the web platform were hard to ignore.

I’m sure that if you’re a developer on iOS or Android, or someone building on top of a game engine, or really any kind of developer building on top of any platform layer, you probably have similar stories. There’s a reason that the stereotype of the grizzled senior engineer is someone who can take a junior’s baroque tangled mess of code and replace it with a single line. The more you learn, the more you’re able to wield your knowledge of how the entire system works end-to-end to create the smallest possible contribution to it (and thus reduce your maintenance burden in the long run).

I’ve been trying really hard not to talk about AI this entire post (because I’ve done it to death over the past year), but of course I can’t help but wonder how AI coding will impact this phenomenon. I actually have both an optimistic and a pessimistic take:

  • Optimistic: because LLMs have an encyclopedic knowledge of whatever platform you’re working with, they can choose exactly the right platform API to deliver the experience the prompter asks for in vague English. And since this solution is likely faster and more correct than userland code, the agent will prefer it after rigorous testing and benchmarking. Furthermore, the “IKEA effect” goes away when developers are not actually writing the code themselves.
  • Pessimistic: because LLMs seem to love duplicating code – for example, ignoring helper functions that already exist in favor of writing their own for the umpteenth time – the amount of custom, non-platform-idiomatic code will skyrocket. Developers won’t instruct their agents to test enough or to try enough alternatives, and will just commit the agent’s first draft. And because it’s always possible to add more epicycles, the agents will continue to iterate on over-engineered solutions that never should have existed in the first place.

In my own use of AI coding, I’ve seen both phenomena happen. I’d like to think that as models and coding harnesses get better we’ll start to veer more towards the optimistic outcome, but I can’t say for sure.

In any case, these are my longwinded and somewhat conflicting thoughts on “use the platform.” As a mantra I love it, because it succinctly captures a feeling I have when I’m looking at some overwrought pile of spaghetti code and thinking how much better and more elegant it would be if the author just understood the layers beneath them a bit better. At the same time, I’ve been that author, and I’ve felt the joy of building such beautiful, messy code (beautiful to me, anyway), so I think it’s worth understanding where such developers are coming from. For that reason, I’m sure we’ll be hearing “use the platform” for as long as there are platforms.

You can comment on the fediverse or Lobsters.
The asteroid currently hitting frontend web development

A lot of the educators I admire in the frontend web space seem to be either bowing out or dialing back their efforts: Axel Rauschmayer, Salma Alam-Naylor, Josh W. Comeau, to name a few. Other well-known luminaries like Kent C. Dodds, Addy Osmani, Rachel Nabors, and Lydia Hallie have pivoted from talking about frontend development to talking about… well, take a wild guess.

I never made a living from talking about web dev, but I do have this blog, and I’ve done conference talks and podcasts about stuff I’m excited about. Recently for example, my passion was explaining all the ins and outs of CSS performance: how shadow DOM works, how the browser’s style engine works, the traps of CSS-in-JS, etc.

Just for kicks, I decided to ask Claude Sonnet how it would handle a Chrome trace with high “Style Calculation” costs. This is one of my favorite brain-teasers, because it’s the kind of thing that I saw web devs – even experienced ones! – trip up on over and over again. Claude gave a perfectly admirable answer:

Click to see

Prompt: Answer without searching the internet: you’re looking at a Chrome trace, and you see repeated spans of high Style cost but relatively low Layout cost. What kind of things do you look for in the webapp to optimize? What do you measure next?

What “Style” cost actually represents

The Style (Recalculate Style) phase is where the browser matches CSS selectors against the DOM and computes the final computed style for each affected element. It’s expensive independent of whether anything actually moves or resizes (that’s Layout’s job). So if Style is high but Layout is low, you’re likely paying for selector matching / invalidation over many elements, not for expensive geometry.

What to look for in the webapp

1. Selector complexity and count

  • Overly complex or deeply nested selectors (.a .b .c >; .d + .e), especially descendant combinators, force the engine to walk more of the DOM/ancestor chain per match attempt.
  • Universal selectors or attribute selectors ([data-foo="bar"]) applied broadly.
  • CSS-in-JS libraries that generate huge numbers of unique class names/rules (style recalculation has to consider the whole rule set).

2. Invalidation scope — this is usually the big one

  • A class/attribute/style toggle high up in the DOM tree (e.g., toggling a class on <body> or a top-level container) can force style recalculation on large subtrees even if only a few elements’ final styles change.
  • Check whether a single state change (e.g., a “theme” class, a “loading” class, a hover state) is invalidating far more elements than necessary. Chrome’s “Selector Stats” (enable in DevTools Performance settings) will show you which selectors are slow and how many elements they were tested against — this is the single most useful next measurement.

3. Frequency/amplification

  • Something re-triggering style recalc many times per frame — e.g., reading a style/layout property in a loop right after a class change (forces synchronous recalc), or a JS animation using .classList.toggle() or inline style updates on many nodes per rAF tick instead of batching.
  • Repeated small DOM mutations each forcing a style pass rather than being batched into one.

4. Inherited/computed property propagation

  • Changing an inherited property (like font-size or color on a common ancestor) forces recompute of all descendants’ computed styles, even without layout changes (e.g., color, visibility, cursor are Style-only, not Layout-triggering).
  • Custom properties (CSS variables) changed at a high-level scope — updating a --custom-prop on :root or a shared ancestor recomputes style for every element referencing it.

5. Shadow DOM / component boundaries

  • If using a framework with lots of shadow roots or scoped styles, check whether style recalculation is being needlessly repeated per component instance due to non-shared stylesheets.

What to measure next

  1. Enable “Selector Stats” in the Performance panel (gear icon → Enable selector stats). Re-record the trace. This gives you, per Recalculate Style event, the top slow selectors and match counts — that tells you directly which CSS rules and how many elements are responsible.
  2. Check the “Recalculate Style” event’s initiator/call stack in the trace to see what JS triggered it — a class toggle, a style.setProperty, an animation frame callback, etc.
  3. Count how many elements are affected per recalc — DevTools shows “Elements Affected” per Recalculate Style event in the summary pane. Compare that number to how many elements actually changed appearance — a big gap indicates over-broad invalidation.
  4. Look at where in the DOM the triggering mutation happens — is it near the root (broad invalidation) vs. scoped to a small subtree (narrow, cheap)?
  5. Check for forced synchronous style — look for “Forced reflow” purple warnings; even though you said Layout is low, sometimes a forced style read (getComputedStyle) interleaved with a DOM write shows up as many small back-to-back Style events rather than one batched one.

Typical fixes once you find the culprit

  • Scope class/state toggles to the smallest subtree possible instead of a common ancestor.
  • Simplify selectors, prefer single class selectors over descendant chains.
  • Move CSS custom property updates to the smallest scope needed.
  • Batch DOM/class changes so recalculation happens once, not per-mutation.
  • Use content-visibility: auto or contain: style layout on independent subtrees to limit invalidation scope.

These days, given a slow-loading website, even as someone who’s written about browser performance for years and who literally worked on a browser performance team, I would probably just chuck a Chrome trace at Claude Code and have it suggest improvements. In fact I’ve done this very thing in my day job and gotten some good results.

The future of frontend

So where does this leave frontend dev education? Not in a great place obviously; I wish I had some more uplifting answers for people who (like me) used to get a lot of fulfillment out of trying to raise the bar for frontend developers everywhere. I do have some guesses though, and I think the problem is still worth puzzling through.

The core question is where frontend development itself lands in this new era. Sadly it feels to me like there are several trends pointing against increased investment in frontend knowledge:

The frontend is less risky to just hand to an agent. If you’re using an agent to write a database migration, you probably want to put it through several rounds of AI code review, scrutinize it yourself, run it on staging first, etc. If you write a React component with an agent, though, then the risk of just yolo’ing it into production is (typically) much lower.

Note I’m not saying there are zero risks: the agent could mess up accessibility, it could cause an infinite loop that blocks users, etc. But in general, frontend code is a lot more ephemeral and replaceable than other types of code. So I expect many AI coders will feel comfortable just letting their agent handle it unsupervised (for better or worse).

DevExp is becoming less critical overall. A lot of the pre-LLM discussion in the frontend space was about ergonomics versus outcomes: “The ‘developer experience’ bait-and-switch” by Alex Russell is a great example. For another example, Svelte and Solid have long argued that their ergonomics lead to better outcomes than React: less code, better performance, etc.

Meanwhile, Cursor and Viget have blogged about migrating their codebases from Solid and Lit, respectively, to React. Since rewrites are less expensive with agents, this may be a bit surprising: why not move to the more performant/less verbose framework? The answer (explicitly in Cursor’s case, and I suspect for Viget as well) is of course: “the agents know React.” For better or worse, React is heavily overrepresented in the training weights, and “agent experience” is starting to matter more than developer experience.

Standards will catch up. I’ve been out of the web standards space for a couple years now, so this is pure speculation on my part. But I imagine that a lot of the efforts to improve the ergonomics of building websites – better CSS shorthands, terser JavaScript syntax, etc. – will become perceived as less important relative to things that actually move the needle on performance, capabilities, etc. At the end of the day, it’s just not very different for an agent to write 3 lines of CSS instead of 1, and anyway using the newer syntax might actually be harder because you have to coach the agent about things that aren’t in its training weights.

In some ways this shift might have already been underway. I remember several years ago at TPAC, well before the AI coding boom, I told someone on the Chrome team that I was working on web component standards. They responded that they weren’t interested in that, because those APIs only affected the developer experience and didn’t actually make the browser more capable (e.g. Project Fugu). That stuck with me because it’s a good point: APIs like shadow DOM and custom elements don’t give web developers any new superpowers; they just change where and how the code gets authored. I expect such things will move out of the spotlight as AI coding takes over.

This doesn’t mean that standards will disappear from the topics a frontend dev needs to keep up on, but I imagine it will become less about “use this newer syntax” (an evergreen source of material for conference talks and articles) and more “here are these emerging capabilities.” And I predict the latter group will be much smaller than the former, since they tend to be more contentious for standards bodies and there’s just a smaller pool of features to draw from.

Whither frontend education?

So how can the field of frontend education adapt to this hostile future? To avoid being utterly bleak, here are some positive directions I think it could go in.

First off, the agents still need to be educated about the big picture. Agents and harnesses seem to love writing React and specifically SPAs, but SPAs are not the answer to everything. You can burn a lot of tokens having an agent write a big complex SPA for your marketing site, and then fix all the bugs with the back button, focus state, performance, etc., or you can just choose an MPA framework like Astro or Eleventy and call it a day. Maybe these frameworks will be a bit harder for the agents to work with (specifically Astro since it kinda-sorta looks like React but isn’t), but my guess is that since you’re writing ~50% less code overall it won’t matter.

Second, making websites that work well for agents is probably going to be a fruitful endeavor for the near future. Vercel’s is-agentic is a good example of this. Ironically, this points back to good fundamentals that public-facing websites should have been doing anyway: server-rendered content, proper accessibility, page speed, etc. But if slapping the word “AI” on it is what gets people to care about it then hey, I’m all for it.

Note that I’m a little bit less sanguine about this second point, because I’m not sure the web even survives in its current form as agents become more of a thing. If I want to figure out how much it costs to fly from Seattle to Paris, I’d much rather ask an agent than click through an infuriating series of buttons on a slow-loading website. The only reason I can’t is because these websites explicitly block bots, or they don’t offer an MCP, but I’m sure there are several startups champing at the bit to solve that problem. So I’m not sure how sustainable the current situation is.

Third, we can offer consulting services for vibe-coded monstrosities. A massive amount of AI-generated frontend code is being pumped out right now, and some of it (to use a Claude-ism) will certainly become “load-bearing.” If those websites are slow, non-compliant, and riddled with security holes, then it may not be enough to ask the agent “fix my website pls.” There could be an opportunity here for real expertise, especially if there’s money on the line and the vibe coder’s knowledge of web development doesn’t extend past “websites are apps hosted on the internet.”

(I acknowledge that this is the shakiest of my three points, since I can totally imagine the next generation of “self-healing” web apps to eclipse the average expert in 2027 or 2028. But for the time being: yes, expertise still matters.)

Conclusion

The point of this post wasn’t to make myself feel better, or to dance on the graves of all the careers that have been upended by the recent AI boom. I’m a naturally gloomy person, and this post was me allowing myself to wallow in my own gloominess. I don’t take any pleasure from noting that the huge body of knowledge I’ve built up over the years has been rendered nearly obsolete, nor am I happy to see the same thing happen to my much-more-qualified peers. But pretending that it’s not happening isn’t a valid strategy either.

There’s a mood in some of the blogs I read these days along the lines of “I’m so tired of talking about AI” or “Please don’t mention AI to me ever again.” I’m sure some of this is a kind of world-weary, above-it-all air that feels good to wear as a badge of distinction. But I think a lot of it also comes from real fear. It’s scary to admit that you don’t know what’s going to happen in a year. It’s destabilizing to imagine your career going along a certain trajectory, serenely landing at retirement, and then to see everything upset just a few years from your goal.

The metaphor I’ve been using is that an asteroid just hit the earth, and we’re still surveying the wreckage. It’s hard to predict what will happen after the dust settles (let alone which tiny rodents will usher in the Age of Mammals!), but ignoring the crater altogether seems like the worst kind of denial. Another metaphor is covid: when covid hit, I don’t recall thinking, “Ugh, I’m so tired of talking about covid” – instead, I wanted to learn everything I could about viruses, epidemiology, masking, etc. This turned out to be a good idea, since covid was going to dominate my life for the next few years (at which point yes, I did finally get tired of talking about it!).

I hardly have a crystal ball, but this post was my attempt to think through where my most cherished field might be going in the future. I admit that I have a lot less skin in the game these days: I’m out of web standards, I don’t even work on the frontend at my current gig, and my blog has mostly been a lot of wailing and gnashing of teeth about AI rather than my usual menu of browsers, performance, accessibility, etc. That said, I still have a lot of love and respect for the frontend field, and I care about what happens to it in the future. It may be unrecognizable in just a few years, but if nothing else, I hope my peers find a way to navigate all these changes and to thrive in this weird new world.

Building a browser API in one shot

When I learned that two simple browser engines had been vibe-coded, I was not particularly surprised. A browser engine is a well-understood problem with multiple independent implementations, whose codebases have no doubt been slurped up into LLM training data.

What did surprise me is that neither project seemed to really leverage the Web Platform Tests (WPTs), which represent countless person-hours of expertise distilled into a precise definition of how a browser should work, right down to the oddest of edge cases. (The second project does make partial use of WPTs, but it doesn’t seem to be the primary testing strategy.)

LLMs work great when you give them a clear specification (or PRD) and acceptance tests. This is exactly what the web standards community has been painstakingly building for the past few decades: the browser standards themselves (in plain English as HTML files) and the WPTs. The WPT pass rate in particular gives you a good measure of how “web-compatible” a browser is (i.e. can it actually render websites in the wild). This is why newer browsers like Ladybird and Servo heavily rely on it.

I don’t have the patience (or cash) to build an entire browser, but I thought it would be interesting to build a single browser API from scratch using a single prompt, and to try to pass a non-trivial percentage of the Web Platform Tests. I chose IndexedDB because it’s a specification that I’m very familiar with, having worked on both PouchDB and fake-indexeddb, as well as having opened small PRs and bugs on the spec itself.

IndexedDB is not a simple API: it’s a full NoSQL database with multiple key types (including array keys and arrays-as-keys), cursors, durability modes, transactions, scheduling, etc. If you build on top of SQLite, then you can get some of this stuff for free (which is probably why both Firefox’s and WebKit’s implementations use it), but you still have to handle JavaScript object types like Dates and ArrayBuffers, JavaScript-specific microtask timing, auto-transactions, and plenty of other idiosyncrasies.

The experiment

So here was the experiment:

  1. Create a repo with submodules containing both the Web Platform Tests and IndexedDB specification.
  2. Tell Claude (in plan mode) to create a plan to build a working implementation of IndexedDB in TypeScript and Node.js on top of SQLite, passing >90% of the tests.
  3. Plug the plan into a Ralph loop so multiple agents can iterate sequentially on solving the problem.
  4. Go to sleep and wake up the next morning.

If you’re not familiar with the so-called “Ralph Wiggum” technique, it’s dead simple: run Claude in a Bash loop, giving it a markdown file of instructions and a text file to track its progress. (That’s literally it.) The main insight is to avoid context rot by frequently starting a brand-new session. In other words: the LLM gets dumber the longer the conversation goes on, so have shorter conversations. I used Matt Pocock’s implementation (which is literally 24 lines of Bash) in --dangerously-skip-permissions mode, in a Podman container for safety.

The project completed in a few hours of work, and the agent decided to disobey my instructions and pass well over 90% of the target tests, reaching 95%. (Naughty robot!) Note that it omitted some tests because they weren’t deemed appropriate for a Node.js environment, but it still amounts to 1,208 passing tests out of the 1,272 target subset.

Here was the prompt. You’ll note I had some typos and grammatical errors (e.g. I meant instanceof, not typeof), but the agent still figured it out:

Click to see prompt

Help me plan a project. You have the entire IndexedDB spec and web-platform-tests checked out in git submodules.

Here’s the project: build a TypeScript-based project that implements IndexedDB in raw JavaScript (no dependencies) on top of SQLite (so okay, SQLite is the one dependency). You should try to pass at least 90% of the IndexedDB tests from WPT.

Stipulations:

  1. Use TypeScript and run in native Node (you have Node v24 already installed which supports TS out-of-the-box). Use tsc for linting though
  2. Write tests using node:test
  3. You must run the WPT tests UNMODIFIED in Node. To achieve this you will no doubt have to use some shims since the tests were designed to run in the browser, not Node. But as much as possible, you should prefer built-ins. Node supports a lot of built-ins now like Event and EventTarget so this shouldn’t be super hard.
  4. You should start first by setting up the basic project scaffolding and test scaffolding. To start, try to get ONE test passing, even if you have to do a basic pure-JS implementation of IndexedDB (i.e. a “hello world”) to get that to work.
  5. You should store some of these basic stipulations and project structure in CLAUDE.md as you go for the next agent. E.g. how to run tests, how to lint, etc.
  6. Your implementation should ultimately store data in sqlite. You should use the better-sqlite3 package for this. Again, no dependencies other than this one. (You may have as many devDependencies as you want, e.g. typescript)
  7. We’re building a plan, and I want this plan to encompass everything that’s needed to get to roughly 90% test coverage. To do so, we should probably divide up the PRD into some subset of tests that make sense to tackle first, but we can leave it up to future agents to change the order if it makes sense
  8. As much as possible, try to make your implementation JS-environment-agnostic. We’ll be running in Node, but if someday we want this running in a browser on top of SQLite-on-WASM then that shouldn’t be impossible. Your test harness code can have Node-specific stuff in it if necessary, but the actual library we’re building should strive to be agnostic.
  9. In the end, your test suite should have a manifest file of which tests are passing, failing, timing out, etc. This will be a good way to judge progress on the test suite and give guidance to the next agent on what to tackle next. Ideally this manifest file will have comments so that agents know if certain tests are tricky or outright impossible (toml or yaml may be a good format).
  10. You’re running in a sandbox with sudo so if you need to install some tool just do it.
  11. The project is complete when you reach 90% test coverage on the IndexedDB tests in wpt. Note that this number should be based on the number of passing tests, not the passing test files.
  12. Your test script should OUTPUT the manifest of passing/failing tests. This allows the next agent to know which tests are passing/failing WITHOUT having to actually run the tests (which takes time). You should also commit this manifest file whenever you commit to git.
  13. For simplicity, your tests should use sub-processes/workers for isolation rather than any kind of vm technique since this can introduce JavaScript cross-realm issues (e.g. typeof Array not being right).
  14. For the purposes of this project, “one task” should be considered to be ONE TEST (or maybe two) at a time to keep things simple. Don’t try to bite off huge entire feature of IndexedDB (e.g. cursors, indexes, etc.) and instead try to break work up into small chunks.
  15. The main goal of this project is to be spec-compliant, but being performant is great too. Try to leverage SQLite features for maximum performance (and don’t fake it by doing things in raw JavaScript instead). If a task is just “improve performance” then that’s fine.

And here is the project itself.

If you can’t tell from the git history, the hardest part was just keeping the loop running. Despite the relentlessness of the Bash loop, Claude Code kept occasionally erroring out with:

Error: No messages returned
    at FKB (/$bunfs/root/claude:6151:78)
    at processTicksAndRejections (native:7:39)

This seems to be a bug. Annoying, but not a dealbreaker since I could just restart the loop when it crashed. So it didn’t finish “overnight,” but it was done by the time I finished breakfast.

Evaluating the code

Looking at the project structure, it’s pretty straightforward and the files have familiar (to me) names: IDBCursor.ts, IDBFactory.ts, etc. This isn’t surprising because it follows the spec naming conventions, as well as the patterns of projects like fake-indexeddb (which I’m sure was part of the LLM training data). The test harness has to shim some browser APIs like window.addEventListener and ImageData to get certain tests to pass, which is exactly what we did in fake-indexeddb as well.

According to cloc, the src directory is 4,395 lines of code. Looking through some of the bits that I knew would be challenging, like event dispatching, I wasn’t surprised to see that it took a similar strategy to fake-indexeddb, shimming the event dispatch / listener logic rather than relying on the Node.js built-ins. (This is really not straightforward!)

Interestingly though, it deviated from fake-indexeddb by implementing its own structuredClone logic using v8.serialize(). I assume the reason for this is that, unlike fake-indexeddb, it doesn’t have the luxury of keeping JavaScript objects in memory, and instead has to serialize to SQLite. So although you could argue that it’s cribbing from its training data, it’s also doing something pretty unique in this case.

As for its transaction scheduler, this doesn’t look anything like fake-indexeddb‘s logic, but it does look sensibly designed and is at least readable. Then there’s also of course sqlite-backend.ts which deviates from the only comparable implementation I’m aware of (IndexedDBShim) by having a proper “backend” for the SQL logic rather than mixing SQL into the APIs as IndexedDBShim does (which is a bit hacky in my opinion).

One annoying thing about its coding style is that it doesn’t make much reference to the actual spec. If you read fake-indexeddb or the source code of a browser (especially Ladybird and Servo in my experience), there are often comments quoting the literal spec language. This is great, since the spec is often pseudocode anyway, so it helps the reader to keep track of whether the browser implementation actually matches the spec or not. Claude seemed to avoid this altogether; perhaps relying entirely on the WPTs, or perhaps just not seeing it worth a word-for-word comment.

Another thing I noticed during code review is that the agent fibbed a bit on the pass rate: out of the original test files it targeted, 9 crashed, and so they weren’t counted in the denominator (presumably because it didn’t know how many tests would have run). So the “real” pass rate is actually 92%, if we consider all crashed tests to be failures: 1208 / 1313 (I got the true denominator using wpt.fyi). Although to be fair, 95% is accurate for the test files that ran without crashing.

As a final test, I ran the code against fake-indexeddb‘s own WPT test suite – just to make sure there was no funny business, and the LLM didn’t cherry-pick tests to make itself look good. The two test suites aren’t 1-to-1 – the agent had decided to skip some large but tricky tests like the IDL harness, plus there are the 9 crashed tests mentioned above. So using fake-indexeddb‘s own tests gives us a more accurate way to judge this code against a comparable IndexedDB implementation.

In this more rigorous test, the implementation scores 77.4%, which compares favorably to fake-indexeddb's own 82.8% (only ~5% off). We can also compare it with browsers:

Implementation Version Passed %
Chrome 144.0.7514.0 1651 99.9%
Firefox 146.0a1 1498 90.6%
Safari 231 preview 1497 90.6%
Ladybird 1.0-cde3941d9f 1426 86.3%
fake-indexeddb 6.2.5 1369 82.8%
One-shot 1279 77.4%

77.4% vs 82.8% is really not bad, given that fake-indexeddb is ~10 years old and has 15 contributors. Although I think once you get past roughly ~40%, you have a largely working implementation – many of the WPTs are corner cases or IDL quirks, e.g. whether a property is enumerable/configurable or not.

The one-shot implementation actually passes 30 tests that fake-indexeddb fails, mostly in the zone of IDL harness tests. As for the 88 tests fake-indexeddb passes but the one-shot fails, they are mostly in structured cloning and blob serialization, properties on the IDBCursor object, errors for invalid keys such as detached ArrayBuffers, and other edge cases.

fake-indexeddb‘s WPT tests also ran in 49.2s versus 125.5s for the one-shot implementation (2.5x slower, median of 3 iterations), so there’s definitely room for improvement on performance. Although to be fair, this is comparing an actual persisted SQLite implementation versus in-memory, and boy did I work to optimize fake-indexeddb! I suspect another issue is that it chose a basic setTimeout for task queuing, whereas we used a much more optimal strategy in fake-indexeddb.

Conclusion

I’ve been talking a lot about LLMs recently and how they’ve changed my coding workflow. A large part of my audience has ethical concerns with LLMs around energy use, copyright, the motivations of big tech companies, etc., but my goal has just been to show that these things work. It would be easy to dismiss them if the technology was merely overhyped, but (somewhat sadly for me) it actually works.

This experiment is a good example of how far the latest models like Opus 4.5 have come: given a good enough prompt with clear tests and a specification, you can go to sleep at night and wake up the next morning to a working codebase. Before LLMs, you might have been able to count on two hands the number of actual independent IndexedDB implementations (~5 browser vendors plus fake-indexeddb and IndexedDBShim). Whereas now you can make a new one on-demand.

And it wasn’t that expensive, either: this project used roughly 20% of my weekly budget on a $100 Claude monthly plan, so let’s just say it cost me 7 bucks. Of course some will say that the costs are subsidized and likely to rise (and I won’t dispute that), but still: this is what you pay today. A new IndexedDB implementation can be had for roughly the price of a side of fries at a fancy pub.

So where does this project go next? If this was five years ago, and I had a halway-decent IndexedDB implementation in my hands, I’d open source it, publish to npm, accept PRs, etc. As is, I don’t really see the point. You can have a better version of the code yourself if you make it two-shot rather than one-shot. Or you can think of a better one-shot. Or you can build it on top of LevelDB or Rust or whatever you want. This is kind of what I was getting at in “The fate of ‘small’ open source”, although the definition of “small” seems to be growing every day.

How do I feel about this? Not great, to be honest. I poured tons of time into fake-indexeddb in the last year, using no AI at all (just my own feeble primate intelligence). I enjoyed the experience and don’t regret it, but experiments like this cheapen the efforts I’ve made over the years. It reduces the value of things. I think this is partly why so many of us have a knee-jerk reaction to reject these tools: if they work, then they’re frankly insulting.

However, I don’t think I or anyone else can wish LLMs away. Given their capabilities, it seems pretty clear that they’re going to become a core part of building software in the future. Maybe that’ll be good, maybe it’ll be bad, but their dominance seems inevitable to me now. I’m trying to not be so glum about it, though: if you follow some “AI influencers” like Matt Pocock, Simon Willison, and Steve Yegge, they seem to be having a tremendous amount of fun. As my former Edge colleague Kyle Pflug said recently:

AI-first development is making it once again joyful and eminently possible for anyone to create on the Web. It’s a feeling I’ve missed since View Source became illegible, and a silver lining that’s arriving just in time.

As a middle-aged fuddy-duddy trying to understand what all these kids are excited about, I have to agree. Even if vibe coding doesn’t feel particularly joyful to me right now, I can see why others like it a lot: it gives you a tremendous amount of creative power and dramatically lowers the barrier to entry. Simon Willison predicts that we’ll see a production-grade web browser built by a small team with AI by 2029. I wouldn’t bet against him on that.

An experiment in vibe coding

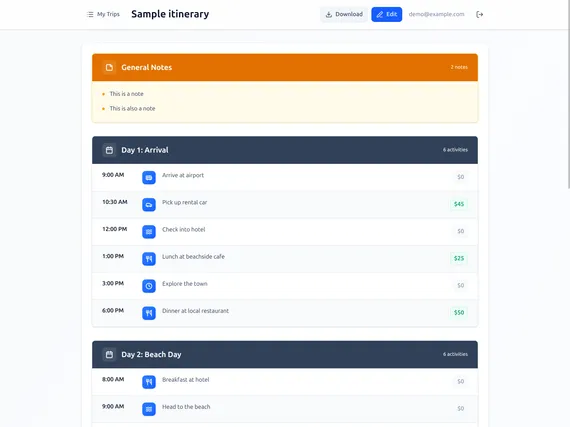
For the holidays, I gave myself a little experiment: build a small web app for my wife to manage her travel itineraries. I challenged myself to avoid editing the code myself and just do it “vibe” style, to see how far I could get.

In the end, the app was built with a $20 Claude “pro” plan and maybe ~5 hours of actual hands-on-keyboard work. Plus my wife is happy with the result, so I guess it was a success.

Screenshot of a travel itinerary app with a basic UI that looks like a lot of other CRUD apps, with a list of itinerary agenda items, dates and costs, etc.

There are still a lot of flaws with this approach, though, so I thought I’d gather my experiences in this post.

The good

The app works. It looks okay on desktop and mobile, it works as a PWA, it saves her itineraries to a small PocketBase server running on Railway for $1 a month, and I can easily back up the database whenever I feel like it. User accounts can only be created by an admin user, which I manage with the PocketBase UI.

I first started with Bolt.new but quickly switched to Claude Code. I found that Bolt was fine for the first iteration but quickly fell off after that. Every time I asked it to fix something and it failed (slowly), I thought “Claude Code could do this better.” Luckily you can just export from Bolt whenever you feel like it, so that’s what we did.

Bolt set up a pretty basic SPA scaffolding with Vite and React, which was fine, although I didn’t like its choice of Supabase, so I had Claude replace it with PocketBase. Claude was very helpful here with the ideation – I asked for some options on a good self-hosted database and went with PocketBase because it’s open-source and has the admin/auth stuff built-in. Plus it runs on SQLite, so this gave me confidence that import/export would be easy.

Claude also helped a lot with the hosting – I was waffling between a few different choices and eventually landed on Railway per Claude’s suggestion (for better or worse, this seems like a prime opportunity for ads/sponsorships in the future). Claude also helped me decipher the Railway interface and get the app up-and-running, in a way that helped me avoid reading their documentation altogether – all I needed to do was post screenshots and ask Claude where to click.

The app also uses Tailwind, which seems to come with decent CSS styles that look like every other website on the internet. I didn’t need this to win any design awards, so that was fine.

Note I also ran Claude in a Podman container with --dangerously-skip-permissions (aka “yolo mode”) because I didn’t want to babysit it whenever it wanted permission to install or run something. Worst case scenario, an attacker has stolen the app code (meh), so hopefully I kept the lethal trifecta in check.

The bad

Vibe-coding tools are decidedly not ready for non-programmers yet. Initially I tried to just give Bolt to my wife and have her vibe her way through it, but she quickly got frustrated, despite having some experience with HTML, CSS, and WordPress. The LLM would make errors (as they do), but it would get caught in a loop, and nothing she tried could break it out of the cycle.

Since I have a lot of experience building web apps, I could look at the LLM’s mistakes and say, “Oh, this problem is in the backend.” Or “Oh, it should write a parser test for this.” Or, “Oh, it needs a screenshot so it can see why the CSS is wrong.” If you don’t have extensive debugging experience, then you might not be able to succinctly express the problem to an LLM like this. Being able to write detailed bug reports, or even have the right vocabulary to describe the problem, is an invaluable skill here.

After handing it over from Bolt to Claude Code and taking the reigns myself, though, I still ran into plenty of problems. First off, LLMs still suck at accessibility – lots of <div>s with onClick all over the place. My wife is a sighted mouse user so it didn’t really matter, but I still have some professional pride even around vibe-coded garbage, so I told Claude to correct it. (At which point it promptly added excessive aria-labels where they weren’t needed, so I told it to dial it back.) I’m not the first to note this, but this really doesn’t bode well for accessible vibe-coded apps.

Another issue was performance. Even on a decent laptop (my Framework 13 with AMD Ryzen 5), I noticed a lot of slow interactions (typing, clicking) due to React re-rendering. This required a lot of back-and-forth with the agent, copy-pasting from the Chrome DevTools Performance tab and React DevTools Profiler, to get it to understand the problem and fix it with memoization and nested components.

At some point I realized I should just enable the React Compiler, and this may have helped but didn’t fully solve the problem. I’m frankly surprised at how bad React is for this use case, since a lot of people seem convinced that the framework wars are over, since LLMs are so “good” at writing React. The next time I try this, I might use a framework like Svelte or Solid where fine-grained reactivity is built-in, and you don’t need a lot of manual optimizations for this kind of stuff.

Other than that, I didn’t run into any major problems that couldn’t be solved with the right prompting. For instance, to add PWA capabilities, it was enough to tell the LLM: “Make an icon that kind of looks like an airplane, generate the proper PNG sizes, here are the MDN docs on PWA manifests.” I did need to follow up by copy-pasting some error messages from the Chrome DevTools (which required even knowing to look in the Application tab), but that resolved itself quickly. I got it to generate a CSP in a similar way.

The only other annoying problem was the token limits – this is something I don’t have to deal with at work, and I was surprised how quickly I ran into limits using Claude as a side project. It made me tempted to avoid “plan mode” even when it would have been the better choice, and I often had to just set Claude aside and wait for my limit to “reset.”

The ugly

The ugliest part of all this is, of course, the cheapening of the profession as well as all the other ills of LLMs and GenAI that have been well-documented elsewhere. My contribution to this debate is just to document how I feel, which is that I’m somewhat horrified by how easily this tool can reproduce what took me 20-odd years to learn, but I’m also somewhat excited because it’s never been easier to just cobble together some quick POCs or lightweight hobby apps.

After a couple posts on this topic, I’ve decided that my role is not to try to resist the overwhelming onslaught of this technology, but instead to just witness and document how it’s shaking up my worldview and my corner of the industry. Of course some will label me a collaborator, but I think those voices are increasingly becoming marginalized by an industry that has just normalized the use of generative AI to write code.

When I watch some of my younger colleagues work, I am astounded by how “AI-native” their behavior is. It infuses parts of their work where I still keep a distance. (E.g. my IDE and terminal are sacred to me – I like Claude Code in its little box, not in a Warp terminal or as inline IDE completions.)

Conclusion

The most interesting part of this whole experiment, to me, is that throwing together this hobby app has removed the need for my wife to try some third-party service like TripIt or Wanderlog. She tried those apps, but immediately became frustrated with bugs, missing features, and ad bloat. Whereas the app I built works exactly to her specification – and if she doesn’t like something, I can plug her feedback into Claude Code and have it fixed.

My wife is a power user, and she’s spent a lot of time writing emails to the customer support departments of various apps, where she inevitably gets a “your feedback is very important to us” followed by zilch. She’s tried a lot of productivity/todo/planning apps, and she always finds some awful showstopper bugs (like memory leaks, errors copy/pasting, etc.), which I blame on our industry just not taking quality very seriously. Whereas if there’s a bug in this app, it’s a very small codebase, it’s got extensive unit/end-to-end tests, and so Claude doesn’t have many problems fixing tiny quality-of-life bugs.

I’m not saying this is the death-knell of small note-taking apps or whatever, but I definitely think that vibe-coded hobby apps have some advantages in this space. They don’t have to add 1,000 features to satisfy 1,000 different users (with all the bugs that inevitably come from the combinatorial explosion of features) – they just have to make one person happy. I still think that generative UI is kind of silly, because most users don’t want to wait seconds (or even minutes) for their UI to be built, but it does work well in this case (where your husband is a professional programmer with spare time during the holidays).

For my regular dayjob, I have no intention to do things fully “vibe-coded” (in the sense that I barely look at the code) – that’s just too risky and irresponsible in my opinion. When the code is complex, your teammates need to understand it, and you have paying customers, the bar is just a lot higher. But vibe coding is definitely useful for hobby or throwaway projects.

For better or worse, the value of code itself seems to be dropping precipitously, to be replaced by measures like how well an LLM can understand the codebase (CLAUDE.md, AGENTS.md) or how easily it can test its “fixes” (unit/integration tests). I have no idea what coding will look like next year, but I know how my wife will be planning our next vacation.

The <time> element should actually do something

A common UI pattern is something like this:

Post published 4 hours ago

People do lots of stuff with that “4 hours ago.” They might make it a permalink:

Post published <a href="/posts/123456">4 hours ago</a>

Or they might give it a tooltip to show the exact datetime upon hover/focus:

Post published
<Tooltip content="December 14, 2025 at 11:30 AM PST">
  4 hours ago
</Tooltip>

If you’re a pedant about HTML though (like me), then you might use the <time> element:

Post published
<time datetime="2025-12-14T19:30:00.000Z">
  4 hours ago
</time>

This is great! We now have a semantic way to express the exact timestamp of a date. So browsers and screen readers should use this and give us a way to avoid those annoying manual tooltips and… oh wait, no. The <time> element does approximately nothing.

I did some research on this and couldn’t find any browser or assistive technology that actually makes use of the <time> element, besides, you know, rendering it. (Whew!) This is despite the fact that <time> is used on roughly 8% of pageloads per Chrome’s usage tracker.

So what does <time> actually do? As near as I can tell, it’s used by search engines to show date snippets in search results. However, I can’t find any guidelines from Google that specifically advocate for the <time> element, although there is a 2023 post from Search Engine Journal which quotes a Google Search liaison:

Google doesn’t depend on a single date factor because all factors can be prone to issues. That’s why our systems look at several factors to determine our best estimate of when a page was published or significantly updated.

In fact, the only Google documentation I found doesn’t mention <time> at all, and instead recommends using Schema.org’s datePublished and dateModified fields. (I.e., not even HTML.)

So there it is. <time> is a neat idea in theory, but in practice it feels like an unfulfilled promise of semantic HTML. A 2010 CSS Tricks article has a great quote about this from Bruce Lawson (no relation):

The uses of unambiguous dates in web pages aren’t hard to imagine. A browser could offer to add events to a user’s calendar. A Thai-localised browser could offer to transform Gregorian dates into Thai Buddhist era dates. A Japanese browser could localise to “16:00時”.

This would be amazing, and I’d love to see browsers and screen readers make use of <time> like this. But for now, it’s just kind of an inert relic of the early HTML5 days. I’ll still use it, though, because (as Marge Simpson would say), I just think it’s neat.

Why do browsers throttle JavaScript timers?

Even if you’ve been doing JavaScript for a while, you might be surprised to learn that setTimeout(0) is not really setTimeout(0). Instead, it could run 4 milliseconds later:

const start = performance.now()
setTimeout(() => {
  // Likely 4ms
  console.log(performance.now() - start)
}, 0)

Nearly a decade ago when I was on the Microsoft Edge team, it was explained to me that browsers did this to avoid “abuse.” I.e. there are a lot of websites out there that spam setTimeout, so to avoid draining the user’s battery or blocking interactivity, browsers set a special “clamped” minimum of 4ms.

This also explains why some browsers would bump the throttling for devices on battery power (16ms in the case of legacy Edge), or throttle even more aggressively for background tabs (1 second in Chrome!).

One question always vexed me, though: if setTimeout was so abused, then why did browsers keep introducing new timers like setImmediate (RIP), Promises, or even new fanciness like scheduler.postTask()? If setTimeout had to be nerfed, then wouldn’t these timers suffer the same fate eventually?

I wrote a long post about JavaScript timers back in 2018, but until recently I didn’t have a good reason to revisit this question. Then I was doing some work on fake-indexeddb, which is a pure-JavaScript implementation of the IndexedDB API, and this question reared its head. As it turns out, IndexedDB wants to auto-commit transactions when there’s no outstanding work in the event loop – in other words, after all microtasks have finished, but before any tasks (can I cheekily say “macro-tasks”?) have started.

To accomplish this, fake-indexeddb was using setImmediate in Node.js (which shares some similarities with the legacy browser version) and setTimeout in the browser. In Node, setImmediate is kind of perfect, because it runs after microtasks but immediately before any other tasks, and without clamping. In the browser, though, setTimeout is pretty sub-optimal: in one benchmark, I was seeing Chrome take 4.8 seconds for something that only took 300 milliseconds in Node (a 16x slowdown!).

Looking out at the timer landscape in 2025, though, it wasn’t obvious what to choose. Some options included:

  • setImmediate – only supported in legacy Edge and IE, so that’s a no-go.
  • MessageChannel.postMessage – this is the technique used by afterframe.
  • window.postMessage – a nice idea, but kind of janky since it might interfere with other scripts on the page using the same API. This approach is used by the setImmediate polyfill though.
  • scheduler.postTask – if you read no further, this was the winner. But let’s explain why!

To compare these options, I wrote a quick benchmark. A few important things about this benchmark:

  1. You have to run several iterations of setTimeout (and friends) to really suss out the clamping. Technically, per the HTML specification, the 4ms clamping is only supposed to kick in after a setTimeout has been nested (i.e. one setTimeout calls another) 5 times.
  2. I didn’t test every possible combination of 1) battery vs plugged in, 2) monitor refresh rates, 3) background vs foreground tabs, etc., even though I know all of these things can affect the clamping. I have a life, and although it’s fun to don the lab coat and run some experiments, I don’t want to spend my entire Saturday doing that.

In any case, here are the numbers (in milliseconds, median of 101 iterations, on a 2021 16-inch MacBook Pro):

Browser setTimeout MessageChannel window scheduler.postTask
Chrome 139 4.2 0.05 0.03 0.00
Firefox 142 4.72 0.02 0.01 0.01
Safari 18.4 26.73 0.52 0.05 Not implemented

Don’t worry about the precise numbers too much: the point is that Chrome and Firefox clamp setTimeout to 4ms, and the other three options are roughly equivalent. In Safari, interestingly, setTimeout is even more heavily throttled, and MessageChannel.postMessage is a tad slower than window.postMessage (although window.postMessage is still janky for the reasons listed above).

This experiment answered my immediate question: fake-indexeddb should use scheduler.postTask (which I prefer for its ergonomics) and fall back to either MessageChannel.postMessage or window.postMessage. (I did experiment with different priorities for postTask, but they all performed almost identically. For fake-indexeddb‘s use case, the default priority of 'user-visible' seemed most appropriate, and that’s what the benchmark uses.)

None of this answered my original question, though: why exactly do browsers bother to throttle setTimeout if web developers can just use scheduler.postTask or MessageChannel instead? I asked my friend Todd Reifsteck, who was co-chair of the Web Performance Working Group back when a lot of these discussions about “interventions” were underway.

He said that there were effectively two camps: one camp felt that timers needed to be throttled to protect web devs from themselves, whereas the other camp felt that developers should “measure their own silliness,” and that any subtle throttling heuristics would just cause confusion. In short, it was the standard tradeoff in designing performance APIs: “some APIs are quick but come with footguns.”

This jibes with my own intuitions on the topic. Browser interventions are usually put in place because web developers have either used too much of a good thing (e.g. setTimeout), or were blithely unaware of better options (the touch listener controversy is a good example). In the end, the browser is a “user agent” acting on the user’s behalf, and the W3C’s priority of constituencies makes it clear that end-user needs always trump web developer needs.

That said, web developers often do want to do the right thing. (I consider this blog post an attempt in that direction.) We just don’t always have the tools to do it, so instead we grab whatever blunt instrument is nearby and start swinging. Giving us more control over tasks and scheduling could avoid the need to hammer away with setTimeout and cause a mess that calls for an intervention.

My prediction is that postTask/postMessage will remain unthrottled for the time being. Out of Todd’s two “camps,” the very existence of the Scheduler API, which offers a whole slew of fine-grained tools for task scheduling, seems to point toward the “pro-control” camp as the one currently steering the ship. Although Todd sees the API more as a compromise between the two groups: yes, it offers a lot of control, but it also aligns with the browser’s actual rendering pipeline rather than random timeouts.

The pessimist in me wonders, though, if the API could still be abused – e.g. by carelessly using the user-blocking priority everywhere. Perhaps in the future, some enterprising browser vendor will put their foot more firmly on the throttle (so to speak) and discover that it causes websites to be snappier, more responsive, and less battery-draining. If that happens, then we may see another round of interventions. (Maybe we’ll need a scheduler2 API to dig ourselves out of that mess!)

I’m not involved much in web standards anymore and can only speculate. For the time being, I’ll just do what most web devs do: choose whatever API accomplishes my goals today, and hope that browsers don’t change too much in the future. As long as we’re careful and don’t introduce too much “silliness,” I don’t think that’s a lot to ask.

Thanks to Todd Reifsteck for feedback on a draft of this post.

Selfish reasons for building accessible UIs

All web developers know, at some level, that accessibility is important. But when push comes to shove, it can be hard to prioritize it above a bazillion other concerns when you’re trying to center a <div> and you’re on a tight deadline.

A lot of accessibility advocates lead with the moral argument: for example, that disabled people should have just as much access to the internet as any other person, and that it’s a blight on our whole industry that we continually fail to make it happen.

I personally find these arguments persuasive. But experience has also taught me that “eat your vegetables” is one of the least effective arguments in the world. Scolding people might get them to agree with you in public, or even in principle, but it’s unlikely to change their behavior once no one’s watching.

So in this post, I would like to list some of my personal, completely selfish reasons for building accessible UIs. No finger-wagging here: just good old hardheaded self-interest!

Debuggability

When I’m trying to debug a web app, it’s hard to orient myself in the DevTools if the entire UI is “div soup”:

<div class="css-1x2y3z4">
  <div class="css-c6d7e8f">
    <div class="css-a5b6c7d">
      <div class="css-e8f9g0h"></div>
      <div class="css-i1j2k3l">Library</div>
      <div class="css-i1j2k3l">Version</div>
      <div class="css-i1j2k3l">Size</div>
    </div>
  </div>
  <div class="css-c6d7e8f">
    <div class="css-m4n5o6p">
      <div class="css-q7r8s9t">UI</div>
      <div class="css-u0v1w2x">React</div>
      <div class="css-u0v1w2x">19.1.0</div>
      <div class="css-u0v1w2x">167kB</div>
    </div>
    <div class="css-m4n5o6p">
      <div class="css-q7r8s9t">Style</div>
      <div class="css-u0v1w2x">Tailwind</div>
      <div class="css-u0v1w2x">4.0.0</div>
      <div class="css-u0v1w2x">358kB</div>
    </div>
    <div class="css-m4n5o6p">
      <div class="css-q7r8s9t">Build</div>
      <div class="css-u0v1w2x">Vite</div>
      <div class="css-u0v1w2x">6.3.5</div>
      <div class="css-u0v1w2x">2.65MB</div>
    </div>
  </div>
</div>

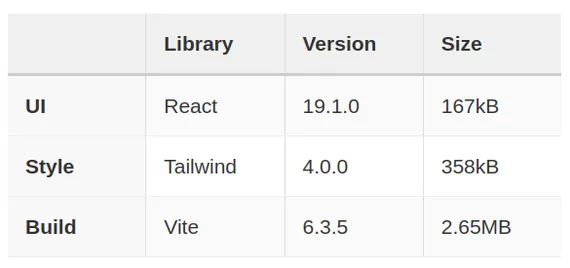
This is actually a table, but you wouldn’t know it from looking at the HTML:

Screenshot of an HTML table with column headers library, version, and size, row headers UI, style, and build, and values React/Tailwind/Vite with their version numbers and build size in the cells.

If I’m trying to debug this in the DevTools, I’m completely lost. Where are the rows? Where are the columns?

<table class="css-1x2y3z4">
  <thead class="css-a5b6c7d">
    <tr class="css-y3z4a5b">
      <th scope="col" class="css-e8f9g0h"></th>
      <th scope="col" class="css-i1j2k3l">Library</th>
      <th scope="col" class="css-i1j2k3l">Version</th>
      <th scope="col" class="css-i1j2k3l">Size</th>
    </tr>
  </thead>
  <tbody class="css-a5b6c7d">
    <tr class="css-y3z4a5b">
      <th scope="row" class="css-q7r8s9t">UI</th>
      <td class="css-u0v1w2x">React</td>
      <td class="css-u0v1w2x">19.1.0</td>
      <td class="css-u0v1w2x">167kB</td>
    </tr>
    <tr class="css-y3z4a5b">
      <th scope="row" class="css-q7r8s9t">Style</th>
      <td class="css-u0v1w2x">Tailwind</td>
      <td class="css-u0v1w2x">4.0.0</td>
      <td class="css-u0v1w2x">358kB</td>
    </tr>
    <tr class="css-y3z4a5b">
      <th scope="row" class="css-q7r8s9t">Build</th>
      <td class="css-u0v1w2x">Vite</td>
      <td class="css-u0v1w2x">6.3.5</td>
      <td class="css-u0v1w2x">2.65MB</td>
    </tr>
  </tbody>
</table>

Ah, that’s much better! Now I can easily zero in on a table cell, or a column header, because they’re all named. I’m not wading through a sea of <div>s anymore.

Even just adding ARIA roles to the <div>s would be an improvement here:

<div class="css-1x2y3z4" role="table">
  <div class="css-a5b6c7d" role="rowgroup">
    <div class="css-m4n5o6p" role="row">
      <div class="css-e8f9g0h" role="columnheader"></div>
      <div class="css-i1j2k3l" role="columnheader">Library</div>
      <div class="css-i1j2k3l" role="columnheader">Version</div>
      <div class="css-i1j2k3l" role="columnheader">Size</div>
    </div>
  </div>
  <div class="css-c6d7e8f" role="rowgroup">
    <div class="css-m4n5o6p" role="row">
      <div class="css-q7r8s9t" role="rowheader">UI</div>
      <div class="css-u0v1w2x" role="cell">React</div>
      <div class="css-u0v1w2x" role="cell">19.1.0</div>
      <div class="css-u0v1w2x" role="cell">167kB</div>
    </div>
    <div class="css-m4n5o6p" role="row">
      <div class="css-q7r8s9t" role="rowheader">Style</div>
      <div class="css-u0v1w2x" role="cell">Tailwind</div>
      <div class="css-u0v1w2x" role="cell">4.0.0</div>
      <div class="css-u0v1w2x" role="cell">358kB</div>
    </div>
    <div class="css-m4n5o6p" role="row">
      <div class="css-q7r8s9t" role="rowheader">Build</div>
      <div class="css-u0v1w2x" role="cell">Vite</div>
      <div class="css-u0v1w2x" role="cell">6.3.5</div>
      <div class="css-u0v1w2x" role="cell">2.65MB</div>
    </div>
  </div>
</div>

Especially if you’re using a CSS-in-JS framework (which I’ve simulated with robo-classes above), the HTML can get quite messy. Building accessibly makes it a lot easier to understand at a distance what each element is supposed to do.

Naming things

As all programmers know, naming things is hard. UIs are no exception: is this an “autocomplete”? Or a “dropdown”? Or a “picker”?

Screenshot of a combobox with "Ne" typed into it and states below in a list like Nebraska, Nevada, and New Hampshire.

If you read the WAI ARIA guidelines, though, then it’s clear what it is: a “combobox”!

No need to grope for the right name: if you add the proper roles, then everything is already named for you:

  • combobox
  • listbox
  • options

As a bonus, you can use aria-* attributes or roles as a CSS selector. I often see awkward code like this:

<div
  className={isActive ? 'active' : ''}
  aria-selected={isActive}
  role='option'
</div>

The active class is clearly redundant here. If you want to style based on the .active selector, you could just as easily style with [aria-selected="true"] instead.

Also, why call it isActive when the ARIA attribute is aria-selected? Just call it “selected” everywhere:

<div
  aria-selected={isSelected}
  role='option'
</div>

Much cleaner!

I also find that thinking in terms of roles and ARIA attributes sharpens my thinking, and gives structure to the interface I’m trying to create. Suddenly, I have a language for what I’m building, which can lead to more “obvious” variable names, CSS custom properties, grid area names, etc.

Testability

I’ve written about this before, but building accessibly also helps with writing tests. Rather than trying to select an element based on arbitrary classes or attributes, you can write more elegant code like this (e.g. with Playwright):

await page.getByLabel('Name').fill('Nolan')

await page.getByRole('button', { name: 'OK' }).click()

Imagine, though, if your entire UI is full of <div>s and robo-classes. How would you find the right inputs and buttons? You could select based on the robo-classes, or by searching for text inside or nearby the elements, but this makes your tests brittle.

As Kent C. Dodds has argued, writing UI tests based on semantics makes your tests more resilient to change. That’s because a UI’s semantic structure (i.e. the accessibility tree) tends to change less frequently than its classes, attributes, or even the composition of its HTML elements. (How many times have you added a wrapper <div> only to break your UI tests?)

Power users

When I’m on a desktop, I tend to be a keyboard power user. I like pressing Esc to close dialogs, Enter to submit a form, or even / in Firefox to quickly jump to links on the page. I do use a mouse, but I just prefer the keyboard since it’s faster.

So I find it jarring when a website breaks keyboard accessibility – Esc doesn’t dismiss a dialog, Enter doesn’t submit a form, ↑/↓ don’t change radio buttons. It disrupts my flow when I unexpectedly have to reach for my mouse. (Plus it’s a Van Halen brown M&M that signals to me that the website probably messed something else up, too!)

If you’re building a productivity tool with its own set of keyboard shortcuts (think Slack or GMail), then it’s even more important to get this right. You can’t add a lot of sophisticated keyboard controls if the basic Tab and focus logic doesn’t work correctly.

A lot of programmers are themselves power users, so I find this argument pretty persuasive. Build a UI that you yourself would like to use!

Conclusion

The reason that I, personally, care about accessibility is probably different from most people’s. I have a family member who is blind, and I’ve known many blind or low-vision people in my career. I’ve heard firsthand how frustrating it can be to use interfaces that aren’t built accessibly.

Honestly, if I were disabled, I would probably think to myself, “computer programmers must not care about me.” And judging from the miserable WebAIM results, I’d clearly be right:

Across the one million home pages, 50,960,288 distinct accessibility errors were detected—an average of 51 errors per page.

As a web developer who has dabbled in accessibility, though, I find this situation tragic. It’s not really that hard to build accessible interfaces. And I’m not talking about “ideal” or “optimized” – the bar is pretty low, so I’m just talking about something that works at all for people with a disability.

Maybe in the future, accessible interfaces won’t require so much manual intervention from developers. Maybe AI tooling (on either the production or consumption side) will make UIs that are usable out-of-the-box for people with disabilities. I’m actually sympathetic to the Jakob Nielsen argument that “accessibility has failed” – it’s hard to look at the WebAIM results and come to any other conclusion. Maybe the “eat your vegetables” era of accessibility has failed, and it’s time to try new tactics.

That’s why I wrote this post, though. You can build accessibly without having a bleeding heart. And for the time being, unless generative AI swoops in like a deus ex machina to save us, it’s our responsibility as interface designers to do so.

At the same time we’re helping others, though, we can also help ourselves. Like a good hot sauce on your Brussels sprouts, eating your vegetables doesn’t always have to be a chore.

Avoiding unnecessary cleanup work in disconnectedCallback

In a previous post, I said that a web component’s connectedCallback and disconnectedCallback should be mirror images of each other: one for setup, the other for cleanup.

Sometimes, though, you want to avoid unnecessary cleanup work when your component has merely been moved around in the DOM:

div.removeChild(component)
div.insertBefore(component, null)

This can happen when, for example, your component is one element in a list that’s being re-sorted.

The best pattern I’ve found for handling this is to queue a microtask in disconnectedCallback before checking this.isConnected to see if you’re still disconnected:

async disconnectedCallback() {
  await Promise.resolve()
  if (!this.isConnected) {
    // cleanup logic
  }
}

Of course, you’ll also want to avoid repeating your setup logic in connectedCallback, since it will fire as well during a reconnect. So a complete solution would look like:

connectedCallback() {
  // setup logic
  this._isSetUp = true
}

async disconnectedCallback() {
  await Promise.resolve()
  if (!this.isConnected && this._isSetUp) {
    // cleanup logic
    this._isSetUp = false
  }
}

For what it’s worth, Solid, Svelte, and Vue all use this pattern when compiled as web components.

If you’re clever, you might think that you don’t need the microtask, and can merely check this.isConnected. However, this only works in one particular case: if your component is inserted (e.g. with insertBefore/appendChild) but not removed first (e.g. with removeChild). In that case, isConnected will be true during disconnectedCallback, which is quite counter-intuitive:

However, this is not the case if removeChild is called during the “move”:

You can’t really predict how your component will be moved around, so sadly you have to handle both cases. Hence the microtask.

In the future, this may change slightly. There is a proposal to add a new moveBefore method, which would invoke a special connectedMoveCallback. However, this is still behind a flag in Chromium, and the API has not been finalized, so I’ll avoid commenting on it further.

Why I’m skeptical of rewriting JavaScript tools in “faster” languages

I’ve written a lot of JavaScript. I like JavaScript. And more importantly, I’ve built up a set of skills in understanding, optimizing, and debugging JavaScript that I’m reluctant to give up on.

So maybe it’s natural that I get a worried pit in my stomach over the current mania to rewrite every Node.js tool in a “faster” language like Rust, Zig, Go, etc. Don’t get me wrong – these languages are cool! (I’ve got a copy of the Rust book on my desk right now, and I even contributed a bit to Servo for fun.) But ultimately, I’ve invested a ton of my career in learning the ins and outs of JavaScript, and it’s by far the language I’m most comfortable with.

So I acknowledge my bias (and perhaps over-investment in one skill set). But the more I think about it, the more I feel that my skepticism is also justified by some real objective concerns, which I’d like to cover in this post.

Performance

One reason for my skepticism is that I just don’t think we’ve exhausted all the possibilities of making JavaScript tools faster. Marvin Hagemeister has done an excellent job of demonstrating this, by showing how much low-hanging fruit there is in ESLint, Tailwind, etc.

In the browser world, JavaScript has proven itself to be “fast enough” for most workloads. Sure, WebAssembly exists, but I think it’s fair to say that it’s mostly used for niche, CPU-intensive tasks rather than for building a whole website. So why are JavaScript-based CLI tools rushing to throw JavaScript away?

The big rewrite

I think the perf gap comes from a few different things. First, there’s the aforementioned low-hanging fruit – for a long time, the JavaScript tooling ecosystem has been focused on building something that works, not something fast. Now we’ve reached a saturation point where the API surface is mostly settled, and everyone just wants “the same thing, but faster.” Hence the explosion of new tools that are nearly drop-in replacements for existing ones: Rolldown for Rollup, Oxlint for ESLint, Biome for Prettier, etc.

However, these tools aren’t necessarily faster because they’re using a faster language. They could just be faster because 1) they’re being written with performance in mind, and 2) the API surface is already settled, so the authors don’t have to spend development time tinkering with the overall design. Heck, you don’t even need to write tests! Just use the existing test suite from the previous tool.

In my career, I’ve often seen a rewrite from A to B resulting in a speed boost, followed by the triumphant claim that B is faster than A. However, as Ryan Carniato points out, a rewrite is often faster just because it’s a rewrite – you know more the second time around, you’re paying more attention to perf, etc.

Bytecode and JIT

The second class of performance gaps comes from the things browsers give us for free, and that we rarely think about: the bytecode cache and JIT (Just-In-Time compiler).

When you load a website for the second or third time, if the JavaScript is cached correctly, then the browser doesn’t need to parse and compile the source code into bytecode anymore. It just loads the bytecode directly off disk. This is the bytecode cache in action.

Furthermore, if a function is “hot” (frequently executed), it will be further optimized into machine code. This is the JIT in action.

In the world of Node.js scripts, we don’t get the benefits of the bytecode cache at all. Every time you run a Node script, the entire script has to be parsed and compiled from scratch. This is a big reason for the reported perf wins between JavaScript and non-JavaScript tooling.

Thanks to the inimitable Joyee Cheung, though, Node is now getting a compile cache. You can set an environment variable and immediately get faster Node.js script loads:

export NODE_COMPILE_CACHE=~/.cache/nodejs-compile-cache

I’ve set this in my ~/.bashrc on all my dev machines. I hope it makes it into the default Node settings someday.

As for JIT, this is another thing that (sadly) most Node scripts can’t really benefit from. You have to run a function before it becomes “hot,” so on the server side, it’s more likely to kick in for long-running servers than for one-off scripts.

And the JIT can make a big difference! In Pinafore, I considered replacing the JavaScript-based blurhash library with a Rust (Wasm) version, before realizing that the performance difference was erased by the time we got to the fifth iteration. That’s the power of the JIT.

Maybe eventually a tool like Porffor could be used to do an AOT (Ahead-Of-Time) compilation of Node scripts. In the meantime, though, JIT is still a case where native languages have an edge on JavaScript.

I should also acknowledge: there is a perf hit from using Wasm versus pure-native tools. So this could be another reason native tools are taking the CLI world by storm, but not necessarily the browser frontend.

Contributions and debuggability

I hinted at it earlier, but this is the main source of my skepticism toward the “rewrite it all in native” movement.

JavaScript is, in my opinion, a working-class language. It’s very forgiving of types (this is one reason I’m not a huge TypeScript fan), it’s easy to pick up (compared to something like Rust), and since it’s supported by browsers, there is a huge pool of people who are conversant with it.

For years, we’ve had both library authors and library consumers in the JavaScript ecosystem largely using JavaScript. I think we take for granted what this enables.

For one: the path to contribution is much smoother. To quote Matteo Collina:

Most developers ignore the fact that they have the skills to debug/fix/modify their dependencies. They are not maintained by unknown demigods but by fellow developers.

This breaks down if JavaScript library authors are using languages that are different (and more difficult!) than JavaScript. They may as well be demigods!

For another thing: it’s straightforward to modify JavaScript dependencies locally. I’ve often tweaked something in my local node_modules folder when I’m trying to track down a bug or work on a feature in a library I depend on. Whereas if it’s written in a native language, I’d need to check out the source code and compile it myself – a big barrier to entry.

(To be fair, this has already gotten a bit tricky thanks to the widespread use of TypeScript. But TypeScript is not too far from the source JavaScript, so you’d be amazed how far you can get by clicking “pretty print” in the DevTools. Thankfully most Node libraries are also not minified.)

Of course, this also leads us back to debuggability. If I want to debug a JavaScript library, I can simply use the browser’s DevTools or a Node.js debugger that I’m already familiar with. I can set breakpoints, inspect variables, and reason about the code as I would for my own code. This isn’t impossible with Wasm, but it requires a different skill set.

Conclusion

I think it’s great that there’s a new generation of tooling for the JavaScript ecosystem. I’m excited to see where projects like Oxc and VoidZero end up. The existing incumbents are indeed exceedingly slow and would probably benefit from the competition. (I get especially peeved by the typical eslint + prettier + tsc + rollup lint+build cycle.)

That said, I don’t think that JavaScript is inherently slow, or that we’ve exhausted all the possibilities for improving it. Sometimes I look at truly perf-focused JavaScript, such as the recent improvements to the Chromium DevTools using mind-blowing techniques like using Uint8Arrays as bit vectors, and I feel that we’ve barely scratched the surface. (If you really want an inferiority complex, see other commits from Seth Brenith. They are wild.)

I also think that, as a community, we have not really grappled with what the world would look like if we relegate JavaScript tooling to an elite priesthood of Rust and Zig developers. I can imagine the average JavaScript developer feeling completely hopeless every time there’s a bug in one of their build tools. Rather than empowering the next generation of web developers to achieve more, we might be training them for a career of learned helplessness. Imagine what it will feel like for the average junior developer to face a segfault rather than a familiar JavaScript Error.

At this point, I’m a senior in my career, so of course I have little excuse to cling to my JavaScript security-blanket. It’s part of my job to dig down a few layers deeper and understand how every part of the stack works.

However, I can’t help but feel like we are embarking down an unknown path with unintended consequences, when there is another path that is less fraught and could get us nearly the same results. The current freight train shows no signs of slowing down, though, so I guess we’ll find out when we get there.