Every so often, the web development community gets into a tizzy about something, usually web components. I find these fights tiresome, but I also see them as a good opportunity to reach across “the great divide” and try to find common ground rather than another opportunity to dunk on each other.
I’ve been an avid follower of Ryan Carniato’s work for years. This post and the steady climb of LWC on the js-framework-benchmark demonstrate that I’ve been paying attention to what he has to say, especially about performance and framework design. The guy has single-handedly done more to move the web framework ecosystem forward in the past 5 years than anyone else I can think of.
So obviously I’m going to be interested when I see a post from Ryan Carniato on web components. And it’s a thought-provoking post! But I also think he misses the mark on a few things. So let’s dive in:
Performance
[T]he fundamental problem with Web Components is that they are built on Custom Elements.
[…] [E]very interface needs to go through the DOM. And of course this has a performance overhead.
This is completely true. If your goal is to build the absolute fastest framework you can, then you want to minimize DOM nodes wherever possible. This means that web components are off the table.
I fully believe that Ryan knows how to build the fastest possible framework. Again, the results for Solid on the js-framework-benchmark are a testament to this.
That said – and I might alienate some of my friends in the web performance community by saying this – performance isn’t everything. There are other tradeoffs in software development, such as maintainability, security, usability, and accessibility. Sometimes these things come into conflict.
To make a silly example: I could make DOM rendering slightly faster by never rendering any aria-* attributes. But of course sometimes you have to render aria-* attributes to make your interface accessible, and nobody would argue that a couple milliseconds are worth excluding screen reader users.
To make an even sillier example: you can improve performance by using for loops instead of .forEach(). Or using var instead of const/let. Typically, though, these kinds of micro-optimizations are just not worth it.
When I see this kind of stuff, I’m reminded of speedrunners trying to shave milliseconds off a 5-minute run of Super Mario Bros using precise inputs and obscure glitches. If that’s your goal, then by all means: backwards long jump across the entire stage instead of just having Mario run forward. I’ll continue to be impressed by what you’re doing, but it’s just not for me.
Minimizing the use of DOM nodes is a classic optimization – this is the main idea behind virtualization. That said, sometimes you can get away with simpler approaches, even if it’s not the absolute fastest option. I’d put “components as elements” in the same bucket – yes it’s sub-optimal, but optimal is not always the goal.
Similarly, I’ve long argued that it’s fine for custom elements to use different frameworks. Sometimes you just need to gradually migrate from Framework A to Framework B. Or you have to compose some micro-frontends together. Nobody would argue that this is the fastest possible interface, but fine – sometimes tradeoffs have to be made.
Having worked for a long time in the web performance space, I find that the lowest-hanging fruit for performance is usually something dumb like layout thrashing, network waterfalls, unnecessary re-renders, etc. Framework authors like myself love to play performance golf with things like the js-framework-benchmark, and it’s a great flex, but it just doesn’t usually matter in the real world.
That said, if it does matter to you – if you’re building for resource-constrained environments where every millisecond counts: great! Ditch web components! I will geek out and cheer for every speedrunning record you break.
The cost of standards
More code to ship and more code to execute to check these edge cases. It’s a hidden tax that impacts everyone.
Here’s where I completely get off the train from Ryan’s argument. As a framework author, I just don’t find that it’s that much effort to support web components. Detecting props versus attributes is a simple prop in element check. Outputting web components is indeed painful, but hey – nobody said you have to do it. Vue 2 got by with a standalone web component wrapper library, and Remount exists without any input from the React team.
As a framework author, if you want to freeze your thinking in 2011 and code as if nothing new was added to the web platform since then, you absolutely can! And you can still write a great framework! This is the beauty of the web. jQuery v1 is still chugging away on plenty of websites, and in fact it gets faster and faster with every new browser release, since browser perf teams are often targeting whatever patterns web developers used ~5 year ago in an endless cat-and-mouse game.
But assuming you don’t want to freeze your brain in amber, then yes: you do need to account for new stuff added to the web platform. But this is also true of things like Symbols, Proxys, Promises, etc. I just see it as part of the job, and I’m not particularly bothered, since I know that whatever I write will still work in 10 years, thanks to the web’s backwards compatibility guarantees.
Furthermore, I get the impression that a wide swath of the web development community does not care about web components, does not want to support them, and you probably couldn’t convince them to. And that’s okay! The web is a big tent, and you can build entire UIs based on web components, or with a sprinkling of HTML web components, or with none at all. If you want to declare your framework a “no web components” zone, then you can do that and still get plenty of avid fans.
That said, Ryan is right that, by blessing something as “the standard,” it inherently becomes a mental default that needs to be grappled with. Component authors must decide whether their <slot>s should work like native <slot>s. That’s true, but again, you could say this about a lot of new browser APIs. You have to decide whether IntersectionObserver or <img loading="lazy"> is worth it, or whether you’d rather write your own abstraction. That’s fine! At least we have a common point of reference, a shared vocabulary to compare and contrast things.
And just because something is a web standard doesn’t mean you have to use it. For the longest time, the classic joke about JavaScript: The Good Parts was how small it is compared to JavaScript: The Definitive Guide. The web is littered with deprecated (but still supported) APIs like document.domain, with, and <frame>s. Take it or leave it!
Conclusion
[I]n a sense there are nothing wrong with Web Components as they are only able to be what they are. It’s the promise that they are something that they aren’t which is so dangerous.
Here I totally agree with Ryan. As I’ve said before, web components are bad at a lot of things – Server-Side Rendering, accessibility, even interop in some cases. They’re good at plenty of things, but replacing all JavaScript frameworks is not one of them. Maybe we can check back in 10 years, but for now, there are still cases where React, Solid, Svelte, and friends shine and web components flounder.
Ryan is making an eminently reasonable point here, as is the rest of the post, and on its own it’s a good contribution to the discourse. The title is a bit inflammatory, which leads people to wield it as a bludgeon against their perceived enemies on social media (likely without reading the piece), but this is something I blame on social media, not on Ryan.
Again, I find these debates a bit tiresome. I think the fundamental issue, as I’ve previously said, is that people are talking past each other because they’re building different things with different constraints. It’s as if a salsa dancer criticized ballet for not being enough like salsa. There is more than one way to dance!
From my own personal experience: at Salesforce, we build a client-rendered app, with its own marketplace of components, with strict backwards-compatibility guarantees, where the intended support is measured in years if not decades. Is this you? If not, then maybe you shouldn’t build your entire UI out of web components, with shadow DOM and the whole kit-n-kaboodle. (Or maybe you should! I can’t say!)
What I find exciting about the web is the sheer number of people doing so many wild and bizarre things with it. It has everything from games to art projects to enterprise SaaS apps, built with WebGL and Wasm and Service Workers and all sorts of zany things. Every new capability added to the web platform isn’t a limitation on your creativity – it’s an opportunity to express your creativity in ways that nobody imagined before.
Web components may not be the future for you – that’s great! I’m excited to see what you build, and I might steal some ideas for my own corner of the web.
I’m on a fedi instance with 19k custom emojis […] and when I open the emoji picker […], the page freezes for like a full second at least and overall performance stutters for a while after that.
If you’re not familiar with Mastodon or the Fediverse, different servers can have their own custom emoji, similar to Slack, Discord, etc. Having 19k (really closer to 20k in this case) is highly unusual, but not unheard of.
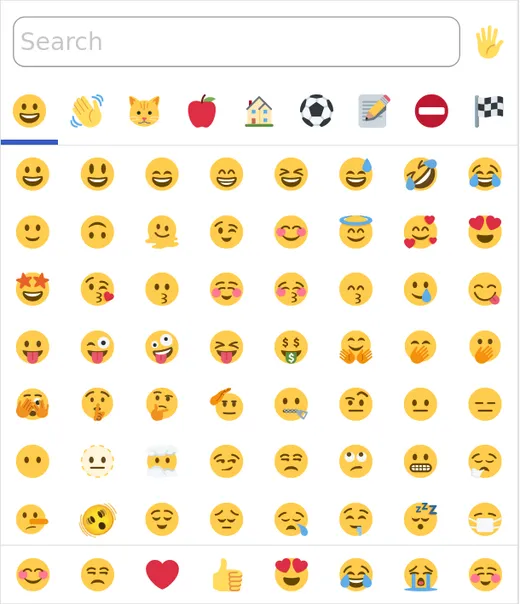
So I booted up their repro, and holy moly, it was slow:
There were multiple things wrong here:
20k custom emoji meant 40k elements, since each one used a <button> and an <img>.
No virtualization was used, so all these elements were just shoved into the DOM.
Now, to my credit, I was using <img loading="lazy">, so those 20k images were not all being downloaded at once. But no matter what, it’s going to be achingly slow to render 40k elements – Lighthouse recommends no more than 1,400!
My first thought, of course, was, “Who the heck has 20k custom emoji?” My second thought was, “*Sigh* I guess I’m going to need to do virtualization.”
I had studiously avoided virtualization in emoji-picker-element, namely because 1) it’s complex, 2) I didn’t think I needed it, and 3) it has implications for accessibility.
I’ve been down this road before: Pinafore is basically one big virtual list. I used the ARIA feed role, did all the calculations myself, and added an option to disable “infinite scroll,” since some people don’t like it. This is not my first rodeo! I was just grimacing at all the code I’d have to write, and wondering about the size impact on my “tiny” ~12kB emoji picker.
After a few days, though, the thought popped into my head: what about CSS content-visibility? I saw from the trace that lots of time is spent in layout and paint, and plus this might help the “stuttering.” This could be a much simpler solution than full-on virtualization.
If you’re not familiar, content-visibility is a new-ish CSS feature that allows you to “hide” certain parts of the DOM from the perspective of layout and paint. It largely doesn’t affect the accessibility tree (since the DOM nodes are still there), it doesn’t affect find-in-page (⌘+F/Ctrl+F), and it doesn’t require virtualization. All it needs is a size estimate of off-screen elements, so that the browser can reserve space there instead.
Luckily for me, I had a good atomic unit for sizing: the emoji categories. Custom emoji on the Fediverse tend to be divided into bite-sized categories: “blobs,” “cats,” etc.
Custom emoji on mastodon.social.
For each category, I already knew the emoji size and the number of rows and columns, so calculating the expected size could be done with CSS custom properties:
These placeholders take up exactly as much space as the finished product, so nothing is going to jump around while scrolling.
The next thing I did was write a Tachometer benchmark to track my progress. (I love Tachometer.) This helped validate that I was actually improving performance, and by how much.
My first stab was really easy to write, and the perf gains were there… They were just a little disappointing.
For the initial load, I got a roughly 15% improvement in Chrome and 5% in Firefox. (Safari only has content-visibility in Technology Preview, so I can’t test it in Tachometer.) This is nothing to sneeze at, but I knew a virtual list could do a lot better!
So I dug a bit deeper. The layout costs were nearly gone, but there were still other costs that I couldn’t explain. For instance, what’s with this big undifferentiated blob in the Chrome trace?
Whenever I feel like Chrome is “hiding” some perf information from me, I do one of two things: bust out chrome:tracing, or (more recently) enable the experimental “show all events” option in DevTools.
This gives you a bit more low-level information than a standard Chrome trace, but without needing to fiddle with a completely different UI. I find it’s a pretty good compromise between the Performance panel and chrome:tracing.
And in this case, I immediately saw something that made the gears turn in my head:
What the heck is ResourceFetcher::requestResource? Well, even without searching the Chromium source code, I had a hunch – could it be all those <img>s? It couldn’t be, right…? I’m using <img loading="lazy">!
Well, I followed my gut and simply commented out the src from each <img>, and what do you know – all those mystery costs went away!
I tested in Firefox as well, and this was also a massive improvement. So this led me to believe that loading="lazy" was not the free lunch I assumed it to be.
At this point, I figured that if I was going to get rid of loading="lazy", I may as well go whole-hog and turn those 40k DOM elements into 20k. After all, if I don’t need an <img>, then I can use CSS to just set the background-image on an ::after pseudo-element on the <button>, cutting the time to create those elements in half.
At this point, it was just a simple IntersectionObserver to add the onscreen class when the category scrolled into view, and I had a custom-made loading="lazy" that was much more performant. This time around, Tachometer reported a ~40% improvement in Chrome and ~35% improvement in Firefox. Now that’s more like it!
I felt good about this solution and shipped it. All told, the benchmark clocked a ~45% improvement in both Chrome and Firefox, and the original repro went from ~3 seconds to ~1.3 seconds. The person who reported the bug even thanked me and said that the emoji picker was much more usable now.
Something still doesn’t sit right with me about this, though. Looking at the traces, I can see that rendering 20k DOM nodes is just never going to be as fast as a virtualized list. And if I wanted to support even bigger Fediverse instances with even more emoji, this solution would not scale.
I am impressed, though, with how much you get “for free” with content-visibility. The fact that I didn’t need to change my ARIA strategy at all, or worry about find-in-page, was a godsend. But the perfectionist in me is still irritated by the thought that, for maximum perf, a virtual list is the way to go.
Maybe eventually the web platform will get a real virtual list as a built-in primitive? There were some efforts at this a few years ago, but they seem to have stalled.
I look forward to that day, but for now, I’ll admit that content-visibility is a good rough-and-ready alternative to a virtual list. It’s simple to implement, gives a decent perf boost, and has essentially no accessibility footguns. Just don’t ask me to support 100k custom emoji!
From left to right: Safari on iOS 17, Firefox 130 on Windows 11, and Chrome 128 on Windows 11.
This, frankly, is a mess. And it’s emblematic of how half-heartedly browsers and operating systems have worked to keep their emoji up to date.
What’s responsible for this sorry state? I gave an overview two years ago, and shockingly little has changed – in fact, it’s gotten a bit worse.
In short:
Firefox bundles their own emoji font (great!), but unfortunately, thanks to turmoil at Twitter/X, their bet on Twemoji has not shaken out too well, and they are two years behind the latest Unicode standard.
Windows 10 users (i.e. 64% of Windows as a whole) are stuck five years behind in emoji versions, and even Windows 11 is still not showing flag emoji, which Microsoft excludes for some mysterious reason. (Geopolitical skittishness? Disregard for sports fans?)
Safari has the same fragmentation problem, with multiple users stuck on old versions of iOS, and thus old emoji fonts. For example, some 3.75% of iOS users are still on iOS 15, with only 2022-era emoji. [2]
As a result, every website on the planet that cares about having a consistent emoji experience has to bundle their own font or spritesheet, wasting untold megabytes for something that’s been standardized like clockwork by the Unicode Consortium for 15 years.
My recommendation remains the same: browsers should bundle their own emoji font and ship it outside of OS updates. Firefox does this right; they just need to switch to an up-to-date font like this Twemoji fork. There is an issue on Chromium to add the same functionality. As for Safari, well… they’re not quite evergreen, and fragmentation is just a consequence of that. But shipping a font is not rocket science, so maybe WebKit or iOS could be convinced to ship it out-of-band.
In the meantime, web developers can use a COLR font or polyfill to get a reasonably consistent experience across browsers. It’s just sad to me that, with all the stunning advancements browsers have made in recent years, and with all the overwhelming popularity of emoji, the web still struggles at rendering them.
Footnotes
I’m using Codepen for this because WordPress automatically replaces native emoji with <img>s, since of course browsers can’t be trusted to render a font properly. Although ironically, they render the old flag (on certain browsers anyway): 🇲🇶
For posterity: using Wikimedia’s stats for August 12th through September 16th 2024: 1.2% mobile Safari 15 users / 32% mobile Safari users = 3.75%.
Et cetera, et cetera. Anyone who’s been doing web performance long enough probably has a story about how they wrote a benchmark that gave them some satisfying result, only to realize later that they flubbed some tiny detail that invalidated the whole thing. It can be crushing.
For years now, though, I’ve been using Tachometer for most browser-based benchmarks. It’s featured in this blog a few times, although I’ve never written specifically about it.
Tachometer doesn’t make benchmarking totally foolproof, but it does automate a lot of the trickiest bits. What I like best is that it:
Alternates between two scenarios in an interleaved fashion.
Launches a fresh browser profile between each iteration.
To be concrete, let’s say you have two scenarios you want to test: A and B. For Tachometer, these can simply be two web pages:
<!-- a.html --><script> scenarioA()</script>
<!-- b.html --><script> scenarioB()</script>
The only requirement is that you have something to measure, e.g. a performance measure:
function scenarioA() { // or B performance.mark('start') doStuff() performance.measure('total', 'start')}
Now let’s say you want to know whether scenarioA or scenarioB is faster. Tachometer will essentially do the following:
Load a.html.
Load b.html.
Repeat steps 1-2 until reaching statistical confidence that A and B are different enough (e.g. 1% different, 10% different, etc.).
This has several nice properties:
Environment-specific variance is removed. Since you’re running A and B at the same time, on the same machine, in an interleaved fashion, it’s very unlikely that some environmental quirk will cause A to be artificially different from B.
You don’t have to guess how many iterations are “enough” – the statistical test does that for you.
The browser is fresh between each iteration, so you’re not just measuring cached/JITed performance.
That said, there are several downsides to this approach:
The less different A and B are, the longer the tool will take to tell you that there’s no difference. In a CI environment, this is basically a nonstarter, because 99% of PRs don’t affect performance, and you don’t want to spend hours of CI time just to find out that updating the README didn’t regress anything.
As mentioned, you’re not measuring JITed time. Sometimes you want to measure that, though. In that case, you have to run your own iterations-within-iterations (e.g. a for-loop) to avoid measuring the pre-JITed time.
…Which you may end up doing anyway, because the tool tends to work best when your iterations take a large enough chunk of time. In my experience, a minimum of 50ms is preferable, although throttling can help you get there.
Tachometer also lacks any kind of visualization of performance changes over time, although there is a good GitHub action that can report the difference between a PR and your main branch. (Although again, you might not want to run it on every PR.)
The way I typically use Tachometer is to run one-off benchmarks, for instance when I’m doing some kind of cross-browser performance analysis. I often generate the config files rather than hand-authoring them, since they can be a bit repetitive.
Also, I only use Tachometer for browser or JavaScript tests – for anything else, I’d probably look into Hyperfine. (Haven’t used it, but heard good things about it.)
Tachometer has served me well for a long time, and I’m a big fan. The main benefit I’ve found is just the consistency of its results. I’ve been surprised how many times it’s consistently reported some odd regression (even in the ~1% range), which I can then track down with a git bisect to find the culprit. It’s also great for validating (or debunking) proposed perf optimizations.
Like any tool, Tachometer definitely has its flaws, and it’s still possible to fool yourself with it. But until I find a better tool, this is my go-to for low-level JavaScript microbenchmarks.
Note, though, that the browser expects connectedCallback to return undefined (or void for you TypeScript-heads). The same goes for disconnectedCallback, attributeChangedCallback, and friends. So the browser is just going to ignore whatever you return from those functions.
The best argument against using this pattern is that it kinda-sorta looks like the browser is going to treat your async function differently. Which it definitely won’t.
For example, let’s say you have some setup/teardown logic:
However, it will actually run the callbacks synchronously, with any async operations as a side effect. So in the above example, the awaits might resolve in a random order, causing a memory leak due to the dangling resize listener.
So as an alternative, you might want to avoid async connectedCallback just to make it crystal-clear that you’re using side effects:
connectedCallback() { (async () => { const response = await fetch('/data.json') const data = await response.json() this._data = data })()}
To me, though, this is ugly enough that I’ll just stick with async connectedCallback. And if I really need my async functions to execute sequentially, I might use the sequential Promise pattern or something.
I think filing bugs on browsers is one of the most useful things a web developer can do.
When faced with a cross-browser compatibility problem, a lot of us are conditioned to just search for some quick workaround, or to keep cycling through alternatives until something works. And this is definitely what I did earlier in my career. But I think it’s too short-sighted.
Browser dev teams are just like web dev teams – they have priorities and backlogs, and they sometimes let bugs slip through. Also, a well-written bug report with clear steps-to-repro can often lead to a quick resolution – especially if you manage to nerd-snipe some bored or curious engineer.
As such, I’ve filed a lot of bugs on browsers over the years. For whatever reason – stubbornness, frustration, some highfalutin sense of serving the web at large – I’ve made a habit of nagging browser vendors about whatever roadblock I’m hitting that day. And they often fix it!
So I thought it might be interesting to do an analysis of the bugs I’ve filed on the major browser engines – Chromium, Firefox, and WebKit – over my roughly 10-year web development career. I’ve excluded older and lesser-known browser engines that I never filed bugs on, and I’ve also excluded Trident/EdgeHTML, since the original “Microsoft Connect” bug tracker seems to be offline. (Also, I was literally paid to file bugs on EdgeHTML for a good 2 years, so it’s kind of unfair.)
Some notes about this data set, before people start drawing conclusions:
Chromium is a bit over-represented, because I tend to use Chromedriver-related tools (e.g. Puppeteer) a lot more than other browser automation tools.
WebKit is kind of odd in that a lot of these bugs turned out to be in proprietary Apple systems (Safari, iOS, etc.) rather than WebKit proper. (At least, this is what I assume the enigmatic rdar:// response means. [1])
I excluded one bug from Firefox that was actually on MDN (which uses the same bug tracker).
The data
So without further ado, here is the data set:
Browser
Filed
Open
Fixed
Invalid
Fixed%
Chromium
27
4
14
9
77.78%
Firefox
18
3
8
7
72.73%
WebKit
25
6
12
7
66.67%
Total
70
13
34
23
72.34%
Some things that jump out at me from the data set:
The “Fixed%” is pretty similar for all three browsers, although WebKit’s is a bit lower. When I look at the unfixed WebKit bugs, 2 are related to iOS rather than WebKit, one is in WebSQL (RIP), and the remaining 3 are honestly pretty minor. So I can’t really blame the WebKit team. (And one of those minor issues wound up in Interop 2024, so it may get fixed soon.)
For the 3 open Firefox issues, 2 of them are quite old and have terrible steps-to-repro (mea culpa), and the remaining one is a minor CSS issue related to shadow DOM.
For the 4 open Chromium issues, one of them is actually obsolete (I pinged the thread), 2 are quite minor, and the remaining one is partially fixed (it works when BFCache is enabled).
I was surprised that the total number of bugs filed on Firefox wasn’t even lower. My hazy memory was that I had barely filed any bugs on Firefox, and when I did, it usually turned out that they were following the spec but the other browsers weren’t. (I learned to really triple-check my work before filing bugs on them!)
6 of the bugs I filed on WebKit were for IndexedDB, which definitely matches my memory of hounding them with bug reports for IDB. (In comparison, I filed 3 IDB bugs on Chromium and 0 on Firefox.)
As expected, 5 issues I filed on Chromium were due to ChromeDriver, DevTools, etc.
If you’d like to peruse the raw data, it can be found below:
position:sticky inside of position:fixed does’t async-scroll in Firefox for Android (and asserts in ActiveScrolledRoot::PickDescendant() in debug build)
Safari sends empty “Access-Control-Request-Headers” in preflight request
2017-03-22
Conclusion
I think cross-browser compatibility has improved a lot over the past few years. We have projects like Interop and Web Platform Tests, which make it a lot more streamlined for browser teams to figure out what’s broken and what they should prioritize.
So if you haven’t yet, there’s no better time to get started filing bugs on browsers! I’d recommend first searching for your issue in the right bug tracker (Chromium, Firefox, WebKit), then creating a minimal repro (CodePen, JSBin, plain HTML, etc.), and finally just including as much detail as you can (browser version, OS version, screenshots, etc.). I’d also recommend reading “How to file a good browser bug”.
Happy bug hunting!
Footnotes
1.Somefolks have pointed out to me that rdar:// links can mean just about anything. I always assumed it meant that the bug got re-routed to some internal team, but I guess not.
This setupLogic() can be just about anything – subscribing to a store, setting up event listeners, etc. The teardownLogic() is designed to undo those things – unsubscribe from a store, remove event listeners, etc.
The problem is that constructor is called once, when the component is created. Whereas disconnectedCallback can be called multiple times, whenever the element is removed from the DOM.
The correct solution is to use connectedCallback instead of constructor:
Unfortunately it’s really easy to mess this up and to not realize that you’ve done anything wrong. A lot of the time, a component is created once, inserted once, and removed once. So the difference between constructor and connectedCallback never reveals itself.
However, as soon as your consumer starts doing something complicated with your component, the problem rears its ugly head:
This can be really subtle. A JavaScript framework’s diffing algorithm might remove an element from a list and insert it into a different position in the list. If so: congratulations! You’ve been disconnected and reconnected.
Or you might call appendChild() on an element that’s already appended somewhere else. Technically, the DOM considers this a disconnect and a reconnect:
// Calls connectedCallbackcontainerOne.appendChild(component)// Calls disconnectedCallback and connectedCallbackcontainerTwo.appendChild(component)
The bottom line is: if you’re doing something in disconnectedCallback, you should do the mirror logic in connectedCallback. If not, then it’s a subtle bug just lying in wait for the right moment to strike.
Web components are kind of having a moment right now. And as part of that, shadow DOM is having a bit of a moment too. Or it would, except that much of the conversation seems to be about why you shouldn’t use shadow DOM.
For example, “HTML web components” are based on the idea that you should use most of the goodness of web components (custom elements, lifecycle hooks, etc.), while dropping shadow DOM like a bad habit. (Another name for this is “light DOM components.”)
This is a perfectly fine pattern for certain cases. But I also think some folks are confused about the tradeoffs with shadow DOM, because they don’t understand what shadow DOM is supposed to accomplish in the first place. In this post, I’d like to clear up some of the misconceptions by explaining what shadow DOM is supposed to do, while also weighing its success in actually achieving it.
What the heck is shadow DOM for
The main goal of shadow DOM is encapsulation. Encapsulation is a tricky concept to explain, because the benefits are not immediately obvious.
Let’s say you have a third-party component that you’ve decided to include on your website or webapp. Maybe you found it on npm, and it solved some use case very nicely. Let’s say it’s something simple, like a dropdown component.
You know what, though? You really don’t like that caret character – you’d rather have a 👇 emoji. And you’d really prefer rounded corners. And the theme color should be red instead of blue. So you hack together some CSS:
Except that 6 months later, the component has an update. And it’s to fix a security vulnerability! Your boss is pressuring you to update the component as fast as possible, since otherwise the website won’t pass a security audit anymore. So you go to update, and…
Everything’s broken.
It turns out that the component changed their internal class name from dropdown to picklist. And they don’t use CSS content for the caret anymore. And they added a wrapper <div>, so the border-radius needs to be applied to something else now. Suddenly you’re in for a world of hurt, just to get the component back to the way it used to look.
Global control is great until it isn’t
CSS gives you an amazing superpower, which is that you can target any element on the page as long as you can think of the right selector. It’s incredibly easy to do this in DevTools today – a lot of people are trained to right-click, “Inspect Element,” and rummage around for any class or attribute to start targeting the element. And this works great in the short term, but it affects the long-term maintainability of the code, especially for components you don’t own.
This isn’t just a problem with CSS – JavaScript has this same flaw due to the DOM. Using document.querySelector (or equivalent APIs), you can traverse anywhere you want in the DOM, find an element, and apply some custom behavior to it – e.g. adding an event listener or changing its internal structure. I could tell the same story above using JavaScript rather than CSS.
This openness can cause headaches for component authors as well as component consumers. In a system where the onus is on the component author to ship new versions (e.g. a monorepo, a platform, or even just a large codebase), component authors can effectively get frozen in time, unable to ship any internal refactors for fear of breaking their downstream consumers.
Shadow DOM attempts to solve these problems by providing encapsulation. If the third-party dropdown component were using shadow DOM, then you wouldn’t be able to target arbitrary content inside of it (except with elaborate workarounds that I don’t want to get into).
Of course, by closing off access to global styling and DOM traversal, shadow DOM also greatly limits a component’s customizability. Consumers can’t just decide they want a background to be red, or a border to be rounded – the component author has to provide an explicit styling API, using tools like CSS custom properties or parts. E.g.:
By exposing an explicit styling API, the risk of breakage across component upgrades is heavily reduced. The component author is effectively declaring an API surface that they intend to support, which limits what they need to keep stable over time. (This API can still break, as with a major version bump, but that’s another story.)
Tradeoffs
When people complain about shadow DOM, they seem to mostly be complaining about style encapsulation. They want to reach in and add a rounded corner on some component, and roll the dice that the component doesn’t change in the future. Depending on what kind of website you’re building, this can be a perfectly acceptable tradeoff. For example:
A portfolio site
A news article with interactive charts
A marketing site for a Super Bowl campaign
A landing page that will be rewritten in 2 years anyway
In all of these cases, long-term maintenance is not really a big concern. The page either has a limited shelf life, or it’s just not important to keep its dependencies up to date. So if the dropdown component breaks in a year or two, nobody cares.
Of course, there is also the opposite world where long-term maintenance matters a lot:
An interactive productivity app
A design system
A platform with its own app store for UI components
An online multiplayer game
I could go on, but the point is: the second group cares a lot more about long-term maintainability than the first group. If you’ve spent your entire career working on the first group, then you may indeed find shadow DOM to be baffling. You can’t possibly understand why you should be prevented from globally styling whatever you want.
Conversely, if you’ve spent your entire career in the second group, then you may be equally baffled by people who want global access to everything. (“Are they trying to shoot themselves in the foot?”) This is why I think people are often talking past each other about this stuff.
But does it work
So now that we’ve established the problem shadow DOM is trying to solve, there’s the inevitable question: does it actually solve it?
This is an important question, because I think it’s the source of the other major tension with shadow DOM. Even people who understand the problem are not in agreement that shadow DOM actually solves it.
If you want to get a good sense of people’s frustrations with shadow DOM, there are two massive GitHub threads you can check out:
There are a lot of potential solutions being tossed around in those threads (including by me), but I’m not really convinced that any one of them is the silver bullet that is going to solve people’s frustrations with shadow DOM. And the reason is that the core problem here is a coordination problem, not a technical problem.
For example, take “open-stylable shadow roots.” The idea is that a shadow root can inherit the styles from its parent context (exactly like light DOM). But then of course, we get into the coordination problem:
Will every web component on npm need to enable open-stylable shadow roots?
Or will page authors need a global mechanism to force every component into this mode?
What if a component author doesn’t want to be opted-in? What if they prefer the lower maintenance costs of a small API surface?
There’s no right answer here. And that’s because there’s an inherent conflict between the needs of the component author and the page author. The component author wants minimal maintenance costs and to avoid breaking their downstream consumers with every update, and the page author wants to style every component on the page to pixel-perfect precision, while also never being broken.
Stated that way, it sounds like an unsolvable problem. In practice, I think the problem gets solved by favoring one group over the other, which can make some sense depending on the context (largely based on whether your website is in group one or group two above).
A potential solution?
If there is one solution I find promising, it’s articulated by my colleague Caridy Patiño:
Build building blocks that encapsulate logic and UI elements that are “fully” customizable by using existing mechanisms (CSS properties, parts, slots, etc.). Everything must be customizable from outside the shadow.
If a building block is using another building block in its shadow, it must do it as part of the default content of a well-defined slot.
Essentially, what Caridy is saying is that instead of providing a dropdown component to be used like this:
In other words, the component should expose its “guts” externally (using <slot>s in this example) so that everything is stylable. This way, anything the consumer may want to customize is fully exposed to light DOM.
This is not a totally new idea. In fact, outside of the world of web components, plenty of component systems have run into similar problems and arrived at similar solutions. For example, so-called “headless” component systems (such as Radix UI, Headless UI, and Tanstack) have embraced this kind of design.
For comparison, here is an (abridged) example of the dropdown menu from the Radix docs:
This is pretty similar to the web component sketch above – the “guts” of the dropdown are on display for all to see, and anything in the UI is fully customizable.
To me, though, these solutions are clearly taking the burden of complexity and shifting it from the component author to the component consumer. Rather than starting with the simplest case and providing a bare-bones default, the component author is instead starting with the complex case, forcing the consumer to (likely) copy-paste a lot of boilerplate into their codebase before they can start tweaking.
Now, maybe this is the right solution! And maybe the long-term maintenance costs are worth it! But I think the tradeoff should still be acknowledged.
As I understand it, though, these kinds of “headless” solutions are still a bit novel, so we haven’t gotten a lot of real-world data to prove the long-term benefits. I have no doubt, though, that a lot of component authors see this approach as the necessary remedy to the problem of runaway configurability – i.e. component consumers ask for every little thing to be configurable, all those configuration options get shoved into one top-level API, and the overall experience starts to look like recursive Swiss Army Knives. (Tanner Linsley gives a great talk about this, reflecting on 5 years of building React Table.)
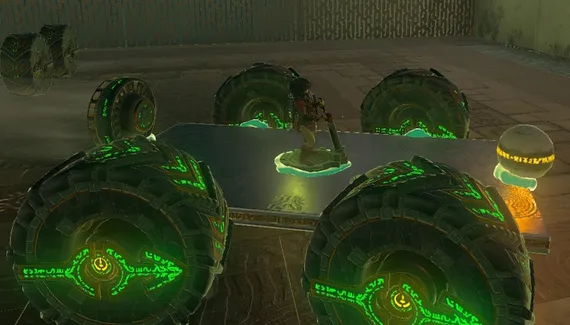
Personally, I’m intrigued by this technique, but I’m not fully convinced that exposing the “guts” of a component really reduces the overall maintenance cost. It’s kind of like, instead of selling a car with a predefined set of customizations (color, window tint, automatic vs manual, etc.), you’re selling a loose set of parts that the customer can mix-and-match into whatever kind of vehicle they want. Rather than a car off the assembly line, it reminds me of a jerry-rigged contraption from Minecraft or Zelda.
In Tears of the Kingdom, you can glue together just about anything, and it will kind of work.
I haven’t worked on such a component system, but I’d worry that you’d get bugs along the lines of, “Well, when I put the slider on the left it works, but when I put it on the right, the scroll position gets messed up.” There is so much potential customizability, that I’m not sure how you could even write tests to cover all the possible configurations. Although maybe that’s the point – there’s effectively no UI, so if the UI is messed up, then it’s the component consumer’s job to fix it.
Conclusion
I don’t have all the answers. At this point, I just want to make sure we’re asking the right questions.
To me, any proposed solution to the current problems with shadow DOM should be prefaced with:
What kind of website or webapp is the intended context?
Who stands to benefit from this change – the component author or page author?
Who needs to shift their behavior to make the whole thing work?
I’m also not convinced that any of this stuff is ripe enough for the standards discussion to begin. There are so many options that can be explored in userland right now (e.g. the “expose the guts” proposal, or a polyfill for open-stylable shadow roots), that it’s premature to start asking standards bodies to standardize anything.
I also think that the inherent conflict between the needs of component authors and component consumers has not really been acknowledged enough in the standards discussions. And the W3C’s priority of constituencies doesn’t help us much here:
User needs come before the needs of web page authors, which come before the needs of user agent implementors, which come before the needs of specification writers, which come before theoretical purity.
In the above formulation, there’s no distinction between component authors and component consumers – they are both just “web page authors.” I suppose conceptually, if we imagine the whole web platform as a “stack,” then we would place the needs of component consumers over component authors. But even that gets muddy sometimes, since component authors and component consumers can work on the same team or even be the same person.
Overall, what I would love to see is a thorough synopsis of the various groups involved in the web component ecosystem, how the existing solutions have worked in practice, what’s been tried and what hasn’t, and what needs to change to move forward. (This blog post is not it; this is just my feeble groping for a vocabulary to even start talking about the problem.)
In my mind, we are still chasing the holy grail of true component reusability. I often think back to this eloquent talk by Jan Miksovsky, where he explains how much has been standardized in the world of building construction (e.g. the size of windows and door frames), whereas us web developers are still stuck rebuilding the same thing over and over again. I don’t know if we’ll ever reach true component reusability (or if building construction is really as rosy as he describes – I can barely wield a hammer), but I do know that I still find the vision inspiring.
In my last post, we went on a guided tour of building a JavaScript framework from scratch. This wasn’t just an intellectual exercise, though – I actually had a reason for wanting to build my own framework.
For a few years now, I’ve been maintaining emoji-picker-element, which is designed as a fast, simple, and lightweight web component that you can drop onto any page that needs an emoji picker.
Most of the maintenance work has been about simply keeping pace with the regular updates to the Unicode standard to add new emoji versions. (Shout-out to Emojibase for providing a stable foundation to build on!) But I’ve also worked to keep up with the latest Svelte versions, since emoji-picker-element is based on Svelte.
The project was originally written in Svelte v3, and the v4 upgrade was nothing special. The v5 upgrade was only slightly more involved, which is astounding given that the framework was essentially rewritten from scratch. (How Rich and the team managed to pull this off boggles my mind.)
I should mention at this point that I think Svelte is a great framework, and a pleasure to work with. It’s probably my favorite JavaScript framework (other than the one I work on!). That said, a few things bugged me about the Svelte v5 upgrade:
It grew emoji-picker-element‘s bundle size by 7.1kB minified (it was originally a bit more, but Dominic Gannaway graciously made improvements to the tree-shaking).
It dropped support for older browsers due to syntax changes, in particular Safari 12 (which is 0.25-0.5% of browsers depending on who you ask).
Now, neither of these things really ought to be a dealbreaker. 7.1kB is not a huge amount for the average webapp, and an emoji picker should probably be lazy-loaded most of the time anyway. Also, Safari 12 might not be worth worrying about (and if it is, it won’t be in a couple years).
I also don’t think there’s anything wrong with building a standalone web component on top of a JavaScript framework – I’ve said so in the past. There are lots of fiddly bits that are hard to get right when you’re building a web component, and 99 times out of 100, you’re much better off using something like Svelte, or Lit, or Preact, or petite-vue, than to try to wing it yourself in Vanilla JS and building a half-baked framework in the process.
That said… I enjoy building a half-baked framework. And I have a bit of a competitive streak that makes me want to trim the bundle size as much as possible. So I decided to take this as an opportunity to rebuild emoji-picker-element on top of my own custom framework.
The end result is more or less what you saw in the previous post: a bit of reactivity, a dash of tagged template literals, and poof! A new framework is born.
This new framework is honestly only slightly more complex than what I sketched out in that post – I ended up only needing 85 lines of code for the reactivity engine and 233 for the templating system (as measured by cloc).
Of course, to get this minuscule size, I had to take some shortcuts. If this were an actual framework I was releasing to the world, I would need to handle a long tail of edge cases, perf hazards, and gnarly tradeoffs. But since this framework only needs to support one component, I can afford to cut some corners.
So does this tiny framework actually cut the mustard? Here are the results:
The bundle size is 6.1kB smaller than the current implementation (and ~13.2kB smaller than the Svelte 5 version).
Safari 12 is still supported (without needing code transforms).
So was it worth it? I dunno. Maybe I will get a flood of bug reports after I ship this, and I will come crawling back to Svelte. Or maybe I will find that it’s too hard to add new features without the flexibility of a full framework. But I doubt it. I enjoyed building my own framework, and so I think I’ll keep it around just for the fun of it.
Side projects for me are always about three things: 1) learning, 2) sharing something with the world, and 3) having fun while doing so. emoji-picker-element ticks all three boxes for me, so I’m going to stick with the current design for the time being.
In my day job, I work on a JavaScript framework (LWC). And although I’ve been working on it for almost three years, I still feel like a dilettante. When I read about what’s going on in the larger framework world, I often feel overwhelmed by all the things I don’t know.
One of the best ways to learn how something works, though, is to build it yourself. And plus, we gotta keep those “days since last JavaScript framework” memes going. So let’s write our own modern JavaScript framework!
What is a “modern JavaScript framework”?
React is a great framework, and I’m not here to dunk on it. But for the purposes of this post, “modern JavaScript framework” means “a framework from the post-React era” – i.e. Lit, Solid, Svelte, Vue, etc.
React has dominated the frontend landscape for so long that every newer framework has grown up in its shadow. These frameworks were all heavily inspired by React, but they’ve evolved away from it in surprisingly similar ways. And although React itself has continued innovating, I find that the post-React frameworks are more similar to each other than to React nowadays.
To keep things simple, I’m also going to avoid talking about server-first frameworks like Astro, Marko, and Qwik. These frameworks are excellent in their own way, but they come from a slightly different intellectual tradition compared to the client-focused frameworks. So for this post, let’s only talk about client-side rendering.
What sets modern frameworks apart?
From my perspective, the post-React frameworks have all converged on the same foundational ideas:
Using modern web APIs like <template> and Proxy, which make all of the above easier.
Now to be clear, these frameworks differ a lot at the micro level, and in how they handle things like web components, compilation, and user-facing APIs. Not all frameworks even use Proxys. But broadly speaking, most framework authors seem to agree on the above ideas, or they’re moving in that direction.
So for our own framework, let’s try to do the bare minimum to implement these ideas, starting with reactivity.
Reactivity
It’s often said that “React is not reactive”. What this means is that React has a more pull-based rather than a push-based model. To grossly oversimplify things: in the worst case, React assumes that your entire virtual DOM tree needs to be rebuilt from scratch, and the only way to prevent these updates is to implement React.memo (or in the old days, shouldComponentUpdate).
Using a virtual DOM mitigates some of the cost of the “blow everything away and start from scratch” strategy, but it doesn’t fully solve it. And asking developers to write the correct memo code is a losing battle. (See React Forget for an ongoing attempt to solve this.)
Instead, modern frameworks use a push-based reactive model. In this model, individual parts of the component tree subscribe to state updates and only update the DOM when the relevant state changes. This prioritizes a “performant by default” design in exchange for some upfront bookkeeping cost (especially in terms of memory) to keep track of which parts of the state are tied to which parts of the UI.
Note that this technique is not necessarily incompatible with the virtual DOM approach: tools like Preact Signals and Million show that you can have a hybrid system. This is useful if your goal is to keep your existing virtual DOM framework (e.g. React) but to selectively apply the push-based model for more performance-sensitive scenarios.
For this post, I’m not going to rehash the details of signals themselves, or subtler topics like fine-grained reactivity, but I am going to assume that we’ll use a reactive system.
Cloning DOM trees
For a long time, the collective wisdom in JavaScript frameworks was that the fastest way to render the DOM is to create and mount each DOM node individually. In other words, you use APIs like createElement, setAttribute, and textContent to build the DOM piece-by-piece:
const div = document.createElement('div')div.setAttribute('class', 'blue')div.textContent = 'Blue!'
One alternative is to just shove a big ol’ HTML string into innerHTML and let the browser parse it for you:
This naïve approach has a big downside: if there is any dynamic content in your HTML (for instance, red instead of blue), then you would need to parse HTML strings over and over again. Plus, you are blowing away the DOM with every update, which would reset state such as the value of <input>s.
At some point, though, folks figured out that parsing the HTML once and then calling cloneNode(true) on the whole thing is pretty danged fast:
const template = document.createElement('template')template.innerHTML = ` <div class="blue">Blue!</div>`template.content.cloneNode(true) // this is fast!
Here I’m using a <template> tag, which has the advantage of creating “inert” DOM. In other words, things like <img> or <video autoplay> don’t automatically start downloading anything.
How fast is this compared to manual DOM APIs? To demonstrate, here’s a small benchmark. Tachometer reports that the cloning technique is about 50% faster in Chrome, 15% faster in Firefox, and 10% faster in Safari. (This will vary based on DOM size and number of iterations, but you get the gist.)
What’s interesting is that <template> is a new-ish browser API, not available in IE11, and originally designed for web components. Somewhat ironically, this technique is now used in a variety of JavaScript frameworks, regardless of whether they use web components or not.
There is one major challenge with this technique, which is how to efficiently update dynamic content without blowing away DOM state. We’ll cover this later when we build our toy framework.
Modern JavaScript APIs
We’ve already encountered one new API that helps a lot, which is <template>. Another one that’s steadily gaining traction is Proxy, which can make building a reactivity system much simpler.
When we build our toy example, we’ll also use tagged template literals to create an API like this:
const dom = html` <div>Hello ${ name }!</div>`
Not all frameworks use this tool, but notable ones include Lit, HyperHTML, and ArrowJS. Tagged template literals can make it much simpler to build ergonomic HTML templating APIs without needing a compiler.
Step 1: building reactivity
Reactivity is the foundation upon which we’ll build the rest of the framework. Reactivity will define how state is managed, and how the DOM updates when state changes.
Let’s start with some “dream code” to illustrate what we want:
Basically, we want a “magic object” called state, with two props: a and b. And whenever those props change, we want to set sum to be the sum of the two.
Assuming we don’t know the props in advance (or have a compiler to determine them), a plain object will not suffice for this. So let’s use a Proxy, which can react whenever a new value is set:
const state = new Proxy({}, { get(obj, prop) { onGet(prop) return obj[prop] }, set(obj, prop, value) { obj[prop] = value onSet(prop, value) return true }})
Right now, our Proxy doesn’t do anything interesting, except give us some onGet and onSet hooks. So let’s make it flush updates after a microtask:
Why flush updates? Mostly because we don’t want to run too many computations. If we update whenever both a and b change, then we’ll uselessly compute the sum twice. By coalescing the flush into a single microtask, we can be much more efficient.
Next, let’s make flush update the sum:
function flush() { state.sum = state.a + state.b}
This is great, but it’s not yet our “dream code.” We’ll need to implement createEffect so that the sum is computed only when a and b change (and not when something else changes!).
To do this, let’s use an object to keep track of which effects need to be run for which props:
const propsToEffects = {}
Next comes the crucial part! We need to make sure that our effects can subscribe to the right props. To do so, we’ll run the effect, note any get calls it makes, and create a mapping between the prop and the effect.
When this function runs, it calls two getters: state.a and state.b. These getters should trigger the reactive system to notice that the function relies on the two props.
To make this happen, we’ll start with a simple global to keep track of what the “current” effect is:
let currentEffect
Then, the createEffect function will set this global before calling the function:
function createEffect(effect) { currentEffect = effect effect() currentEffect = undefined}
The important thing here is that the effect is immediately invoked, with the global currentEffect being set in advance. This is how we can track whatever getters it might be calling.
Now, we can implement the onGet in our Proxy, which will set up the mapping between the global currentEffect and the property:
At this point, we have all the pieces in place for flush to call all the dirtyEffects:
function flush() { while (dirtyEffects.length) { dirtyEffects.shift()() }}
Putting it all together, we now have a fully functional reactivity system! You can play around with it yourself and try setting state.a and state.b in the DevTools console – the state.sum will update whenever either one changes.
Now, there are plenty of advanced cases that we’re not covering here:
Using try/catch in case an effect throws an error
Avoiding running the same effect twice
Preventing infinite cycles
Subscribing effects to new props on subsequent runs (e.g. if certain getters are only called in an if block)
However, this is more than enough for our toy example. Let’s move on to DOM rendering.
Step 2: DOM rendering
We now have a functional reactivity system, but it’s essentially “headless.” It can track changes and compute effects, but that’s about it.
At some point, though, our JavaScript framework needs to actually render some DOM to the screen. (That’s kind of the whole point.)
For this section, let’s forget about reactivity for a moment and imagine we’re just trying to build a function that can 1) build a DOM tree, and 2) update it efficiently.
Once again, let’s start off with some dream code:
function render(state) { return html` <div class="${state.color}">${state.text}</div> `}
As I mentioned, I’m using tagged template literals, ala Lit, because I found them to be a nice way to write HTML templates without needing a compiler. (We’ll see in a moment why we might actually want a compiler instead.)
We’re re-using our state object from before, this time with a color and text property. Maybe the state is something like:
state.color = 'blue'state.text = 'Blue!'
When we pass this state into render, it should return the DOM tree with the state applied:
<div class="blue">Blue!</div>
Before we go any further, though, we need a quick primer on tagged template literals. Our html tag is just a function that receives two arguments: the tokens (array of static HTML strings) and expressions (the evaluated dynamic expressions):
function html(tokens, ...expressions) {}
In this case, the tokens are (whitespace removed):
[ "<div class=\"", "\">", "</div>"]
And the expressions are:
[ "blue", "Blue!"]
The tokens array will always be exactly 1 longer than the expressions array, so we can trivially zip them up together:
This template contains our inert DOM (technically a DocumentFragment), which we can clone at will:
const cloned = template.content.cloneNode(true)
Of course, parsing the full HTML whenever the html function is called would not be great for performance. Luckily, tagged template literals have a built-in feature that will help out a lot here.
For every unique usage of a tagged template literal, the tokens array is always the same whenever the function is called – in fact, it’s the exact same object!
For example, consider this case:
function sayHello(name) { return html`<div>Hello ${name}</div>`}
Whenever sayHello is called, the tokens array will always be identical:
[ "<div>Hello ", "</div>"]
The only time tokens will be different is for completely different locations of the tagged template:
html`<div></div>`html`<span></span>` // Different from above
We can use this to our advantage by using a WeakMap to keep a mapping of the tokens array to the resulting template:
const tokensToTemplate = new WeakMap()function html(tokens, ...expressions) { let template = tokensToTemplate.get(tokens) if (!template) { // ... template = parseTemplate(htmlString) tokensToTemplate.set(tokens, template) } return template}
This is kind of a mind-blowing concept, but the uniqueness of the tokens array essentially means that we can ensure that each call to html`...` only parses the HTML once.
Next, we just need a way to update the cloned DOM node with the expressions array (which is likely to be different every time, unlike tokens).
To keep things simple, let’s just replace the expressions array with a placeholder for each index:
And now whenever the html function is called, we can clone the template and update the placeholders:
const element = cloned.firstElementChildfor (const { name, value } of element.attributes) { element.setAttribute(name, replaceStubs(value))}element.textContent = replaceStubs(element.textContent)
Now, this is still not terribly efficient – notably, we are updating textContent and attributes that don’t necessarily need to be updated. But for our toy framework, this is good enough.
We can test it out by rendering with different state:
Since we already have a createEffect from the rendering system above, we can now combine the two to update the DOM based on the state:
const container = document.getElementById('container')createEffect(() => { const dom = render(state) if (container.firstElementChild) { container.firstElementChild.replaceWith(dom) } else { container.appendChild(dom) }})
This actually works! We can combine this with the “sum” example from the reactivity section by merely creating another effect to set the text:
createEffect(() => { state.text = `Sum is: ${state.sum}`})
This renders “Sum is 3”:
You can play around with this toy example. If you set state.a = 5, then the text will automatically update to say “Sum is 7.”
Next steps
There are lots of improvements we could make to this system, especially the DOM rendering bit.
Most notably, we are missing a way to update content for elements inside a deep DOM tree, e.g.:
<div class="${color}"> <span>${text}</span></div>
For this, we would need a way to uniquely identify every element inside of the template. There are lots of ways to do this:
Lit, when parsing HTML, uses a system of regexes and character matching to determine whether a placeholder is within an attribute or text content, plus the index of the target element (in depth-first TreeWalker order).
Frameworks like Svelte and Solid have the luxury of parsing the entire HTML template during compilation, which provides the same information. They also generate code that calls firstChild and nextSibling to traverse the DOM to find the element to update.
Whether we decided to do Lit-style client-side parsing or Svelte/Solid-style compile-time parsing, what we want is some kind of mapping like this:
[ { elementIndex: 0, // <div> above attributeName: 'class', stubIndex: 0 // index in expressions array }, { elementIndex: 1 // <span> above textContent: true, stubIndex: 1 // index in expressions array }]
These bindings would tell us exactly which elements need to be updated, which attribute (or textContent) needs to be set, and where to find the expression to replace the stub.
The next step would be to avoid cloning the template every time, and to just directly update the DOM based on the expressions. In other words, we not only want to parse once – we want to only clone and set up the bindings once. This would reduce each subsequent update to the bare minimum of setAttribute and textContent calls.
Another interesting pattern to implement would be iterations (or repeaters), which come with their own set of challenges, like reconciling lists between updates and handling “keys” for efficient replacement.
I’m tired, though, and this blog post has gone on long enough. So I leave the rest as an exercise to the reader!
Conclusion
So there you have it. In the span of one (lengthy) blog post, we’ve implemented our very own JavaScript framework. Feel free to use this as the foundation for your brand-new JavaScript framework, to release to the world and enrage the Hacker News crowd.
Personally I found this project very educational, which is partly why I did it in the first place. I was also looking to replace the current framework for my emoji picker component with a smaller, more custom-built solution. In the process, I managed to write a tiny framework that passes all the existing tests and is ~6kB smaller than the current implementation, which I’m pretty proud of.
In the future, I think it would be neat if browser APIs were full-featured enough to make it even easier to build a custom framework. For example, the DOM Part API proposal would take out a lot of the drudgery of the DOM parsing-and-replacement system we built above, while also opening the door to potential browser performance optimizations. I could also imagine (with some wild gesticulation) that an extension to Proxy could make it easier to build a full reactivity system without worrying about details like flushing, batching, or cycle detection.
If all those things were in place, then you could imagine effectively having a “Lit in the browser,” or at least a way to quickly build your own “Lit in the browser.” In the meantime, I hope that this small exercise helped to illustrate some of the things framework authors think about, and some of the machinery under the hood of your favorite JavaScript framework.
1. Now that we’ve built the framework, you can see why the content passed to innerHTML can be considered trusted. All HTML tokens either come from tagged template literals (in which case they’re fully static and authored by the developer) or are placeholders (which are also written by the developer). User content is only set using setAttribute or textContent, which means that no HTML sanitization is required to avoid XSS attacks. Although you should probably just use CSP anyway!