Archive for the ‘software engineering’ Category

Why don’t more developers “use the platform”?

For years, advocates for web standards, performance, and accessibility have implored web developers to “use the platform”. I’ve often been one of those advocates.

The argument is simple: why build something yourself, in JavaScript, when the browser can do it for you? Whatever you build, it’s likely to have poorer performance and worse usability than something the browser could just give you out-of-the-box.

I think it’s worth taking the other side, though, if for no other reason than to understand where the “platform-skeptic” developers are coming from. If “use the platform” is so obvious, then why do so many people seem to need convincing?

The most obvious reason is historical: for the longest time, browsers were playing catch-up with the ecosystem on top of them. Libraries like jQuery filled crucial gaps while browsers implemented equivalent APIs – and even then, you might have to wait for laggards like IE6 to age out before you could actually use them. Today, most browsers are evergreen (Safari is debatable, although ~7 times per year ain’t bad), but up until the 2020s or so, web developers had to deal with a decidedly lumpy web. In that environment, rolling your own is a sensible choice.

Another reason is familiarity: when you’re used to looking for React components on npm, that’s what you tend to reach for, regardless of the problem at hand. If you search for “sticky positioning” on npm, there’s no package that says “just use CSS position: sticky, you dolt.”

And often, even with a robust standard, libraries on npm would fill a useful gap between framework ergonomics and the platform underneath it. I always found it intriguing that many React developers preferred to stick to JSX and React idioms – raw DOM APIs felt “icky” – but were perfectly happy to use lower-level libraries where raw DOM manipulations are common. For example, a virtual list library might happily use raw DOM APIs for pure performance, while exposing higher-level primitives that a novice React developer could better grasp. In a sense, the ecosystem of React components led to a natural division of labor where those with more expertise packaged up unfamiliar platform APIs in a more familiar form factor.

Some of this effect was also driven by documentation. Many npm packages have lovingly detailed READMEs or websites with examples, tutorials, and screenshots. Whereas until MDN became cemented as the go-to place for web documentation (with web.dev as Google’s more future-facing arm), documentation for the web platform was scattered across blogs, StackOverflow, and sites like CSS Tricks. And many of these sites would just tell you to use a well-known library like jQuery or GreenSock!
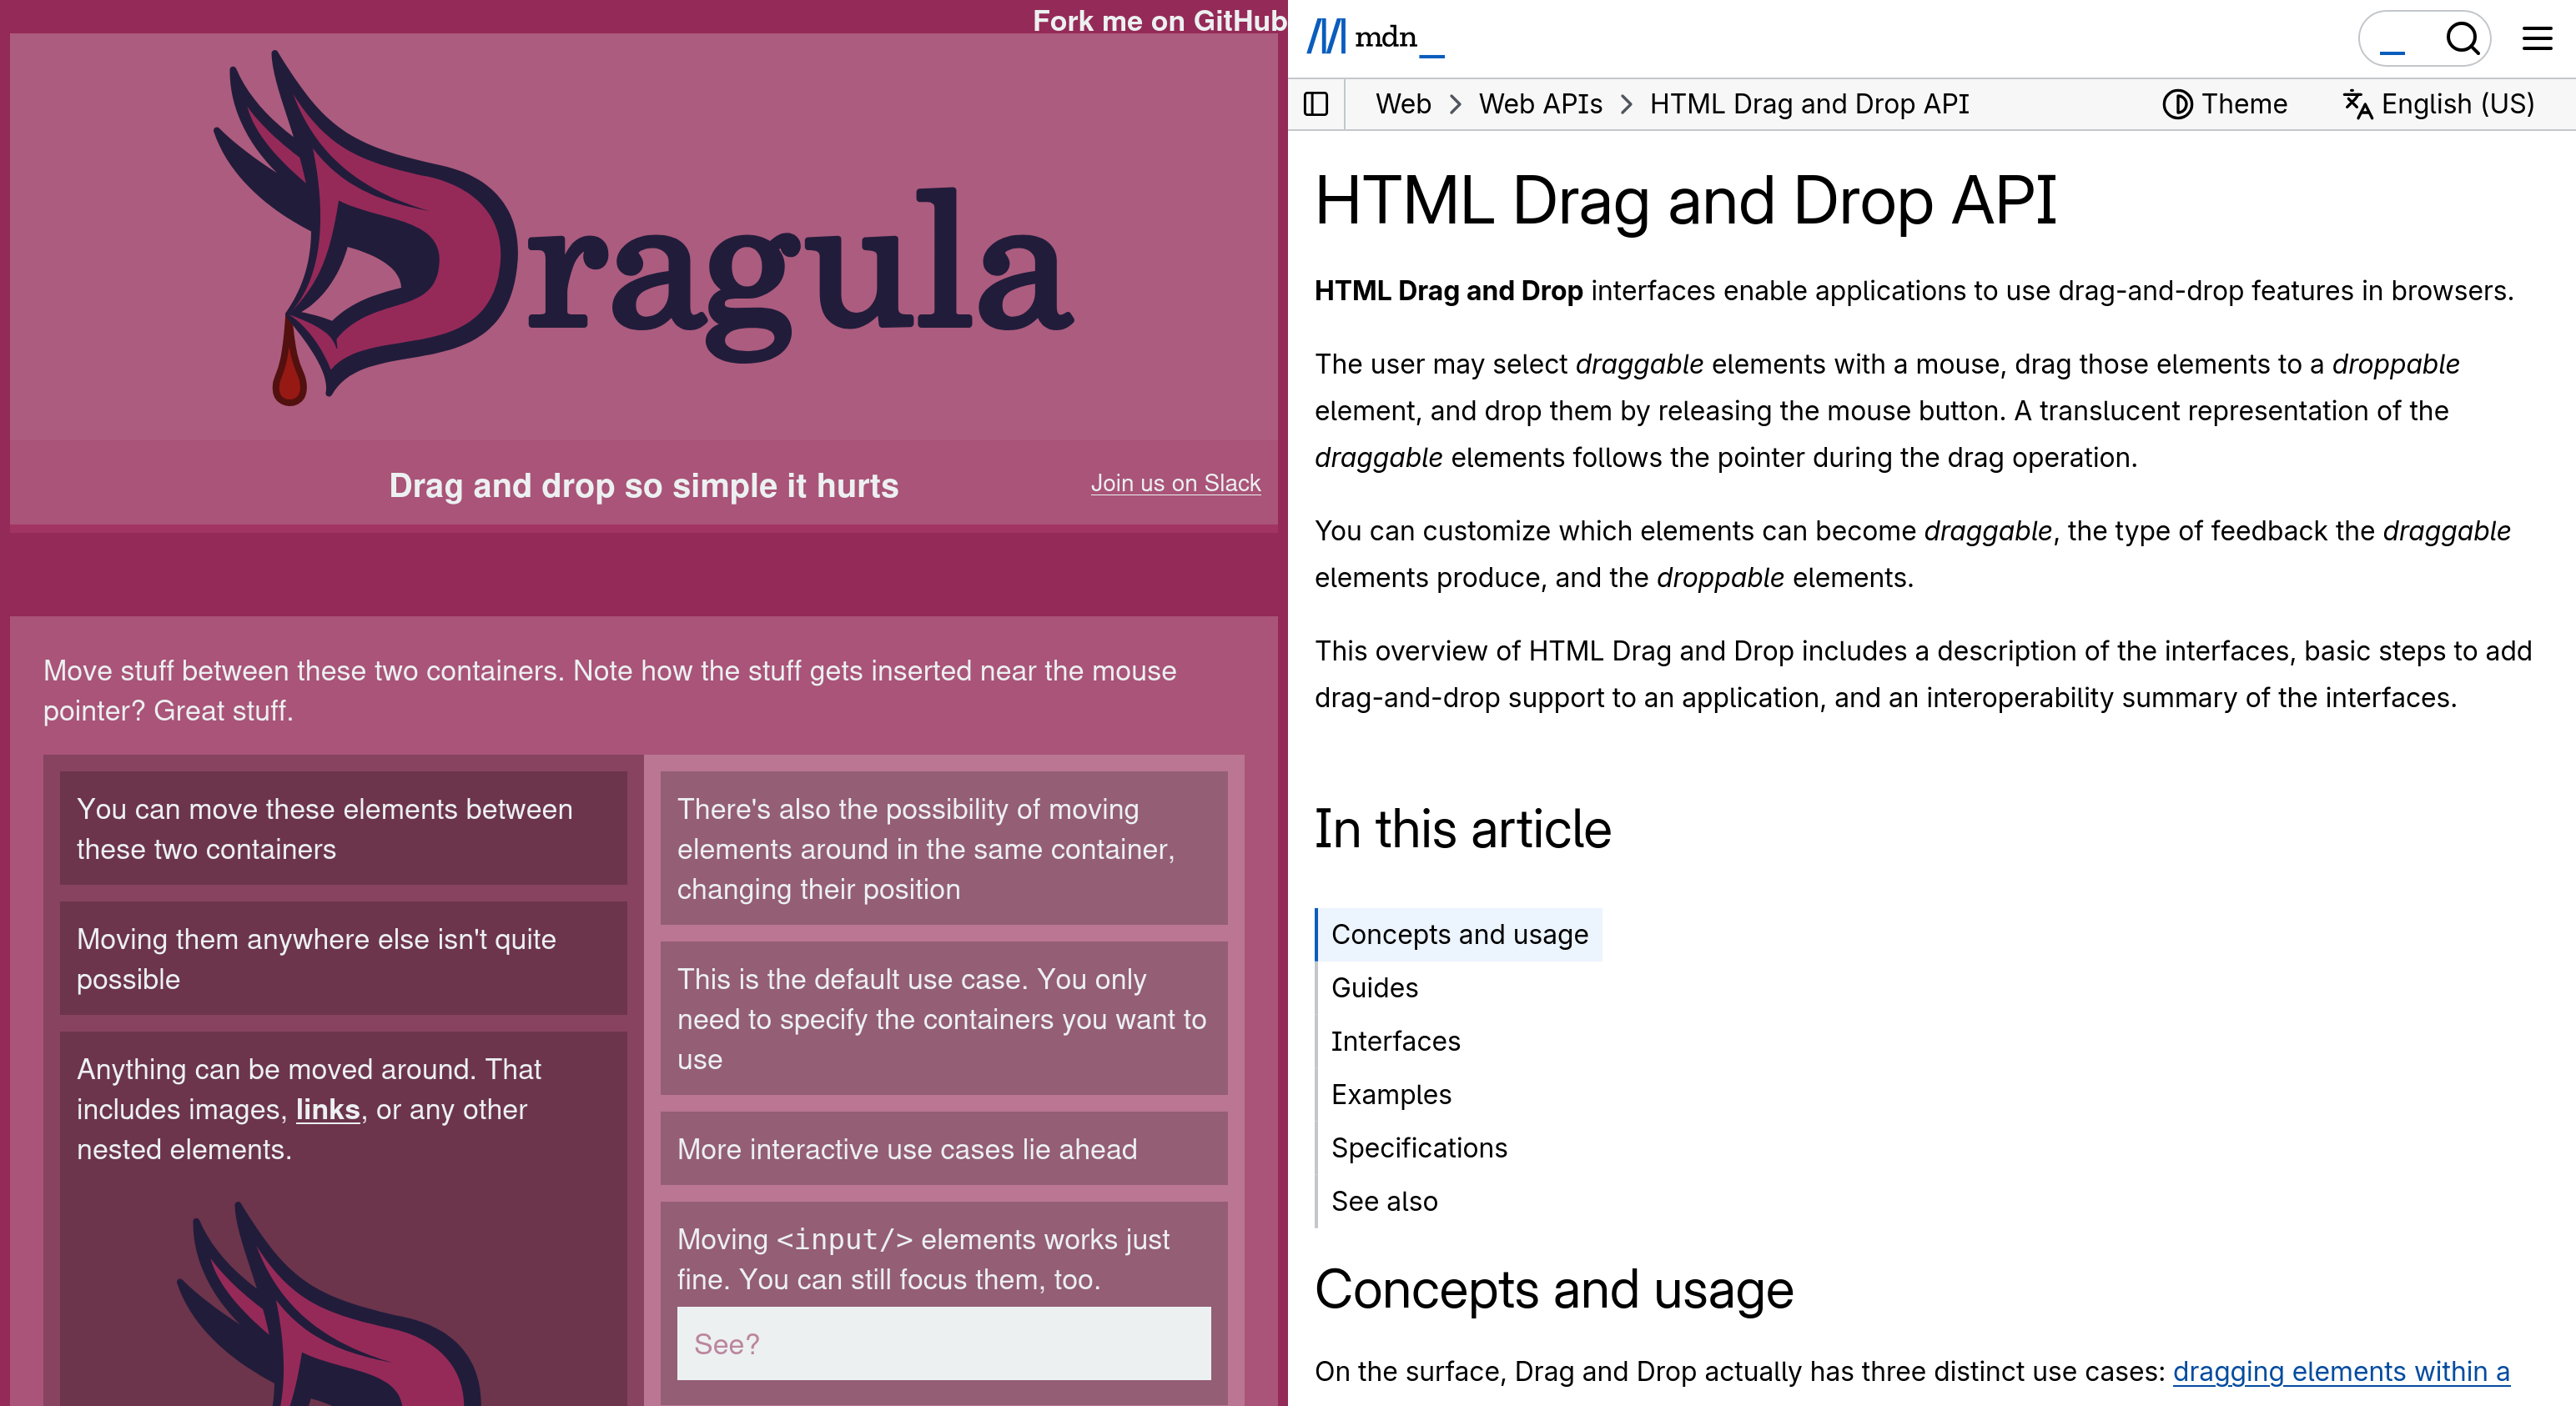
Screenshot of the Dragula website saying "drag and drop so simple it hurts" with a logo and stylized purple page versus the MDN page for the Drag and Drop API which looks much more subdued in comparison
The Dragula site versus the Drag and Drop MDN page. Arguably the former is still more compelling.

If it were just about third-party libraries versus platform APIs, though, then I don’t think it could fully explain the antipathy toward “use the platform.” Developers who are lazy (or do I repeat myself?), and who just want a ready-made solution for whatever problem they’re facing, are unlikely to care whether that solution comes from npm, the browser, or copied off of someone’s random GitHub Gist. They want to solve their problem and move on. But there’s a different source of anti-“use the platform” that I want to explore.

For a certain type of developer, building things yourself is just more fun. And often the resulting code is easier to reason about, especially if you don’t have an encyclopedic knowledge of the web platform. And once you’ve built something, there can be a kind of IKEA effect where you want to maintain and tinker with your own homemade code.

As an example, let’s imagine you’re trying to build a modal dialog. You might visually understand how these are supposed to work: content appears on the screen, but the background is still visible although partially occluded, and maybe clicking outside the dialog dismisses it. So you might grab for position:absolute and z-index to position the dialog correctly – aha, but the background still scrolls, so you have to disable overflow on the body… And then if you understand something about accessibility, you realize you need to handle Esc to dismiss, and build a focus trap, and return focus to the element that launched the dialog, and…

For many developers, what I just described sounds like a nightmare (and a good way to build something that only half-works). But for many developers, this sounds like fun! Think of how much you learn as you start building this thing. And think about how you could start putting your own spin on it by adding animations, themes, an optional “close” button… Before you know it, you’ve built a library that’s ready to go on npm. That’s way more fun than just grabbing <dialog> and calling it a day – what a downer!

And for many of us, before APIs like <dialog> existed, this was how we learned the web platform! Many of the people who now advocate for “use the platform” were once themselves authors of polyfills, shims, and libraries. I know because I’m one myself! I spent years working on tooling for IndexedDB, WebSQL, and other browser storage APIs as part of my work on PouchDB, which eventually led to me feeling confident enough to sit in W3C standards meetings and even open issues and pull requests on the IndexedDB spec itself. Without the forcing function of a gap in the platform that needed to be filled, I don’t know if I would have found the interest or motivation to get to that level of expertise.

Of course, doing it yourself is not always an unalloyed good. Sometimes it just comes from pure ignorance. On the web platform in particular, I think one of the reasons there was such a proliferation of JavaScript solutions to problems that could be better solved by CSS, for example, is that many developers just didn’t take the time to deeply understand how CSS works.

And to be fair, CSS has historically been hard to understand! There’s a reason the site is called “CSS Tricks.” Things like the clear fix, floats, and the min-width: 0 trick are hardly intuitive. Rather than trying to understand CSS’s internal algorithm, it’s often much easier to just imagine the imperative logic you want and then express it in JavaScript. Plus, for years CSS didn’t have a straightforward way to express common patterns like line clamping, textarea resizing, scrollbar hiding, etc. So of course developers built it themselves using the tools they already understood.

I don’t even think this phenomenon of “avoiding the platform” is limited to the web. It can apply to any developer working on top of a platform they don’t fully understand. For example, at my work, we use ClickHouse for storing various kinds of analytics data. At one point, my coworker and I disagreed about how to store large JSON data in a column: he built a system for compressing it before storage, whereas I put the data in a separate key-value store and only inserted the key into ClickHouse. It turned out we were both wrong! ClickHouse automatically compresses data, and as a columnar data store you actually get better compression across rows if you just let ClickHouse handle it. And the separate key-value store was just a poor man’s version of what a columnar SELECT already does.

I only realized these things after actually taking the time to thoroughly read the ClickHouse docs and then write a benchmark to prove my hypothesis. In the end I was shocked that we had built something that was slower and clunkier than what the platform itself could give us out-of-the-box. The parallels with JavaScript and the web platform were hard to ignore.

I’m sure that if you’re a developer on iOS or Android, or someone building on top of a game engine, or really any kind of developer building on top of any platform layer, you probably have similar stories. There’s a reason that the stereotype of the grizzled senior engineer is someone who can take a junior’s baroque tangled mess of code and replace it with a single line. The more you learn, the more you’re able to wield your knowledge of how the entire system works end-to-end to create the smallest possible contribution to it (and thus reduce your maintenance burden in the long run).

I’ve been trying really hard not to talk about AI this entire post (because I’ve done it to death over the past year), but of course I can’t help but wonder how AI coding will impact this phenomenon. I actually have both an optimistic and a pessimistic take:

  • Optimistic: because LLMs have an encyclopedic knowledge of whatever platform you’re working with, they can choose exactly the right platform API to deliver the experience the prompter asks for in vague English. And since this solution is likely faster and more correct than userland code, the agent will prefer it after rigorous testing and benchmarking. Furthermore, the “IKEA effect” goes away when developers are not actually writing the code themselves.
  • Pessimistic: because LLMs seem to love duplicating code – for example, ignoring helper functions that already exist in favor of writing their own for the umpteenth time – the amount of custom, non-platform-idiomatic code will skyrocket. Developers won’t instruct their agents to test enough or to try enough alternatives, and will just commit the agent’s first draft. And because it’s always possible to add more epicycles, the agents will continue to iterate on over-engineered solutions that never should have existed in the first place.

In my own use of AI coding, I’ve seen both phenomena happen. I’d like to think that as models and coding harnesses get better we’ll start to veer more towards the optimistic outcome, but I can’t say for sure.

In any case, these are my longwinded and somewhat conflicting thoughts on “use the platform.” As a mantra I love it, because it succinctly captures a feeling I have when I’m looking at some overwrought pile of spaghetti code and thinking how much better and more elegant it would be if the author just understood the layers beneath them a bit better. At the same time, I’ve been that author, and I’ve felt the joy of building such beautiful, messy code (beautiful to me, anyway), so I think it’s worth understanding where such developers are coming from. For that reason, I’m sure we’ll be hearing “use the platform” for as long as there are platforms.

You can comment on the fediverse or Lobsters.

You can just choose how many bugs you want now

There’s a bizarre aspect of AI coding that I’ve been trying to put my finger on, and I think it’s this: you can basically just decide how many bugs you want your software to have now.

We discovered this first with security, because of course security bugs are the most non-negotiable ones. But I think once the vulnpocalypse is over, we’ll start to turn our attention to other types of bugs: correctness, performance, accessibility, reliability, etc.

Some of us are already doing this. For example, I find myself spending a lot of time these days in code review, using tools like my triple-agent code review skill as well as Geoffrey Litt’s explain-diff skill.

My experience is that, in a complex system, you can basically find as many bugs as you ask the agents for. If you get tired of tackling bugs in the PR itself, have no fear: the agent will also find plenty of preexisting bugs for you to spend time on. The question is just when you want to stop and call it “done.”

Of course the bugs are not free to fix. There are still many tradeoffs to consider: lines-of-code versus likelihood that the bug will actually occur, the risk of introducing new bugs in a complex solution, the cost of making the code harder to understand for future reviewers or agents, etc. But the finding of the bugs has become nearly free, and AI agents are also capable of finding very subtle, intricate bugs that otherwise could have flown under the radar for years. What we do with this situation is the interesting question.

As many have noted, it doesn’t seem like the overall polish of software has increased since AI coding became a thing. If anything, there is just more junk and shovelware out there, of dubious quality. I think this demonstrates that, although our ability to find new bugs has skyrocketed, our overall tolerance for bugs has not changed. There are still plenty of winds blowing in the opposite direction:

  • The preventable problem paradox: if an incident occurs and you swoop in to fix it, you’re a hero. If you prevent the problem from ever occurring in the first place, then nobody knows you did anything.
  • Related: the pressure inside many software orgs is to keep shipping visible results, not to fine-tune something that already “works.” With AI coding this is magnified: management often assumes that 10x productivity means 10x more visible features and apps.
  • Laziness: one of the classic virtues of a programmer, this time working against us. I find myself mentally exhausted after slogging through the umpteenth AI-generated bug report, which requires me to carefully think through intricate aspects of the system and weigh the pros and cons of fixing it. I imagine many of my peers in the industry have just tuned out AI code reviews or only focus on the most critical findings.

Avoiding epicycles

There are a few ways we can approach this problem, though, that don’t require unending toil. One way is to set up the agent on a loop, e.g. “do a code review, fix all critical/high/medium issues, then repeat.” I find this can work, but it has a tendency to create lots of epicycles.

If you’re not familiar with the concept: in the pre-Copernican1 model of the solar system, ancient astronomers “fixed” miscalculations in the planets’ orbits by simply adding more circles to their movement. This improved the accuracy of the predictions, but at the cost of making the overall model more complicated. Obviously just saying “the earth moves around the sun” greatly simplifies the whole thing, but first you need the insight to make this simplification possible.

I’ve found that AI agents are pretty bad at such dramatic simplifications (in other words, “LLMs can’t jump”). They will happily build one epicycle per bug until the code is a spaghetti mess. So a valuable part of AI code review is still to ask questions like “How can we make this simpler?” and “Is there a fundamental flaw with the codebase that we should fix before we tackle this class of bugs?”

Another technique that works well is to have good tests. (Easier said than done!) For example, when I was playing around with vibe coding the W3C IndexedDB API, it became pretty clear to me that an agent could just grind through the test suite, and if it got close to 100% then I could be reasonably certain to have a bug-free implementation. But the only reason this works is because the Web Platform Tests are a phenomenally good test suite, honed by years of independent browser implementers discovering odd bugs and adding test cases for every unlikely scenario you can think of. Most companies, in their first-party codebases, could only dream of such a test suite.

I can imagine, though, that if you’re building a system from scratch, and especially if your goal is to reproduce the output of an existing system, then you can get pretty far by just putting all your effort into the test suite and then letting the agent go nuts on the rest. PGRust seems to be having some success with this.

A third technique is to just simplify your system design so that whole classes of bugs become impossible. For example, I’ve long been an advocate for multi-page apps (MPAs) over single-page apps (SPAs), just because, with MPAs, entire bug categories simply don’t exist: breaking the back button, losing scroll state, leaking client-side memory, improper accessibility during page navigations, etc.

Of course you lose some power with a simpler system versus a complex one, and maybe a reasonable answer is to deliberately choose a more complex system while also just fixing all the bugs. I feel though that this would still have a tendency towards epicycles, and I would much rather read (or debug!) a codebase built on simpler principles rather than one built on complex ones, even if they both have the same overall bug posture.

Conclusion

It’s become cliché to note that we’re in unprecedented times, and that everybody is figuring out what exactly software engineering is supposed to look like when robots can do a good chunk of what used to be “the job.” And yet, it still remains worth saying. Whatever I wrote in this blog post may become outdated in a matter of months, and the next 5 AI-related articles you read on Hacker News will probably argue 5 different opinions. It’s a cacophonous mess, and I have low confidence that I’ve figured out all the answers.

What I’ve defaulted to is focusing on the short term: i.e. what are agents good at today, and where can humans still provide some value. Some people are running with the assumption that all concerns of code quality, complexity, and maintainability will be swept away someday by agents that can easily manage whatever baroque legacy system they’re handed. That may end up true, but I’m not going to bet on it because I haven’t seen it yet. For now, I’m still concerned about things like the DRY and KISS principles, keeping a working theory of the code in my head (ala Peter Naur), and trying to steer the agent toward better code quality.

I do think it’s interesting though, that we have a much greater ability to tackle more and more subtle bugs than we ever had before. Maybe this will lead to a reliability renaissance, or maybe it will lead to the same overall bugginess, just with more apps and more features in each app. I know that my personal preference is for greater software craftsmanship, but it remains to be seen how the software industry as a whole will step up to this challenge.

Footnotes

1. Technically, Copernicus’s system still had epicycles, and only Kepler managed to get rid of them. I think in some ways this makes the analogy stronger: in software, a re-architecture sometimes isn’t obviously better right away, and only shows its value over time.

Using AI to write better code more slowly

A lot of people seem convinced that the point of AI coding is to write low-quality code as fast as possible. Spew out barely-passable slop, open massive PRs, and merge them unvetted. Ship it!

But the thing is, LLMs are very flexible. And you can use them just as effectively to write high-quality code more slowly.

This statement seems completely obvious to me at this point, and I almost didn’t want to write this post for that reason. But there seem to be enough people convinced that LLMs are only good as slop cannons that it’s worth making the opposite case.

If Mythos taught us anything, it’s that LLM agents are really good at finding bugs. Throw them at a codebase enough times, and they will find so many bugs that you’ll barely know what to do with them.

Like many others, I’ve also found this is true of non-Mythos models – some may be better than others at finding subtle bugs or avoiding false positives, but the fact is that the latest public models from Anthropic and OpenAI are good enough to find plenty of bugs in an unscrutinized codebase.

The problem is not so much finding the bugs, but instead prioritizing and validating them. For this reason I have a Claude skill I adapted from this article‘s core insight, which is that the more, different models you throw at a PR review, the less likely you are to get hallucinations or bogus bugs.

The skill says (paraphrasing):

Run a Claude sub-agent, Codex, and Cursor Bugbot to find bugs in this PR ranked by critical/high/medium/low. Once they’re all done, review their findings, do your own research to rule out false positives, and write a final report.

That’s basically it. You can add your own definition of “bug” if you want – mine has stipulations about the KISS and DRY principles, writing accessible HTML/JSX, using proper indexes for SQL queries, etc.

In my experience, this skill always finds tons of bugs in a PR, and the false positive rate is near zero. It finds so many bugs that you’ll be bored senseless if you try to tackle them all. They’ll range from critical security or correctness bugs to the more mundane medium-level perf bugs to low-level “this comment is misleading”-type bugs.

My typical workflow is:

  • Have an agent fix all the criticals and highs (with my guidance on the proper solution), then repeat until no criticals/highs
  • Skip highs/mediums where the juice isn’t worth the squeeze (e.g. 100 lines of code to fix a narrow edge case)
  • Abandon the PR if it has so many criticals that I realize the whole approach is misguided

When I use this technique, I haven’t necessarily seen my velocity go up. If anything, the review process often finds pre-existing bugs, so I end up on a tangential side-quest where I’m writing unit tests and fixing subtle flaws that pre-date the PR. This is the opposite of the “10x productivity” slop-cannon style of development that most people imagine when they think of vibe coding, but I find it very satisfying.

It’s a great way to improve the overall health of the codebase while also teaching you about the odd corners of it. In my experience, the happy-path of a complex architecture is less interesting than its failure modes. And pre-LLMs, this is usually how I got familiar with a codebase anyway: understanding where the assumptions break down, and then getting my hands dirty to fix it.

If you’re the kind of person who is skeptical that AI coding is good for anything, then I doubt this post will persuade you. But if you’re the kind of developer who uses agents to write multi-hundred-line PRs that you barely understand yourself, I’d invite you to slow down a bit and try this other, slower style of “vibe coding.” Ask an agent how your PR works and how it might fail. Have it write Markdown docs with Mermaid charts if necessary. Use Matt Pocock’s /grill-me skill until you understand the entire PR front-to-back.

You might not be more “productive” in terms of raw lines of code. You might burn a ton of tokens just to find out that your entire plan was wrongheaded from the start. But I find this style of coding to be a more super-powered version of the kind of programming I was already trying to do before LLMs: careful, methodical, quality-obsessed, focused on making things better for the next coder.

So take a deep breath, slow down, try this technique, and see if you don’t enjoy writing better code more slowly.

The diminished art of coding

Programming is an art. It’s less like fine art or music and closer to architecture or carpentry – combining form and function – but it is an art.

If you don’t believe me, consider code reviews. I’ve definitely done code reviews where I admired the mastery on display, where the elegance of the solution shone out like a brilliant gem, where I felt like Salieri overcome by the symphony in his head as he reads Mozart. Conversely, I’ve mentored juniors where I read their code and immediately saw opportunities to help them mature – this bit is repetitive, this bit could be expressed more succinctly, this bit hits a performance de-optimization, etc.

When I do PR reviews of AI-authored code, I feel none of these things. I can sometimes tell whether it’s authored by Claude or Codex (Claude likes lots of Official-Sounding Comments, Codex is more to-the-point), but my mind tends to wander to the intent behind the PR, to the prompt or the plan. Nitpicking details of the code, like the type of for-loop or the names of functions, feels entirely superfluous. Sometimes the best advice is to just choose a new plan and re-prompt.

For most of my career, I’ve held two contradictory views of coding in my head simultaneously:

  • Coding is an art form, but you shouldn’t get too sentimental about your code – most code eventually becomes technical debt that should be expunged
  • Code can express the creativity of the author, but the best code is idiomatic, reducing the WTFs per minute
  • In short: code is art, but it’s also a means to an end

With the advent of LLM coding agents, I think this contradiction has been firmly resolved in favor of function over form. Or as Les Orchard might put it, the “make-it-go people” have triumphed over the “craft-lovers.”

The craft is still there, of course, but it’s different. When I code with agents, I’m thinking at a much higher level of abstraction: architecture, resilience, systems, monitoring, testing. I used to sweat the small details – Claude starts comments with a capital letter, I rarely do; Claude names variables one way, I prefer another – but I quickly learned to stop caring. It’s simply a waste of time to nitpick, especially since the agent will likely undo your nitpicks on the next refactor.

In some ways I feel like a carpenter whose job is now to write the blueprints for the IKEA factory. Of course there is still artistry in designing the blueprints, but you don’t care if the factory spits out one or two tables with splinters in the legs. The point is to produce enough furniture fast enough that the little imperfections don’t matter. Taste and judgment still count, but they’re at the level of the overseer on the assembly line, not the master carpenter working a chisel.

Finding art elsewhere

For me, coding always occupied an odd place on the artistic spectrum. Some code is firmly art – Jenn Schiffer, for example, has been an artist-in-residence and has had numerous projects devoted to the intersection of art and programming. Whereas other code is purely functional: I’m sure many programmers have spent their entire careers pumping out glue code for enterprise CRMs without ever wondering if what they were making was “art.”

One worry I have for my entire generation of programmers is that many of us have been getting our artistic “fix” from coding: taking craftsmanship seriously, reviewing others’ code with the eye of a literary critic, trying to elevate the profession. Now the profession has been turned into an assembly line, and many of us are eagerly jumping into our new jobs as blueprint-designers without questioning what this will do to our souls. I believe art is necessary for a rich and full human life, so this isn’t an idle concern.

My advice to other coders, or at least the advice I’m taking myself, is that if you’re looking for art in coding: stop looking. If you’ve never taken an interest in poetry, or painting, or dance, or whatever, now would be a good time. In an era where the internet is increasingly full of bots pumping their bland bot ideas into everybody’s brains, seeking out distinctly human forms of expression has become vital.

It might sound corny (or like I’m going through a mid-life crisis), but I’ve done the following lately:

  • started painting (Bob Ross is of course an easy stepping stone)
  • gone to several ballets / contemporary dance performances
  • started reading more fiction (The Sun Magazine is a longtime favorite of mine, but I’m even reading the poetry now)
  • picked up my guitar again

You might have also noticed that this blog has gotten a lot more sentimental and experimental lately. I’ve never used LLMs to help with my writing (not even to spellcheck!), but lately I’ve tried to fight my own tendencies to write bland, predictable prose. In a world of machines that “predict the next token,” what’s the best reaction? Be less predictable. At least that’s what I hope I’m doing.

I don’t think coding is dead as an art form, and I do think that the “new” craftsmanship will have its own masters, its own styles, its own expressiveness. Heck, maybe I’ll be surprised and there will be an artist-in-residence somewhere wielding agent orchestrators like a paintbrush! But I kind of doubt it. If you’re not knitting, then you’re making clothes on an assembly line, and if the clothes are disposable, then it’s just fast-fashion. There’s artistry there, perhaps, but the end product is much less interesting artistically because there’s less of the human touch to it.

In my view, we’re firmly in the fast-fashion era of coding: software is vibe-coded, used up, thrown away, vibe-coded again. This is not a fully bad thing, and I’m sure many non-coders especially are giddy at the superpowers they’ve acquired. But as coders, we shouldn’t lose sight of what we’ve lost, and we should seek to make up for it with new sources of artistic sustenance.

You had a story

You had a story you used to tell yourself about how you got here in life.

You’d share the story with others. Maybe you’d be at a party, and someone would ask what you do, and you’d say, “I’m a programmer.” And their eyes would perk up and their mind would fill with images of ball pits and propeller beanies and that funny movie with Jesse Eisenberg, and they’d say, “Oh yeah, like you build apps?”

And you’d proudly brush it off and say something like, “Yeah I work on the backend, you don’t know what that is, but it’s basically the magical thing in the cloud that makes your apps work.” Or you’d say, “Yeah I work on the frontend, it’s the thing you touch all day long on your phone, I make it look good and run fast.”

And if you thought about what it took to get there, you’d think of the lines of code, fuzzy green text in a black terminal, the mystical incantations that lit up the glowing rectangles that everyone else was staring at all day. They didn’t know the effort, the raw-adrenaline flow of code bursting from your fingertips as you wove dreams into pixels. Or the writer’s block of the showstopper bug that nagged you on your jog and in the shower until suddenly the answer came to you when you awoke, as if from a dream, and you rushed to the keyboard to pound out the solution, the pure exhilaration of making the computer obey you.

Then someday somebody took that story from you. They told a different story: one where someone on a stage, in a business suit that you’d never wear, with a smug grin that you’d never wear, talked words into a computer and, the little traitor, it obeyed him. He talked words like you or I would, like any simpleton would, and it obeyed him. And the crowd cheered because they knew that now the glowing rectangles belonged to them as well, and not just you, with your wizardly spells that took years of study to master.

When you see your brother at Thanksgiving, he’s excitedly showing your parents an app he built to track football scores. Except he didn’t really build it, you think to yourself bitterly. He’s not a programmer, he’s a mechanic, and maybe he knows his way around cars, but he never grinded LeetCode to pass an interview, or stayed up late studying Data Structures and Algorithms to pass an exam. “Let you brother have this one,” your dad chides you after an outburst at the dinner table. “It’s just an app.” Just an app, you scoff with amazement.

When you go home, you pour yourself a stiff drink and wonder what kind of story you can tell yourself now. You were Superman, and now every schmuck puts on a cape and thinks they can fly. The fools! They’ll fall. They’ll fall and crash, you reassure yourself as you take a swig.

Your friends agree. “This stuff will never work,” they say, as if with bored detachment. “Remember low-code? Remember no-code? What a joke.” But you notice something: a fear in their eyes that you’ve never seen before. You don’t feel reassured.

Eventually you find that your own colleagues are warming to the stuff. “It’s actually pretty useful,” they say. “Give it a shot.” You’re astounded by the pure treason. Don’t they realize this is a rejection of everything they’ve done their entire careers, an insult to their very dignity as a programmer? They shrug. “Sure, but times change. I want to have a job in five years.”

Five years. Your retirement is looming. And you were looking forward to leaving at the top of your game, maybe to tinker on some side projects after money is no longer an issue. But now you don’t know about the money, or the side projects, or whether you’ll be at the top of your game anymore or just a washed-up has-been. The panic is really starting to set in now, and you’re looking for an out.

You approach the tool out of resentment – cautiously, like a cursed artifact. You hold the dead thing at arm’s length, as if its very aura might poison you. You try it out, and it chirps happy success but everything it spits out is failure. You close the laptop lid. Vindication! The thing truly is dead, a fraud, a sham. You can return satisfied to your beloved craft.

Except your craft doesn’t feel right anymore. More and more, you read about astounding feats created with the accursed tool. Colleagues you trust and admire are now reconfirming, in more strident tones, that it actually works. The treason is all around you, choking your joy, ruining what once gave you so much meaning. You can barely stand to look at the blinking cursor in your text editor anymore, which has also betrayed you with its daily offers to steal your voice, retire your fingers, extinguish your spark.

You start to wonder if this industry is even right for you anymore. How can it be right when everything around you feels so wrong? And always, there is the fear: fear that you are losing ground, fear that you won’t make it past the next layoffs, fear that you’ll be joining your brother in the auto shop and he’ll be showing you the ropes, you with your fumbling fingers that can barely hold a wrench, and oh by the way did you see the app he built to replace his content management system?

Where the story goes next is for you to decide. Maybe you can skate by for a few more years in a sinecure, holding onto a payslip for dear life, while the world moves whooshing around you. Maybe you’ll give in and learn the new tools, but with a kind of detached ambivalence, going through the motions but no longer feeling joy or meaning or like you have something worth talking about at a dinner party.

Or maybe you’ll look around and study those who have adapted to the new world and are thriving. Maybe you’ll notice the coworker who brushed off all the doom and gloom and just says, “Hey, look at this cool thing I built.” And maybe you’ll notice that this coworker has their own kind of mastery, their own tools and workflows with odd names that turn you off at first but ultimately pique your curiosity. Maybe you’ll wonder if it makes more sense to hang out with the people building and sharing and having fun instead of those who mope and whinge and cry for a lost golden age. Maybe instead of being ruled by fear, you’ll find your creative spark again.

Because isn’t that the point in the first place? Isn’t that why you got into programming? Wasn’t it to make something, to put it out in the world and bring joy to others with your creation? Wasn’t it to make a song out of sand, a painting out of pure thought, a miracle out of nothing, regardless of how you did it?

If it is, then you might find that the story you need to tell about yourself, about who you are and where you came from and why you create, was right there all along. The story has been told hundreds of times throughout history – only the characters and the scenery change – and you still have it in you. You found it once before, and if you search for it with curiosity and an open heart, you’ll find it again. It never really left you.

Days of miracle and wonder

Oprah Winfrey and I have something in common, which is that our favorite album is Paul Simon’s Graceland.

I’ve been thinking a lot recently about the opening track, “The Boy in the Bubble”. The song can be read a few different ways, but I read it as an aging man amazed by modernity but also kind of frightened by it, and comforting his loved one with:

These are the days of miracle and wonder, and don’t cry baby, don’t cry, don’t cry

If these are “the days of miracle and wonder,” then why would anyone want to cry about it? Well, a few different reasons:

These are the days of lasers in the jungle, lasers in the jungle somewhere

Staccato signals of constant information

A loose affiliation of millionaires and billionaires

Sound familiar? It was written in 1986, but it could have been written today.

One thing I’ve noticed during our recent technological turbulations is that some people seem to have lost the capacity for wonder, or are willfully ignorant of the wonders around them. And if you can’t acknowledge that something extraordinary has happened, then you can’t start grieving for what has been lost (the subject of my last post). To me, this is the opposite of what Paul Simon is advocating: awe for the future combined with reverence for the past.

For example, I have a lot of conversations on Mastodon that start with me acknowledging some flabbergasting feat that coding agents have accomplished lately, like one-shotting a browser API that passes 77% of the relevant Web Platform Tests, or building a rudimentary browser that can render basic web pages, or building a C compiler that can compile the Linux kernel, etc. Then the interlocutor says something like, “Sure, but are the Web Platform Tests really representative of a working browser?” (Short answer: yes, it’s the entire basis of cross-browser projects like Interop.) Or: “Well sure, but is the code maintainable and bug-free?”

I find these conversations kind of baffling. It’s as if you’ve been shown a talking dog that can also sing the blues and play steel-string guitar, and your first response is, “Yeah, but the second verse was a bit off-key.” I understand skepticism – being skeptical is good, and there is a ton of hype and hogwash out there in the “AI era,” but like… can we just take a moment to be amazed? None of this was imaginable even three years ago, and now it’s practically worthy of the snooze button.

In fact, some of my more AI-adept colleagues are actually not much impressed with these stories, precisely because they know that even more amazing stories are likely around the corner. The lasers in the jungle have become so commonplace that we hardly notice them anymore.

Personally, I’m trying to maintain my skepticism as well as my sense of wonder. There’s so much breathless hype out there that it clouded my judgment for a while, but I’m also humbled by how fast things have moved, defying my early expectations.

I don’t consider myself a tech optimist – I seriously doubt we’ll ever travel to Mars, let alone colonize it, and I think predictions of the singularity or uploading our brains into the cloud are fun science fiction but hardly a bet I would take on the optimists’ side. But I have to admit that I was wrong on AI coding, so I’m prepared for my expectations to be defied again.

In many ways, I feel like the last year has been a victory for the techno-optimists – LinkedIn bros, Elon Musk stans, former NFT-peddlers – over artists, tech critics, and left-leaning intellectuals, which has been a bitter pill for me to swallow, since I identify with the second group much more than the first. This is what I was trying to get at with “AI tribalism”, although in retrospect I was a bit clumsy about it.

So if you’re feeling like me, and a bit bitter that the tech bros are taking a victory lap right now, and maybe hoping that they realize their shoelaces are untied and fall flat on their faces, I’d suggest taking a different tack. Disregard the hype, ignore the breathless prognostications of eternal abundance, and just look around and ask yourself if you would have been impressed by any of this three years ago. If so, take a moment to be amazed. It doesn’t make you a stooge or a credulous mark; it just makes you human.

And if you have to grieve, grieve. Technology is changing in scary and unpredictable ways, and not all the changes are positive. (Far from it – I wonder if someday we’ll look back on the invention of LLMs like the invention of the atom bomb.) But eventually we should move on from our grief, because the world is not ending; it’s just turning, as it always has.

In other words:

These are the days of miracle and wonder, and don’t cry baby, don’t cry, don’t cry

We mourn our craft

I didn’t ask for this and neither did you.

I didn’t ask for a robot to consume every blog post and piece of code I ever wrote and parrot it back so that some hack could make money off of it.

I didn’t ask for the role of a programmer to be reduced to that of a glorified TSA agent, reviewing code to make sure the AI didn’t smuggle something dangerous into production.

And yet here we are. The worst fact about these tools is that they work. They can write code better than you or I can, and if you don’t believe me, wait six months.

You could abstain out of moral principle. And that’s fine, especially if you’re at the tail end of your career. And if you’re at the beginning of your career, you don’t need me to explain any of this to you, because you already use Warp and Cursor and Claude, with ChatGPT as your therapist and pair programmer and maybe even your lover. This post is for the 40-somethings in my audience who don’t realize this fact yet.

So as a senior, you could abstain. But then your junior colleagues will eventually code circles around you, because they’re wearing bazooka-powered jetpacks and you’re still riding around on a fixie bike. Eventually your boss will start asking why you’re getting paid twice your zoomer colleagues’ salary to produce a tenth of the code.

Ultimately if you have a mortgage and a car payment and a family you love, you’re going to make your decision. It’s maybe not the decision that your younger, more idealistic self would want you to make, but it does keep your car and your house and your family safe inside it.

Someday years from now we will look back on the era when we were the last generation to code by hand. We’ll laugh and explain to our grandkids how silly it was that we typed out JavaScript syntax with our fingers. But secretly we’ll miss it.

We’ll miss the feeling of holding code in our hands and molding it like clay in the caress of a master sculptor. We’ll miss the sleepless wrangling of some odd bug that eventually relents to the debugger at 2 AM. We’ll miss creating something we feel proud of, something true and right and good. We’ll miss the satisfaction of the artist’s signature at the bottom of the oil painting, the GitHub repo saying “I made this.”

I don’t celebrate the new world, but I also don’t resist it. The sun rises, the sun sets, I orbit helplessly around it, and my protests can’t stop it. It doesn’t care; it continues its arc across the sky regardless, moving but unmoved.

If you would like to grieve, I invite you to grieve with me. We are the last of our kind, and those who follow us won’t understand our sorrow. Our craft, as we have practiced it, will end up like some blacksmith’s tool in an archeological dig, a curio for future generations. It cannot be helped, it is the nature of all things to pass to dust, and yet still we can mourn. Now is the time to mourn the passing of our craft.

AI tribalism

“Heartbreaking: The Worst Person You Know Just Made a Great Point” – ClickHole

“When the facts change, I change my mind. What do you do, sir?” – John Maynard Keynes, paraphrased

2025 was a weird year for me. If you had asked me exactly a year ago, I would have said I thought LLMs were amusing toys but inappropriate for real software development. I couldn’t fathom why people would want a hyperactive five-year-old to grab their keyboard every few seconds and barf some gobbledygook into their IDE that could barely compile.

Today, I would say that about 90% of my code is authored by Claude Code. The rest of the time, I’m mostly touching up its work or doing routine tasks that it’s slow at, like refactoring or renaming.

By now the battle lines have been drawn, and these arguments are getting pretty tiresome. Every day there’s a new thinkpiece on Hacker News about how either LLMs are the greatest thing ever or they’re going to destroy the world. I don’t write blog posts unless I think I have something new to contribute though, so here goes.

What I’ve noticed about a lot of these debates, especially if you spend a lot of time on Mastodon, Bluesky, or Lobsters, is that it’s devolved into politics. And since politics long ago devolved into tribalism, that means it’s become tribalism.

I remember when LLMs first exploded onto the scene a few years ago, and the same crypto bros who were previously hawking monkey JPEGs suddenly started singing the praises of AI. Meanwhile upper management got wind of it, and the message I got (even if they tried to use euphemisms, bless their hearts) was “you are expendable now, learn these tools so I can replace you.” In other words, the people whose opinions on programming I respected least were the ones eagerly jumping from the monkey JPEGs to these newfangled LLMs. So you can forgive me for being a touch cynical and skeptical at the start.

Around the same time, the smartest engineers I knew were maybe dabbling with LLMs, but overall unimpressed with the hallucinations, the bugs, and just the overall lousiness of these tools. I remember looking at the slow, buggy output of an IDE autocomplete and thinking, “I can type faster than this. And make fewer mistakes.”

Something changed in 2025, though. I’m not an expert on this stuff, so I have no idea if it was Opus 4.5 or reinforcement learning or just that Claude Code was so cleverly designed, but some threshold was reached. And I noticed that, more and more, it just didn’t make sense for me to type stuff out by hand (and I’m a very fast typist!) when I could just write a markdown spec, work with Claude in plan mode to refine it, and have it do the busywork.

Of course the bugs are still there. It still makes dumb mistakes. But then I open a PR, and Cursor Bugbot works its magic, and it finds bugs that I never would have thought of (even if I had written the code myself). Then I plug it back into Claude, it fixes it, and I start to wonder what the hell my job as a programmer even is anymore.

So that’s why, when I read about Steve Yegge’s Gas Town or Geoffrey Huntley’s Ralph loops (or this great overview by Anil Dash), I no longer brush it off as pure speculation or fantasy. I’ve seen what these tools can do, I’ve seen what happens when you lash together some very stupid barnyard animals and they’ve suddenly built the Pyramids, so I’m not surprised when smart engineers say that the solution to bad AI is to just add more AI. This is already working for me today (in my own little baby systems I’ve built), and I don’t have to imagine some sci-fi future to see what’s coming next.

The models don’t have to get better, the costs don’t have to come down (heck, they could even double and it’d still be worth it), and we don’t need another breakthrough. The breakthrough is already here; it just needs a bit more tinkering and it will become a giant lurching Frankenstein-meets-Akira-meets-the-Death-Star monster, cranking out working code from all 28 of its sub-agent tentacles.

I can already hear the cries of protest from other engineers who (like me) are clutching onto their hard-won knowledge. “What about security?” I’ve had agents find security vulnerabilities. “What about performance?” I’ve had agents write benchmarks, run them, and iterate on solutions. “What about accessibility?” Yeah they’re dumb at that – but if you say the magic word “accessibility,” and give them a browser to check their work, then suddenly they’re doing a better job than the median web dev (which isn’t saying much, but hey, it’s an improvement).

And honestly, even if all that doesn’t work, then you could probably just add more agents with different models to fact-check the other models. Inefficient? Certainly. Harming the planet? Maybe. But if it’s cheaper than a developer’s salary, and if it’s “good enough,” then the last half-century of software development suggests it’s bound to happen, regardless of which pearls you clutch.

I frankly didn’t want to end up in this future, and I’m hardly dancing on the grave of the old world. But I see a lot of my fellow developers burying their heads in the sand, refusing to acknowledge the truth in front of their eyes, and it breaks my heart because a lot of us are scared, confused, or uncertain, and not enough of us are talking honestly about it. Maybe it’s because the initial tribal battle lines have clouded everybody’s judgment, or maybe it’s because we inhabit different worlds where the technology is either better or worse (I still don’t think LLMs are great at UI for example), but there’s just a lot of patently unhelpful discourse out there, and I’m tired of it.

To me, the truth is this: between the hucksters selling you a ready-built solution, the doomsayers crying the end of software development, and the holdouts insisting that the entire house of cards is on the verge of collapsing – nobody knows anything. That’s the hardest truth to acknowledge, and maybe it’s why so many of us are scared or lashing out.

My advice (and I’ve already said I know nothing) would just be to experiment, tinker, and try to remain curious. It certainly feels to me like software development is unrecognizable from where it was 3 years ago, so I have no idea where it will be 3 years from now. It’s gonna be a bumpy ride for everyone, so just try have some empathy for your fellow passengers in the other tribe.

How I use AI agents to write code

Yes, this is the umpteenth article about AI and coding that you’ve seen this year. Welcome to 2025.

Some people really find LLMs distasteful, and if that’s you, then I would recommend that you skip this post. I’ve heard all the arguments, and I’m not convinced anymore.

I used to be a fairly hard-line anti-AI zealot, but with the release of things like Claude Code, OpenAI Codex, Gemini CLI, etc., I just can’t stand athwart history and yell “Stop!” anymore. I’ve seen my colleagues make too much productive use of this technology to dismiss it as a fad or mirage. It writes code better than I can a lot of the time, and that’s saying something because I’ve been doing this for 20 years and I have a lot of grumpy, graybeard opinions about code quality and correctness.

But you have to know how to use AI agents correctly! Otherwise, they’re kind of like a finely-honed kitchen knife attached to a chainsaw: if you don’t know how to wield it properly, you’re gonna hurt yourself.

Basic setup

I use Claude Code. Mostly because I’m too lazy to explore all the other options. I have colleagues who swear by Gemini or Codex or open-source tools or whatever, but for me Claude is good enough.

First off, you need a good CLAUDE.md (or AGENTS.md). Preferably one for the project you’re working in (the lay of the land, overall project architecture, gotchas, etc.) and one for yourself (your local environment and coding quirks).

This seems like a skippable step, but it really isn’t. Think about your first few months at a new job – you don’t know anything about how the code works, you don’t know the overall vision or design, so you’re just fumbling around the code and breaking things left and right. Ideally you need someone from the old guard, who really knows the codebase’s dirty little secrets, to write a good CLAUDE.md that explains the overall structure, which parts are stable, which parts are still under development, which parts have dragons, etc. Otherwise the LLM is just coming in fresh to the project every time and it’s going to wreak havoc.

As for your own personal CLAUDE.md (i.e. in ~/.claude), this should just be for your own coding quirks. For example, I like the variable name _ in map() or filter() functions. It’s like my calling card; I just can’t do without it.

Overall strategy

I’ve wasted a lot of time on LLMs. A lot of time. They are every bit as dumb as their critics claim. They will happily lead you down the garden path and tell you “Great insight!” until you slowly realize that they’ve built a monstrosity that barely works. I can see why some people try them out and then abandon them forever in disgust.

There are a few ways you can make them more useful, though:

  1. Give them a feedback loop, usually through automated tests. Automated tests are a good way for the agent to go from “I’ve fixed the problem!” to “Oh wait, no I didn’t…” and actually circle in on a working solution.
  2. Use the “plan mode” for more complicated tasks. Just getting the agent to “think” about what it’s doing before it executes is useful for something simpler than a pure refactor or other rote task.

For example, one time I asked an agent to implement a performance improvement to a SQL query. It immediately said “I’ve found a solution!” Then I told it to write a benchmark and use a SQL EXPLAIN, and it immediately realized that it actually made things slower. So the next step was to try 3 different variants of the solution, testing each against the benchmark, and only then deciding on the way forward. This is eerily similar to my own experience writing performance optimizations – the biggest danger is being seduced by your own “clever” solution without actually rigorously benchmarking it.

This is why I’ve found that coding agents are (currently) not very good at doing UI. You end up using something like the Playwright or Chrome DevTools MCP/skill, and this either slurps up way too many tokens, or it just slows things down considerably because the agent has to inspect the DOM (tokens galore) or write a Playwright script and take a screenshot to inspect it (slooooooow). I’ve watched Claude fumble over closing a modal dialog too often to have patience for this. It’s only worthwhile if you’re willing to let the agent run over your lunch break or something.

The AI made a mistake? Add more AI

This one should be obvious but it’s surprisingly not. AIs tend to make singular, characteristic mistakes:

  1. Removing useful comments from previous developers – “this is a dumb hack that we plan to remove in version X” either gets deleted or becomes some Very Official Sounding Comment that obscures the original meaning.
  2. Duplicating code. Duplicating code. I don’t know why agents love duplicating code so much, but they do. It’s like they’ve never heard of the DRY principle.
  3. Making subtle “fixes” when refactoring code that actually break the original intent. (E.g. “I’ll just put an extra null check in here!”)

Luckily, there’s a pretty easy solution to this: you shut down Claude Code, start a brand-new session, and tell the agent “Hey, diff against origin/main. This is supposed to be a pure refactor. Is it really though? Check for functional bugs.” Inevitably, the agent will find some errors.

This seems to work better if you don’t tell the agent that the code is yours (presumably because it would just try to flatter you about how brilliant your code is). So you can lie and say you’re reviewing a colleague’s PR or something if you want.

After this “code review” agent runs, you can literally just shut down Claude Code and run the exact same prompt again. Run it a few times until you’re sure that all the bugs have been shaken out. This is shockingly effective.

Get extra work done while you sleep

One of the most addictive things about Claude Code is that, when I sign off from work. I can have it iterate on some problem while I’m off drinking a beer, enjoying time with my family, or hunkering down for a snooze. It doesn’t get tired, it doesn’t take holidays, and it doesn’t get annoyed at trying 10 different solutions to the same problem.

In a sense then, it’s like my virtual Jekyll-and-Hyde doppelganger, because it’s getting work done that I never would have done otherwise. Sometimes the work is a dud – I’ll wake up and realize that the LLM got off on some weird tangent that didn’t solve the real problem, so I’ll git reset --hard and start from scratch. (Often I’ll use my own human brain for this stuff, since this situation is a good hint that it’s not the right job for an LLM.)

I’ve found that the biggest limiting factor in these cases is not the LLM itself, but rather just that Claude Code asks for permission on every little thing, to where I’ve developed an automation blindness where I just skim the command and type “yes.” This scares me, so I’ve started experimenting with running Claude Code in a Podman container in yolo mode. Due to the lethal trifecta, though, I’m currently only comfortable doing this with side projects where I don’t care if my entire codebase gets sent to the dark web (or whatever it is misbehaving agents might do).

This unfortunately leads to a situation where the agent invades my off-work hours, and I’m tempted to periodically check on its progress and either approve it or point it in another direction. But this becomes more a problem of work-life balance than of human-agent interaction – I should probably just accept that I should enjoy my hobbies rather than supervising a finicky agent round-the-clock!

Conclusion

I still kind of hate AI agents and feel ambivalent toward them. But they work. When I read anti-AI diatribes nowadays, my eyes tend to glaze over and I think of the quote from Galileo: “And yet, it moves.” All your arguments make a lot of sense, they resonate with me a lot, and yet, the technology works. I write an insane amount of code these days in a very short number of hours, and this would have been impossible before LLMs.

I don’t use LLMs for everything. I’ve learned through bitter experience that they are just not very good at subtle, novel, or nebulous projects that touch a lot of disparate parts of the code. For that, I will just push Claude to the side and write everything myself like a Neanderthal. But those cases are becoming fewer and further between, and I find myself spending a lot of time writing specs, reviewing code, or having AIs write code to review other AIs’ code (like some bizarre sorcerer’s apprentice policing another sorcerer’s apprentice).

In some ways, I compare my new role to that of a software architect: the best architects I know still get their hands dirty sometimes and write code themselves, if for no other reason than to remember the ground truth of the grunts in the trenches. But they’re still mostly writing design documents and specs.

I also don’t use AI for my open-source work, because it just feels… ick. The code is “mine” in some sense, but ultimately, I don’t feel true ownership over it, because I didn’t write it. So it would feel weird to put my name on it and blast it out on the internet to share with others. I’m sure I’m swimming against the tide on this one, though.

If I could go back in time and make it so LLMs were never a thing… I might still do it. I really had a lot more fun writing all the code myself, although I am having a different sort of fun now, so I can’t completely disavow it.

I’m reminded of game design – if you create a mechanic that’s boring, but which players can exploit to consistently win the game (e.g. hopping on turtle shells for infinite 1-Ups), then they’ll choose that strategy, even if they end up hating the game and having less fun. LLMs are kind of like that – they’re the obvious optimal strategy, and although they’re less fun, I’ll keep choosing them.

Anyway, I may make a few enemies with this post, but I’ve long accepted that what I write on the internet will usually attract some haters. Meanwhile I think the vast majority of developers have made their peace with AI and are just moving on. For better or worse, I’m one of them.

The fate of “small” open source

By far the most popular npm package I’ve ever written is blob-util, which is ~10 years old and still gets 5+ million weekly downloads.

It’s a small collection of utilities for working with Blobs in JavaScript. I wrote it because I found that PouchDB users were endlessly confused about how to work with Blobs and how to convert them to strings, ArrayBuffers, etc.

Given that some 80% of developers are now using AI in their regular work, blob-util is almost certainly the kind of thing that most developers would just happily have an LLM generate for them. Sure, you could use blob-util, but then you’d be taking on an extra dependency, with unknown performance, maintenance, and supply-chain risks.

And sure enough, Claude will happily spit out whatever Blob utilities you need when prompted:

> Write me a utility function in TypeScript to convert a Blob to an ArrayBuffer. It should return a Promise.

function blobToArrayBuffer(blob: Blob): Promise<ArrayBuffer> {
  return new Promise((resolve, reject) => {
    const reader = new FileReader();
    
    reader.onload = () => {
      if (reader.result instanceof ArrayBuffer) {
        resolve(reader.result);
      } else {
        reject(new Error('Failed to read Blob as ArrayBuffer'));
      }
    };
    
    reader.onerror = () => {
      reject(reader.error);
    };
    
    reader.readAsArrayBuffer(blob);
  });
}

Claude’s version is pretty close to the blob-util version (unsurprising, since it was probably trained on it!). Although it’s much more verbose, unnecessarily checking if readAsArrayBuffer actually gives you an ArrayBuffer (although this does make TypeScript happy). To be fair, it also improves on my implementation by directly rejecting with an error rather than the more awkward onerror event.

I suppose some people would see this as progress: fewer dependencies, more robust code (even if it’s a bit more verbose), quicker turnaround time than the old “search npm, find a package, read the docs, install it” approach.

I don’t have any excessive pride in this library, and I don’t particularly care if the download numbers go up or down. But I do think something is lost with the AI approach. When I wrote blob-util, I took a teacher’s mentality: the README has a cutesy and whimsical tutorial featuring Kirby, in all his blobby glory. (I had a thing for putting Nintendo characters in all my stuff at the time.)

The goal wasn’t just to give you a utility to solve your problem (although it does that) – the goal was also to teach people how to use JavaScript effectively, so that you’d have an understanding of how to solve other problems in the future.

I don’t know which direction we’re going in with AI (well, ~80% of us; to the remaining holdouts, I salute you and wish you godspeed!), but I do think it’s a future where we prize instant answers over teaching and understanding. There’s less reason to use something like blob-util, which means there’s less reason to write it in the first place, and therefore less reason to educate people about the problem space.

Even now there’s a movement toward putting documentation in an llms.txt file, so you can just point an agent at it and save your brain cells the effort of deciphering English prose. (Is this even documentation anymore? What is documentation?)

Conclusion

I still believe in open source, and I’m still doing it (in fits and starts). But one thing has become clear to me: the era of small, low-value libraries like blob-util is over. They were already on their way out thanks to Node.js and the browser taking on more and more of their functionality (see node:glob, structuredClone, etc.), but LLMs are the final nail in the coffin.

This does mean that there’s less opportunity to use these libraries as a springboard for user education (Underscore.js also had this philosophy), but maybe that’s okay. If there’s no need to find a library to, say, group the items in an array, then maybe learning about the mechanics of such libraries is unnecessary. Many software developers will argue that asking a candidate to reverse a binary tree is pointless, since it never comes up in the day-to-day job, so maybe the same can be said for utility libraries.

I’m still trying to figure out what kinds of open source are worth writing in this new era (hint: ones that an LLM can’t just spit out on command), and where education is the most lacking. My current thinking is that the most value is in bigger projects, more inventive projects, or in more niche topics not covered in an LLM’s training data. For example, I look back on my work on fuite and various memory-leak-hunting blog posts, and I’m pretty satisfied that an LLM couldn’t reproduce this, because it requires novel research and creative techniques. (Although who knows: maybe someday an agent will be able to just bang its head against Chrome heap snapshots until it finds the leak. I’ll believe it when I see it.)

There’s been a lot of hand-wringing lately about where open source fits in in a world of LLMs, but I still see people pushing the boundaries. For example, a lot of naysayers think there’s no point in writing a new JavaScript framework, since LLMs are so heavily trained on React, but then there goes the indefatigable Dominic Gannaway writing Ripple.js, yet another JavaScript framework (and with some new ideas, to boot!). This is the kind of thing I like to see: humans laughing in the face of the machine, going on with their human thing.

So if there’s a conclusion to this meandering blog post (excuse my squishy human brain; I didn’t use an LLM to write this), it’s just that: yes, LLMs have made some kinds of open source obsolete, but there’s still plenty of open source left to write. I’m excited to see what kinds of novel and unexpected things you all come up with.